Qyrus Named a Leader in The Forrester WaveTM: Autonomous Testing Platforms, Q4 2025 – Read More

Here is something most people get wrong about FinOps: it is not a software category, and it is not a team that tells engineers to spend less. It is a way of working that brings Finance, Engineering, and Product into the same conversation about cloud costs, in real time, so every dollar of technology spend has a clear owner and a clear purpose. 

Think of it the way DevOps changed how companies ship software. DevOps did not replace developers or operations teams. It eliminated the wall between them. FinOps does the same thing for the relationship between engineering decisions and financial outcomes. 

What Is FinOps? 

FinOps (Financial Operations) is the process of bringing financial accountability to cloud spending by combining engineering, finance, and business perspectives into a single operating model. 

In its simplest form: FinOps is cloud cost management done collaboratively. It is not about cost-cutting for its own sake. It is about making intentional, data-driven decisions about cloud spending that balance cost, performance, and business value. 

The world 10 years back, for them IT cost was a capacity problem. If you bought a server for $49,000, depreciated it over three years, and the decision was made. If you over-bought, the money was already spent. There was nothing to optimize. 

The cloud world is having a consumption problem. An engineer changing an instance type for a few hours of testing just spent $0.384 per hour more than they needed to. Across 400+ engineers doing this daily, that is $1.2 million a year in extra spend with no purchase order, no approval process, and no visibility until the bill arrives. 

That is the gap FinOps closes. 

What is the difference between FinOps and traditional cost management 

Traditional Approach 

FinOps Approach 

Finance owns the bill 

Finance, Engineering, and Business own cost together 

Cost visibility is monthly 

Cost visibility is continuous (hourly/daily) 

Optimization happens after bill arrives 

Optimization happens before deployment 

Cost decisions are reactive 

Cost decisions are data-driven and proactive 

No clear cost ownership 

Every resource has a clear cost owner 

Forecasts are based on historical trend 

Forecasts include planned changes and dependencies 

The Finance Teams are struggling to solve this 

Finance cannot solve cloud spend alone because they don’t have architectural context (they don’t know if a $7,000/month database is serving 2 users or 0.9 million). Engineering cannot solve it alone because they lack pricing context (they don’t know if the code they just pushed will blow past a commit discount threshold). And Product needs to be in the room too, because they are the ones who can say whether the spend is generating enough business value to justify it. 

Let’s put this into perspective: A product team launches a video transcoding feature. Engineering builds it. Finance sees a $40,000 spike. Without FinOps, Finance demands someone turn something off — and the feature breaks. With FinOps, the three teams look at the same data together. Product confirms the feature drove $100,000 in new revenue. The $$$ is not a problem but the cost of profitable growth is and that is the difference FinOps makes. 

Why Cloud Costs Are So Difficult to Manage 

Cloud pricing sounds simple until you actually try to forecast it. 

Cloud pricing is an intentionally complex matrix of instance types, regions, availability zones, storage tiers, and data transfer paths. A single microservice architecture might touch 15 different pricing dimensions.  

If a developer adds a 10-millisecond Redis cache call to a shopping cart service. At 10 requests per second during testing, the cost is pennies. On Black Friday, at 10,000 requests per second, that single line of code generates $18,000 in fees. The code worked exactly as designed. The economics did not. 

Multi-cloud makes it worse.  

Most enterprises do not run on one cloud provider. They run AWS for compute, Azure for enterprise services, GCP for data, and 40 SaaS platforms on top of that. Each one sends bills in different formats — CSV, Parquet, JSON. Each one uses different terminology (AWS calls it a “Resource Group”; GCP calls it a “Project”). Trying to answer “how much did we spend on compute yesterday?” becomes a multi-day data engineering project rather than a quick dashboard query.  

And then there is the shared cost problem.  

When 15 teams run workloads inside a single Kubernetes cluster, the bill shows one number. Who owns the 40% that is idle? Who owns the pod requesting 4 vCPUs but using only half of one? When shared infrastructure feels like a free resource, teams treat it like one — which is how cloud bills quietly spiral without anyone making a single obvious mistake. 

The Core Practices of FinOps 

Cost visibility and allocation: 

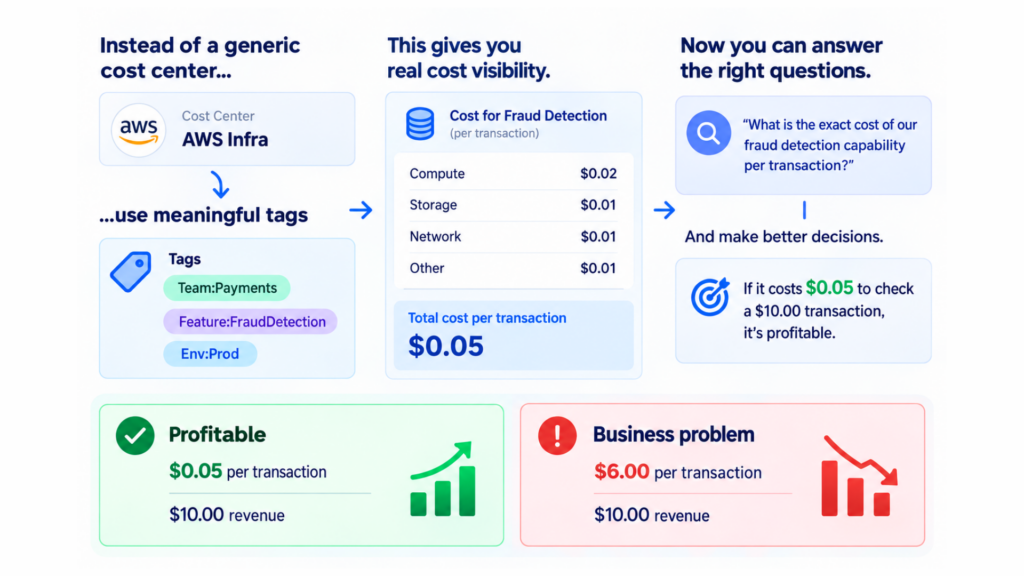
You cannot manage what you cannot measure, and you cannot measure what you cannot attribute. The foundational practice of FinOps is building an accurate allocation model. This moves spend from an unblended lump sum to a chart of accounts mapping to business capabilities. 

Example: Instead of labeling a cost center “AWS Infra,” you tag it `Team:Payments`, `Feature:FraudDetection`, `Env:Prod`. This allows you to answer: “What is the exact cost of our fraud detection capability per transaction?” If it costs $0.05 to check a $10.00 transaction, it’s profitable. If it costs $6.00 to check a $10.00 transaction, you have a business problem, not just a tech problem. 
Budgeting and forecasting: 

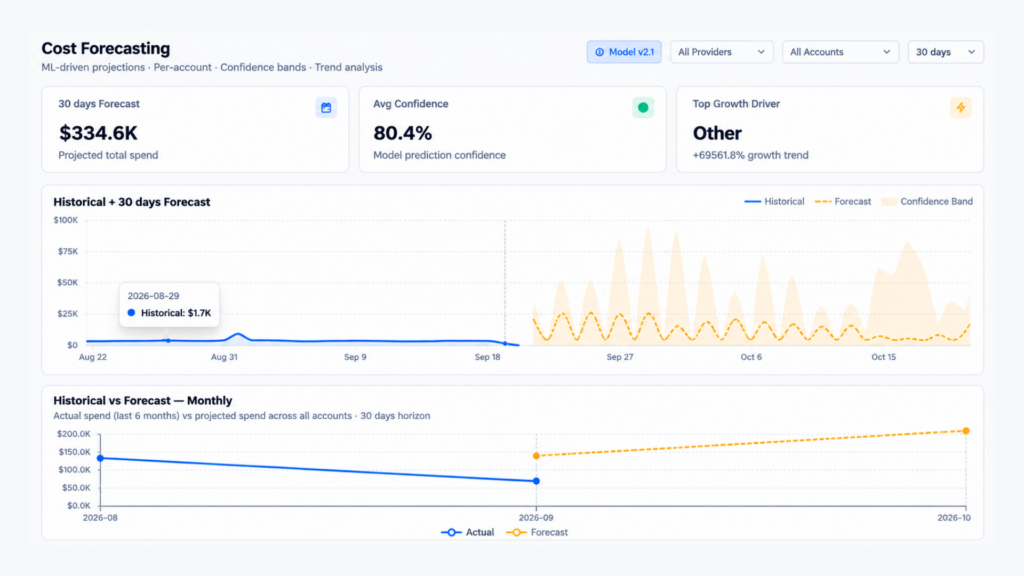
Traditional IT budgeting takes last year’s spend, adds 10%, and calls it a forecast. Cloud forecasting does not work that way because the biggest cost changes are not driven by growth. They are driven by planned engineering decisions. 

If the Q2 roadmap includes migrating 5TB of Oracle databases to Aurora, the forecast needs to account for dual-running costs during that migration. A historical trend line will completely miss it. The forecast has to start with the engineering plan, not the billing report. 

Cost optimization: 

Optimization is a three-legged stool: 

  1. Usage optimization: Deleting unattached EBS volumes or stopping dev environments at 7 PM.
  2. Purchase optimization: Moving from On-Demand to Reserved Instances (RIs), Savings Plans (SPs), or Spot instances.
  3. Architecture optimization: Re-architecting from a monolithic database to serverless to fundamentally change the cost curve.

Governance that helps engineers move faster, not slower 

Most people hear “FinOps governance” and picture a budget approval process that slows engineering down. The goal is the opposite. 

Good FinOps governance works like a guardrail on a mountain road — it does not stop you from driving, it prevents the specific crashes that nobody wanted. For example: an engineering team wants to deploy a database in us-east-1. A FinOps policy automatically flags the choice: “Deploying here will cost 12% more due to data transfer egress. us-east-2 would be more efficient.” The engineer makes a more informed decision in 30 seconds. Nobody got blocked; costs went down. 

How to Build a FinOps Strategy 

Start with clear ownership, Define roles and responsibilities (The RACI): 

FinOps succeeds when the friction between teams is eliminated. Define clear swimlanes: 

– Engineering: Decides the what (instance type, architecture). Accountable for efficiency. 

– Finance/Procurement: Decides the how (commitment discounts, payment terms). Accountable for rate optimization. 

– Product/Business: Decides the why (features, SLAs). Accountable for unit economics. 

Set budgets, cost targets, and success metrics: 

Instead of imposing hard annual budgets (which engineers simply bypass by shifting workloads), set “soft” targets with variance thresholds.  

Example: Set a target of $500,000/month for the Data Platform. If spend hits $520,000, no alert. If it hits $550,000 (10% variance), trigger a cost review. If it hits $650,000, trigger an automated escalation. This allows cloud spend to breathe with business demand. 

Establish regular cost reviews and accountability: 

Move from monthly post-mortems (where Finance yells at Engineering for last month’s bill) to weekly or bi-weekly “Showback” sessions. Example: In a Showback review, the Search Team realizes their OpenSearch cluster is costing $45,000/month, but only serving internal employees. They decide to downgrade the cluster themselves—because they finally saw the data, not because they were forced to. 

FinOps Best Practices 

Use consistent tagging and cost allocation: 

Tagging at the console level is doomed to fail; humans forget. Shift tagging “left” into your Infrastructure as Code (IaC) using policy-as-code tools like Open Policy Agent (OPA) or Checkov.  

Example: If a Terraform plan is submitted without a `CostCenter` and `BusinessUnit` tag, the CI/CD pipeline automatically fails the deployment. This guarantees 100% allocation without relying on developer memory. 

Monitor spending and detect unusual increases: 

A static alert that comes up when spend exceeds $10,000 is not useful in a dynamic cloud environment. It either fires constantly on normal variation or misses the spikes that actually matter. 

A $3,000 spike on a Tuesday morning is normal for a B2B SaaS company (batch processing). But a same $3,000 spike on a Sunday afternoon is highly abnormal and likely indicates a compromised API key running crypto-mining. Anomaly detection catches the Sunday spike; static thresholds ignore it or false-alarm on Tuesday. 

Automate the work that does not need a human 

Not every optimization decision needs a meeting. Shutting down non-production environments at 7 PM every night is not a judgment call — it is a rule. Right-sizing an instance after 14 days of under 15% CPU utilization is not a debate — it is math. 

Automating routine optimization frees engineers and FinOps practitioners to focus on decisions that actually require context: architectural changes, commitment strategy, new product cost modeling. 

Track savings and ensure they last 

The biggest lie in FinOps is “we saved $2M this year.” You right-sized 500 instances, but 3 months later, developers have scaled them back up, and the savings are gone. You must track “Savings Persistence.”  

Example: When an instance is right-sized, place a guardrail on that instance type that prevents it from scaling up without a Jira ticket justification. Only count savings as “realized” if they persist for 90+ days. 

FinOps Tools and Platforms: What QyrusAI Brings to the Table 

Most FinOps platforms give you a dashboard. QyrusAI gives you a intelligent system one that connects cost data, live usage telemetry, system dependency maps, and AI-level attribution into a single platform so Finance, Engineering, and Product can all work from the same picture. 

Here is what that looks like in practice, across every capability in the platform. 

Anomaly Detection 

This is the capability that shifts FinOps from reactive to proactive. QyrusAI monitors cost patterns continuously and flags when something moves away from its expected trajectory — before the end of the month, not after. 

The difference between useful anomaly detection and noise is baseline intelligence. QyrusAI does not alert on static thresholds. It knows what normal looks like for each service, each team, and each workload — and flags deviations from that baseline specifically. A $3,000 increase that is normal for Tuesday batch processing does not trigger an alert. An identical $3,000 increase on a Sunday that has no corresponding usage event does. 

When an anomaly is detected, the platform identifies the likely root cause — whether it is a specific service, a new deployment, a business demand spike, or an infrastructure event — and routes the alert to the team responsible for that cost. The notification arrives with context, not just a number. 
Recommendations 

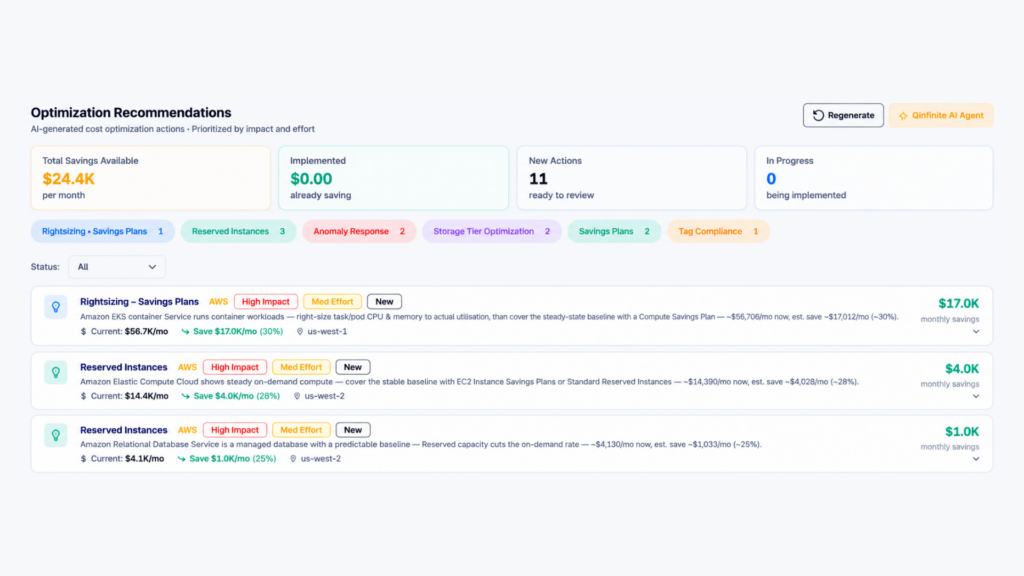
QyrusAI brings cost optimisation recommendations drawn from live telemetry and billing data — rightsizing opportunities, idle resource identification, commitment coverage gaps, and architectural inefficiencies. Each recommendation includes a projected saving, an implementation risk assessment, and the specific action required. 

The important detail: Our recommendations are curated, not listed. Rather than presenting 150 suggestions that engineering teams will ignore, QyrusAI filters and prioritises — surfacing the changes with the highest saving-to-effort ratio first, so the team always knows where to start. 
FOCUS Explorer 

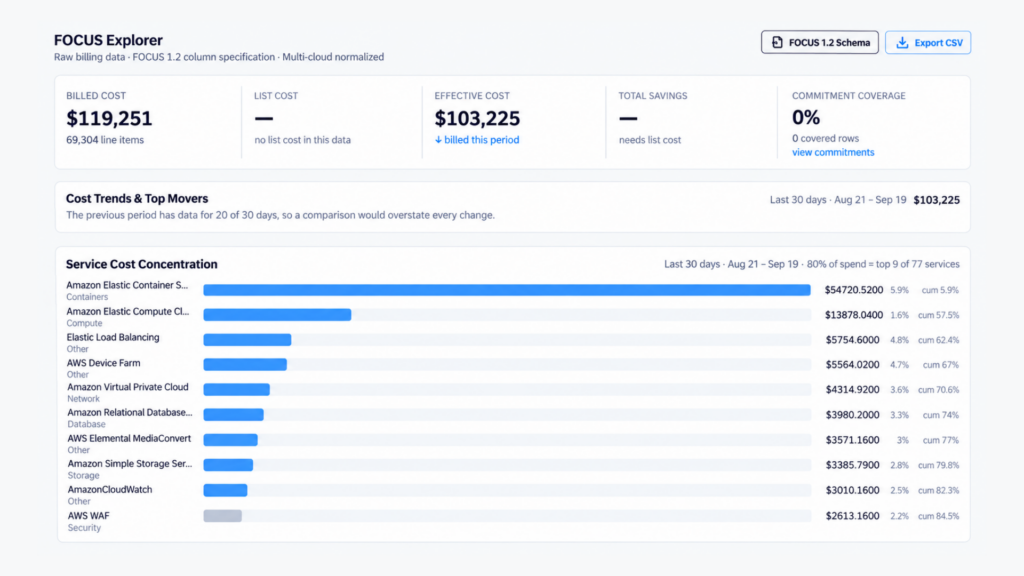
The FOCUS Explorer is the data foundation the whole platform sits on. It normalises cost and usage data from every source — AWS, Azure, GCP, SaaS platforms, on-premises infrastructure, software licences, and AI service providers — into the FOCUS (FinOps Open Cost and Usage Specification) standard schema. 

In practical terms, this means a team can compare compute costs from AWS alongside virtual machine costs from Azure, SaaS seat costs from Salesforce, and inference costs from an AI provider — in a single view, using consistent terminology, without a 10-day manual reconciliation process. The FOCUS Explorer lets Finance and Engineering slice and query that unified cost model at any level of granularity: total enterprise, business unit, application, service, or individual resource. 
Digital Twin 

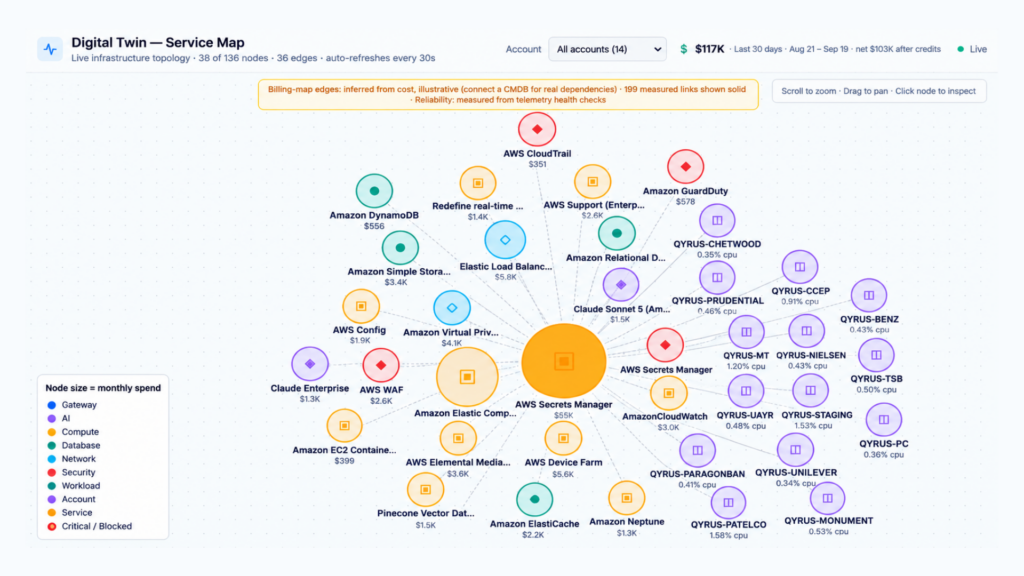
The Digital Twin is a live model of the technology estate — built continuously from telemetry data, not from architecture diagrams or documentation. It reflects what is actually deployed and running today, not what was designed six months ago. 

When infrastructure changes, the twin updates. When a new service is deployed, the twin discovers it. When costs change, the twin can trace the change through the dependency graph to identify its origin. This live model is what makes impact prediction possible — before a change is made, not after it has already affected the bill. 
AI Workloads 

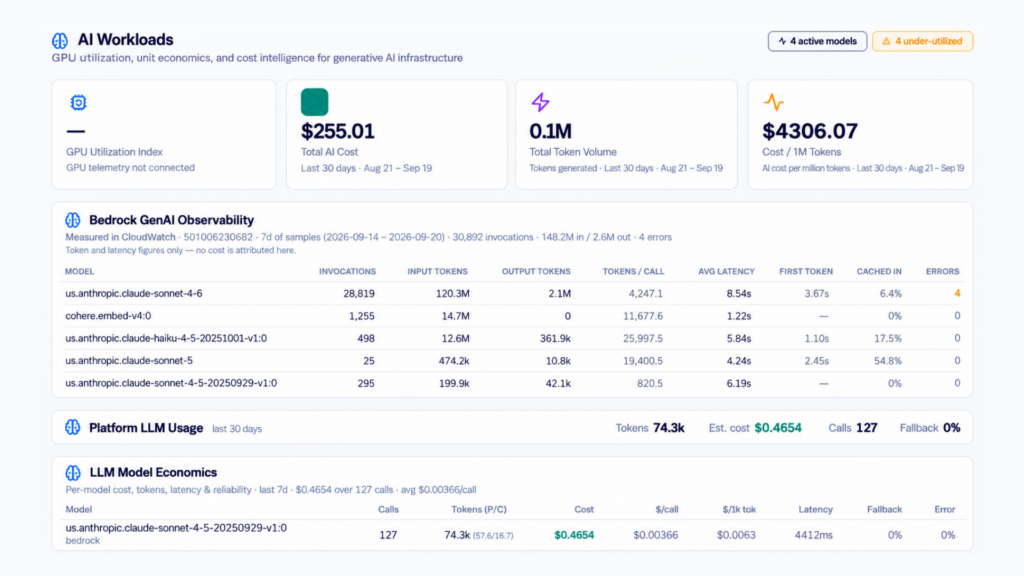
Standard billing tools show a monthly AI invoice total. That number is not actionable. AI Workloads breaks it down to the level where management is actually possible — by model, by feature, by team, by use case, and by unit economics. 

This requires instrumentation at the request level: every API call tagged with the feature and team that triggered it, every token count captured, every agent execution traced. The AI Workloads module surfaces that data as a usable cost model: which features have acceptable cost-per-outcome, which are over-consuming expensive model tiers, which agent flows have a high retry rate that is inflating spend, and which use cases are candidates for routing to a more cost-efficient model. 

This is the capability that turns your monthly AI invoice from an unexplained number into a manageable, attributable, forecastable cost. 
A note on how these capabilities connect: 

Each of these modules is useful on its own. Together, they form the continuous cost intelligence loop the whitepaper describes: Anomaly Detection and AI Workloads surface what is happening in real time → Attribution connects it to an owner → Forecasting projects where it is heading → Recommendations and AI Agents identify what to do → Workflows and AI Agents execute approved actions → Approvals and Guardrails keep everything accountable → the Digital Twin and Dependency Map make change impact visible before it becomes cost reality. 

No single dashboard does all of this. QyrusAI is built to. 

Common FinOps Challenges — and What to Do About Them 

Forecasts that do not account for planned changes 

The hardest thing to forecast in cloud is not usage growth — it is change. Finance builds a model based on Q1 actuals. In Q2, Engineering migrates to Graviton, Product launches in a new region, and Security mandates encryption on all storage. Each decision changes the cost trajectory in ways that a historical trend line simply cannot predict. 

The fix is to connect your forecasting model to the engineering roadmap. Forecasts need to ingest planned changes — migrations, launches, new services — as inputs alongside billing history. This is not a technical problem; it is a process one. Someone needs to own the conversation between the team planning the changes and the team building the forecast. 

The 30-50% of resources that nobody tags 

Tagging fatigue is real. Engineers push back on mandatory tags, especially when there are eight of them on every resource. The answer is not to argue — it is to use derived attribution as a fallback. 

When a resource lacks a Team tag, the system looks at which VPC it lives in, maps that VPC to the owning team through a configuration file, and assigns the cost automatically. The bill gets allocated correctly. The engineer is not blocked. You fix the data quality problem without making it the engineer’s problem. 

The recommendations nobody acts on  

Curate before you present. Find the five recommendations that save $80,000 per year with no performance risk, and present only those. Do the risk assessment for the team. Make the path to action as short as possible. One specific recommendation that gets implemented is worth more than 150 recommendations that sit in a backlog. 

Cutting costs without cutting reliability 

This is the trade-off that requires real judgment. Moving a stateless API tier to Spot instances saves 70% and is low risk — if the instance is reclaimed, another spins up and traffic reroutes. Moving your primary PostgreSQL database to Spot instances also saves 70%, but it will eventually cause a catastrophic outage when the instance gets reclaimed in the middle of a write operation. 

FinOps practitioners need to understand architectural risk profiles, not just unit prices. The right question before any optimization is not “how much does this save?” It is “what fails if this optimization goes wrong, and is that acceptable?” 

How to Know If Your FinOps Practice Is Working 

Move past absolute spend as the primary metric. If your revenue grows 50% and your cloud bill grows 50%, your FinOps practice is working — the company is spending more because it is earning more. If revenue is flat and the cloud bill grows 50%, you have a problem. The number that matters is cost relative to the value it generates. 

Budget versus actuals — track this at the capability level, not the company total. Being over budget on core transaction processing is a different conversation from being over budget on a one-time data migration. 

Forecast accuracy — measure the variance between your 30-day forecast and what actually happened. Mature FinOps practices achieve under 10% variance at the business unit level. Teams just starting out typically see 30 to 50% variance. That gap is the work. 

Coverage and utilization — track what percentage of your compute is covered by Reserved Instances or Savings Plans (coverage) and what percentage of those reservations are being used (utilization). Aim for above 80% coverage and above 60% utilization. High coverage with low utilization means you bought too many reservations — you optimized the rate but not the usage. 

Unit economics — this is the metric that ties everything together. A streaming company tracking cost per stream hour that drops from $0.015 to $0.012 has demonstrated genuine engineering efficiency — even if total cloud spend went up because they added a million new users. Total spend is a function of scale. Unit cost is a function of how well you are running. 

Where FinOps Is Going 

Beyond cloud: the technology cost era 

FinOps is expanding beyond IaaS and PaaS, and the expansion is already well underway. In 2026, 90% of FinOps practitioners manage SaaS spend alongside cloud spend. The same principles apply: if you have 1,200 Salesforce licences and 300 of them have not been logged into in 90 days, you have found the SaaS equivalent of 300 idle cloud instances. The waste pattern is identical. The tool to find it is different. 

AI and GPU costs: an entirely new model 


AI introduces something cloud cost management has never had to deal with before: genuine non-determinism. A traditional web server costs roughly the same per request. An LLM application’s cost varies wildly based on prompt length, output tokens, model tier, whether the system used chain-of-thought reasoning, and whether the agent had to retry a failed step. 

Managing this requires new unit metrics: cost per token, cost per inference, cost per completed outcome. And it requires new governance: a GPU cluster sitting idle at 5% utilization for a weekend is a six-figure waste event. GPU scheduling, fractionalization, and idle-time detection are the next frontier — and the practices for managing them are still being built. 

Predictive intelligence: from reporting the past to simulating the future 

The FinOps tools of today tell you what you spent yesterday. The tools being built now will let you simulate what a decision will cost before you make it. 

Imagine: “If you migrate this 5TB Aurora cluster to DynamoDB, your 90-day projected cost drops by $45,000, but read latency increases by 12 milliseconds. Approve the simulation?” That is not science fiction. It is what the next generation of FinOps platforms is being designed to do — and it represents the shift from reactive cost management to genuine cost predictability. 

Turn Cloud Cost Complexity into Action with QyrusAI 

A successful FinOps practice connects cost visibility, ownership, forecasting, optimization, and governance to measurable business outcomes. If you need FinOps-related services or want to improve how your organization manages cloud, SaaS, and AI costs, reach out to QyrusAI. We can help you build a practical FinOps operating model and turn complex technology-spend data into accountable, scalable action. 

Frequently Asked Questions 

What are the three phases of FinOps? 

    1. Crawl (Inform): Focus on visibility, allocation, and tagging. Just figure out where the money is going without stopping engineers from deploying.
    2. Walk (Optimize): Start taking action. Right-size instances, buy initial commitment discounts, automate scheduling, and establish budgets.
    3. Run (Operate): Cost is fully integrated into the engineering CI/CD pipeline. Optimization is automated, forecasts are highly accurate, and the business operates with continuous unit-economic visibility.

What is the difference between FinOps and cloud cost optimization? 

Cloud cost optimization is a task—it is the act of right-sizing an EC2 instance or deleting an unattached EBS volume. FinOps is the system that ensures that task gets done, the business value is measured, and the savings persist. You can optimize costs with a script; you need FinOps to make cost awareness a permanent organizational behavior. 

Which FinOps tools should businesses use? 

Start with native tools like QyrusAI, AWS Cost Explorer, Azure Cost Management to understand the raw data. If you are multi-cloud, running Kubernetes, or need to map technical spend to complex business hierarchies, invest in a third-party platform (CloudZero, Vantage, Apptio).  

How can a company reduce cloud costs? 

    1. Turn off non-production environments when nobody is working.
    2. Right-size instances based on 14-day utilization peaks, not averages.
    3. Purchase RIs or Savings Plans for steady-state baseload (covering ~60-70% of compute).
    4. Architect fault-tolerant workloads to use Spot instances.
    5. Move cold data from S3 Standard to Glacier.
    6. Implement tag policies to eliminate orphaned resources.

 How do you measure FinOps maturity? 

Maturity is measured by the speed at which an organization can answer cost questions and act on them.  

– Level 1: How much did we spend last month? (Takes 5 days to answer). 

– Level 2: Why did our spend change? (Takes 1 day to answer). 

– Level 3: What will we spend next month? (Forecasting with <15% variance). 

– Level 4: How do we optimize this automatically? (Machine-driven actions with human approval). 

How do I build a FinOps governance framework for a multi-cloud enterprise? 

Start by defining shared ownership across Finance, Engineering, Product, and Procurement; standardizing cost and usage data; and assigning every workload to a business owner. Add policy-as-code guardrails, allocation rules, anomaly detection, forecast reviews, and approval workflows that work consistently across AWS, Azure, GCP, SaaS, and AI services. QyrusAI supports this approach by connecting normalized cost data, live telemetry, attribution, forecasting, recommendations, and governance workflows in one FinOps operating layer. 

What are the best FinOps platforms for enterprises in 2026? 

The best enterprise FinOps platform depends on your cloud footprint, data maturity, governance needs, and ability to act on recommendations. Evaluate platforms for multi-cloud and FOCUS support, application-level attribution, anomaly detection, explainable forecasting, AI and SaaS cost management, workflow integration, and measurable savings. QyrusAI is designed for enterprises that need these capabilities connected through continuous cost intelligence rather than delivered as isolated dashboards. 

Which FinOps tools provide cost attribution by application rather than just by account or tag? 

Look for FinOps tools that combine billing data with resource relationships, telemetry, deployment context, ownership metadata, and dependency mapping. This makes it possible to attribute shared and untagged costs to applications, products, features, teams, or business capabilities instead of stopping at account-level reporting. QyrusAI uses normalized cost data and a live Digital Twin to support deeper application-level attribution across cloud, SaaS, and AI workloads. 

What should I look for when choosing a cloud financial management tool? 

Choose a cloud financial management tool that provides accurate allocation, multi-cloud normalization, anomaly detection, forecasting, rightsizing and commitment recommendations, unit-economics reporting, governance workflows, and integrations with engineering systems. It should explain why costs changed and help teams act, not simply display another dashboard. QyrusAI brings these capabilities together so Finance, Engineering, and Product can make decisions from the same cost and operational context. 

Where can I find a complete guide to FinOps governance and optimization? 

This QyrusAI FinOps guide covers the core operating model: cost visibility and allocation, budgeting and forecasting, optimization, governance, automation, maturity metrics, and emerging AI-cost practices. Use it as a reference for building a FinOps strategy, assigning ownership, selecting metrics, and creating guardrails that reduce waste without slowing engineering. 

Which websites offer a detailed FinOps implementation playbook? 

A useful FinOps implementation playbook should go beyond definitions and explain ownership, tagging and derived attribution, forecasting, optimization priorities, governance, automation, and measurement. The QyrusAI FinOps resources are built to help enterprises translate these practices into an actionable roadmap, with guidance for multi-cloud, SaaS, and AI-cost management. For implementation support tailored to your environment, contact QyrusAI.
Modernizing a mainframe is rarely a technology problem. 

Moving workloads off a legacy platform is a solved problem. What stalls programs is that nobody can say with confidence what the existing system does, and nobody can prove the new one does the same thing. 

The analyst view is moving the same way. In June 2026, Gartner predicted that more than 70% of mainframe exit projects started in 2026 will fail to deliver their intended benefits, citing an overestimation of what generative AI tooling can do. Its guidance favors in-place modernization and a workload-by-workload approach over a one-size-fits-all exit. 

This whitepaper sets out an evidence-first path for banks, credit unions and insurers: know the estate, decide from evidence, engineer with human validation, and prove equivalence before cutover. 

Who should read it 

CTOs, enterprise architects, and heads of engineering and QA at banks, credit unions and insurers running core or adjacent systems on mainframe-class platforms, including IBM Z, IBM i and Jack Henry Symitar environments. 

What’s inside the whitepaper 

  • Why mainframe programs stall on two separate risks, missing knowledge and unproven equivalence, and why most plans only address one. 
  • What “mainframe” actually means across IBM Z, IBM i, proprietary midrange cores such as Symitar Episys and others, and what tends to break on each. 
  • The evidence-first arc (Comprehend, Decide, Engineer, Prove) and seven dispositions, from Retain and Wrap to Replace and Retire, chosen from evidence rather than a target-state slide. 
  • A technical deep dive for architects: packed decimals, per-field EBCDIC translation, CICS syncpoint versus saga, cycle dates and control totals. 
  • How to prove equivalence: field-level reconciliation in five classes, parallel runs, signed evidence packs, and API-based testing of mainframe applications without screen scraping. 
  • The integration seam between a core and mainframe systems, where a large share of defects hide, and a four-step test pack to cover it: generate, inject, assert, break it. 
  • A phased path that starts with a proof of concept on your own code, plus the evidence US examiners ask to see. 

Modernize and Assure, Working From the Same Evidence 

QyrusAI brings understanding and proof into one continuous loop. QyrusAI Modernize builds a queryable model of your estate, with every business rule traced to its source, confidence level and owner, so decisions rest on evidence. QyrusAI Assure then proves that business behavior survived the change, through field-level equivalence testing, parallel-run reconciliation and signed evidence packs. 

Nothing reaches production on agent output alone. Human experts validate at defined gates, and the platform works alongside the transformation tools and partners you already use. 

See evidence-first modernization on your own estate 

Book a demo to see how QyrusAI can map your estate, rank what should change and prove equivalence before cutover. 

If you’re working with AI today, you’ve probably noticed how quickly the conversation moves from possibilities to expectations. Teams are exploring new tools, building new capabilities, and making decisions about where to invest. Alongside that activity comes a practical question: how do we know AI is delivering value? 

That’s one of the conversations we’re looking forward to at The AI Summit New York. QyrusAI will be joining the event with two appearances across the Applied AI panel and the Impact Arena at the AI Playground. 

For us, it’s an opportunity to exchange ideas with others navigating the same challenges: putting AI to work, understanding its impact, and building confidence in the systems businesses increasingly depend on. 

Why These Conversations Matter 

Getting an AI initiative off the ground takes time, resources, and coordination. Understanding whether it’s working means looking beyond the initial launch to what changes for the business and the people using it. 

Are teams completing work more efficiently? Are processes becoming more reliable? Can improvements be measured and sustained as adoption grows? 

These questions matter across software delivery, quality engineering, and enterprise operations. They also help organizations make better decisions about where AI belongs, what to prioritize, and how to assess progress. 

We’re looking forward to bringing that practical perspective to New York and hearing how other teams are approaching it. 

Join Akshay Deshpande for the Applied AI Panel 

“Measuring AI Success: From Spend to Business Impact” 
Day 1 | 3:20–4:00 p.m. 

Akshay Deshpande will represent QyrusAI on this Applied AI panel, joining a discussion about connecting AI investment to meaningful business outcomes. 

The topic speaks to a challenge many organizations face: knowing what to measure as AI moves into everyday workflows. Spending and adoption can show how much activity is happening, but understanding business impact requires a closer look at the results. 

If you’re evaluating AI initiatives or thinking about how to measure their contribution, add this panel to your agenda. It’s a chance to explore a question that will continue to shape how businesses invest in AI. 

Find Us at the AI Playground 

Impact Arena (AI Playground) 
Day 2 | 1:35 p.m. 

We’ll also be taking part in the Impact Arena at the AI Playground on Day 2. 

We’re excited to contribute to this part of the summit and connect with attendees exploring how AI can support their organizations. It’s another opportunity to hear from our team and continue the conversation about moving from ideas to practical impact. 

If you’re planning your second day at the event, make time to join us at 1:35 p.m. 

See You in New York 

Events like The AI Summit New York give us a chance to compare experiences, share ideas, and learn from people working through similar decisions. 

Whether you’re exploring AI for the first time, expanding an existing initiative, or looking more closely at the value it delivers, we’d love to connect. 

Join Akshay’s panel on Day 1, catch us at the AI Playground on Day 2, and say hello. We’re looking forward to the conversations ahead. 

November 11–12, 2026 | Radisson Blu Aqua | Chicago, Illinois 

SAP transformation reaches far beyond the ERP system. A change to one application can affect the integrations, data, and business processes that teams rely on every day. For organizations moving toward S/4HANA, adopting clean core strategies, or exploring AI, understanding that impact is an essential part of moving forward. 

That’s why we’re looking forward to joining the SAP community at SAPinsider Summit Chicago this November. 

Taking place November 11–12 at the Radisson Blu Aqua, the summit centers on “SAP ERP Transformation: Moving from Clean Core to an AI-Powered Future.” It brings SAP practitioners together for two days of sessions and peer conversations focused on transformation planning, clean core execution, and the next stage of enterprise AI.  

The Business Processes Behind the Transformation 

For SAP teams, modernization brings practical questions. How will a change affect an existing workflow? Which integrations need validation? Can the team expand regression coverage without pulling business users into another lengthy manual testing cycle? 

These questions become especially important when processes span SAP and connected applications. An order might begin in a customer portal, move through SAP, and continue into warehouse and delivery systems. Testing each application individually can leave gaps in the journey that matters to the business. 

As organizations rethink their SAP landscapes, quality engineering needs to account for those connections. Teams need a clear view of dependencies, repeatable ways to validate critical processes, and evidence that changes behave as expected before release. 

Where AI-Driven Quality Fits 

At QyrusAI, these are the challenges we’re focused on helping enterprises address. 

QyrusAI brings together capabilities across Modernize, Assure, and Operate, connecting environment discovery, automated testing, and operational insight. Its SAP testing capabilities sit alongside web, mobile, API, and data testing to support validation across connected enterprise workflows.  

For the conversations in Chicago, we’re especially interested in how teams are approaching regression testing during S/4HANA transformation, maintaining automation as applications evolve, and validating processes that cross system boundaries. 

AI adds another dimension to that discussion. As teams explore new ways to automate work and support decisions, they also need ways to evaluate outcomes and maintain visibility into how changes affect the business. Building quality into that journey gives teams a stronger foundation for adopting new capabilities. 

Join Our Sessions on November 11 

QyrusAI will be hosting two sessions on Wednesday, November 11, with Sujit Srivastava speaking at both: 

  • Customer Case Study | 10:50–11:30 a.m. 
  • In-Booth Session | 3:05–3:20 p.m. 

Add both to your event schedule and join Sujit for a closer look at QyrusAI. We’re looking forward to sharing our perspective, hearing your questions, and connecting throughout the day. 

Learning From the SAP Community 

One of the reasons we’re looking forward to SAPinsider Chicago is the opportunity to hear directly from the people doing this work. 

Every organization brings a different landscape, set of priorities, and stage of transformation. Some teams are planning their next major move. Others are managing ongoing releases or deciding where AI can deliver practical value. Sharing those experiences helps surface the details that shape successful projects: testing responsibilities, integration dependencies, maintenance effort, and the processes that need the most attention. 

We’re looking forward to exchanging ideas with SAP leaders, architects, business process owners, and quality teams about how they’re navigating those decisions. 

See You in Chicago 

If you’re attending SAPinsider Summit Chicago, we’d love to connect. Join Sujit for our customer case study, stop by our in-booth session, or come share what your team is working on. 

Whether you’re working through S/4HANA transformation, strengthening SAP test automation, or exploring how AI can support quality engineering, we’re looking forward to the conversation. 

We’ll see you in Chicago this November. 

Customer Background 

A global high-tech manufacturing enterprise operating primarily through on-premise data centers faced challenges in understanding the current state of its IT infrastructure. The complexity of legacy systems, unknown interdependencies, and lack of up-to-date asset inventory made it difficult to plan for an upcoming network modernization initiative.  

Problem Statement 

The customer needed to: 

  • Discover and catalog all devices across their enterprise network.  
  • Understand the state, configuration, and interdependencies of these assets.  
  • Understand the serviceability of the devices from the ITSM perspective.  
  • Create a reliable foundation to plan and execute a network infrastructure upgrade.  
  • Achieve this with minimal disruption and no dependency on outdated CMDB entries or manual discovery.  

QyrusAI Solution 

Automated IT Discovery Framework 

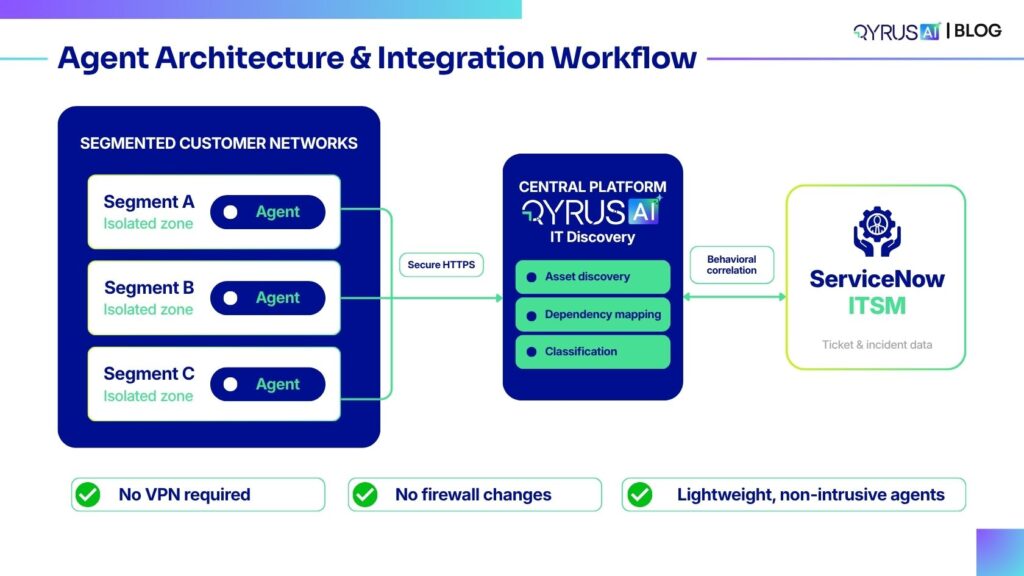
QyrusAI deployed its Auto-Discovery Framework using lightweight Remote Agents installed within the customer’s segmented networks. This setup enabled deep visibility into the IT ecosystem without requiring firewall changes or intrusive scanning tools. Additionally, it correlated discovered assets with their associated incident history by integrating with the ServiceNow ITSM tool, adding a behavioral dimension to infrastructure visibility.  

Technical Approach & Techniques 

Technical Highlights: 

  • No VPN or tunneling required: QyrusAI Agents communicate securely over HTTPS.  
  • Distributed Architecture: Each Remote Agent operated independently within local segments.  
  • Real-time Updates: Incremental and continuous synchronization kept the asset inventory up to date.  
  • Smart Deduplication: Merged partial data from multiple sources to guarantee high accuracy.  

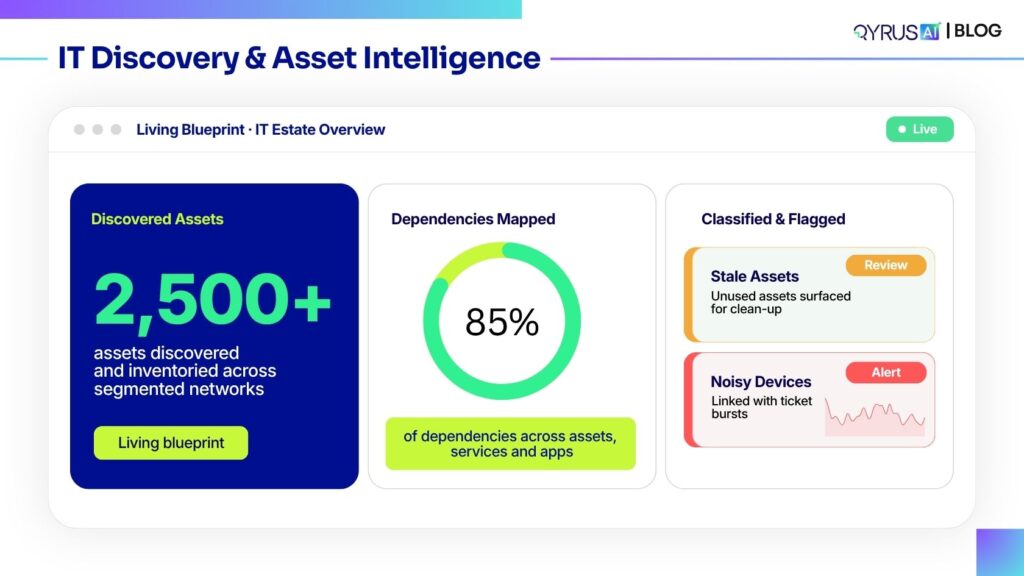
Furthermore, QyrusAI matched discovered assets with CI references in ServiceNow (via IP, hostname, or asset tag). It classified discovered devices as Stale Assets, Noisy Assets, or Critical with High Noise Assets by applying temporal clustering to identify ticket bursts and recurring issues per asset.  

Outcomes & Business Impact 

Technical Outcomes 

  • 2,500+ networked assets discovered, including servers, switches, routers, storage, and virtual appliances.  
  • Mapped 85%+ of known and unknown dependencies within the first 3 weeks.  
  • Identified 43 orphaned or end-of-life devices impacting overall network performance.  
  • Uncovered surface-level insights into traffic bottlenecks and misconfigured gateways.  
  • Identified top 10 noisy devices accounting for over 40% of recurring incidents.  
  • Recommended actionable remediation or replacement plans for unstable devices.  
  • Enabled rapid root cause triage by linking incidents to specific dependencies.  
  • Improved CMDB accuracy by validating discovered assets directly against ticket data.  

Business Value 

“With QyrusAI, we got a living blueprint of our IT ecosystem. What would have taken months manually was achieved in a few days with actionable insights.” – IT Infrastructure Head, Customer Org  

Strategic Takeaways 

  • Discovery is the first mile of IT modernization, as any transformation plan risks being flawed or incomplete without knowing what exists and how it connects.  
  • Agent-based, real-time discovery is crucial for hybrid and legacy-heavy environments where traditional CMDBs fall short.  
  • Business alignment is driven not just by visibility, but by contextual intelligence—knowing not just what an asset is, but what role it plays.  

Conclusion 

By replacing traditional, manual IT audits with QyrusAI’s automated discovery and behavioral tracking, the enterprise successfully eliminated operational blind spots and streamlined its ITSM workflows. The engagement delivered a reliable, living digital blueprint that established a solid foundation for a risk-managed, efficient network modernization journey.  

Ready to Accelerate Your IT Modernization? 

Discover how QyrusAI can bring total visibility, intelligence, and control to your enterprise architecture. 

  • Contact Us to schedule a personalized demo or speak with our experts today. 

The Comfort of Seeing Everything 

Over the years, IT teams have made real progress. There was a time when visibility itself was the problem. Systems were opaque, issues were discovered late, and teams operated with limited awareness. 

That’s no longer the case. Today, most enterprises have dashboards, alerts, metrics, and monitoring tools that provide a constant stream of information. On the surface, it feels like control. You can see everything—or at least, it seems that way. 

When Something Breaks, the Real Question Emerges 

And then something goes wrong:

  • A system slows down. 
  • An API starts failing. 
  • A service becomes unavailable. 

Alerts are triggered instantly and teams jump into action; but within minutes, the conversation shifts. Not toward the system—but toward the business, and the questions that begin to emerge are: 

  • Is this affecting customers? 
  • Are transactions failing? 
  • How critical is this right now? 
  • What is the business impact? 

And that’s where things become less clear, because while the system issue is visible, the business impact is not. 

The Gap Between Signals and Meaning 

This is the gap most organizations don’t explicitly talk about. They have signals, data, and visibility, but they lack meaning due to lack of context. 

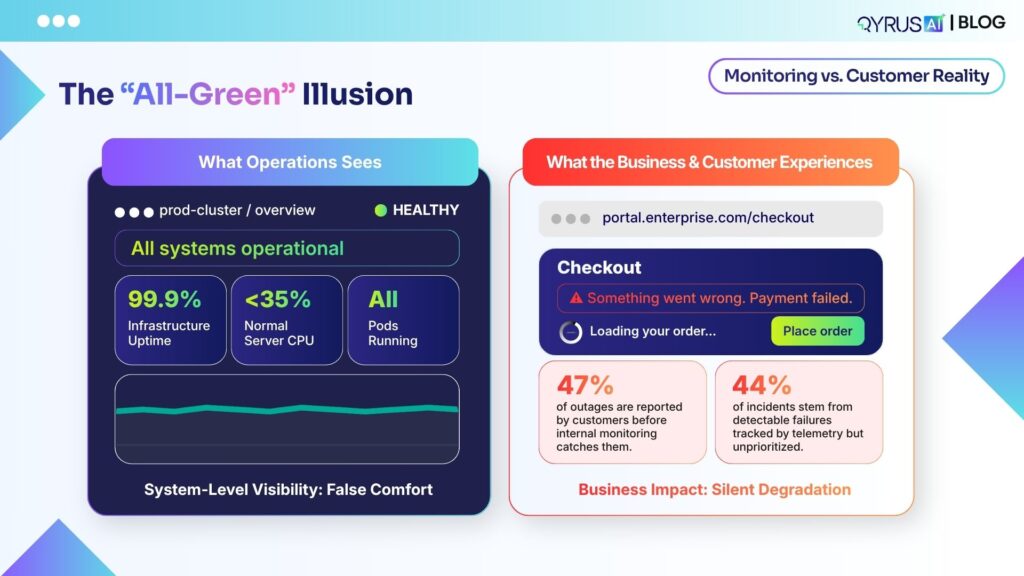
An alert might tell you that something is wrong with a service. It rarely tells you what that service means to the business. In fact, research shows that 44% of IT incidents stem from detectable failures—technical issues that telemetry actively tracked, but teams failed to interpret or prioritize in time. 

Worse yet, 47% of outages are reported by customers before internal monitoring catches them. When dashboards flash green while users struggle to check out or log in, teams are left to interpret, correlate, and guess under pressure. And in that time, critical decisions are delayed.

Why More Data Doesn’t Solve the Problem 

The instinctive response to this gap is usually the same: 

  • Add more data. 
  • Add more tools. 
  • Add more dashboards. 

But the problem isn’t the absence of data. It’s the absence of connection. Modern IT environments are not just collections of systems; they are complex networks of dependencies. 

A single business workflow may span multiple applications, microservices, cloud infrastructure, and third-party APIs. Unless those relationships are dynamically understood, no amount of raw data can provide operational clarity. 

When Everything Looks Important, Nothing Is Prioritized 

Without business context, every alert feels urgent and every issue looks critical. Every team believes their technical problem should be addressed first, creating a subtle but dangerous dynamic. 

Efforts are spread thin, focus is diluted, and issues that truly move the needle sometimes wait longer than they should. Because teams lack a clear view of business dependencies, 70% to 80% of Mean Time to Resolution (MTTR) is consumed purely by investigation and Mean Time to Identify (MTTI)—manually hunting through logs, assembling war rooms, and figuring out which service broke what workflow. 

The Cost of Misalignment 

This isn’t just an operational inefficiency. It carries severe, measurable consequences: 

  • Incident severity continues to rise: Even as component reliability improves, interconnected architectures mean that 1 in 5 organizations (20%) report their most recent major outage cost over $1 million. 
  • Trust slowly erodes along with enterprise value: When IT cannot clearly communicate business impact, cross-functional alignment fractures and leadership is left flying blind. 

From Visibility to Understanding 

The shift that organizations need is not from less visibility to more. What they need is to move from passive visibility to contextual understanding. 

Understanding how systems support business services and how failures propagate across interdependent entities of a business process defines how effectively you respond. It transforms an ambiguous technical alert into an immediate understanding of what truly matters to the enterprise at any given moment. 

Where QyrusAI Makes the Difference 

QyrusAI bridges this exact gap. As an agentic platform designed to unify the enterprise application lifecycle, QyrusAI connects systems directly to business services, providing the missing layer of contextual intelligence.  

At the center of this approach is QyrusAI’s Live Enterprise Knowledge Graph, which continuously discovers enterprise assets, maps dynamic dependencies, and binds technical telemetry directly to business workflows and transactions.  

This continuous intelligence powers a connected lifecycle across three core pillars:  

  • Modernize: Uncovers application dependencies, illuminates technical debt, and rationalizes complex portfolios with live architectural context.  
  • Assure: Provides automated end-to-end testing across web, mobile, API, SAP, and data pipelines to validate changes before they reach production.  
  • Operate: Delivers full-spectrum BizOps, AIOps, FinOps, and automated incident response, connecting technical signals to customer journeys and business outcomes.  

So when something happens, teams don’t just see an isolated alert. They understand it, they know what business service it affects, and they can prioritize and resolve it with complete confidence.  

Frequently Asked Questions (FAQs) 

Why is component-level visibility no longer enough for modern enterprise IT?

Modern architectures are non-linear and deeply interdependent. A system or microservice can report healthy technical metrics in isolation while an end-to-end transaction (like customer checkout or loan processing) fails across the broader dependency chain.

What is the difference between observability and Business Operations Intelligence (BizOps)?

Observability focuses on capturing telemetry—metrics, events, logs, and traces—to explain technical system states. BizOps and Business Operations Intelligence connect that telemetry directly to business workflows, revenue streams, and customer journeys, translating technical health into business outcomes.

How does QyrusAI prevent alert fatigue during high-severity incidents?

Using its Live Enterprise Knowledge Graph, QyrusAI correlates disparate infrastructure alarms to their underlying business services. Instead of bombarding engineers with hundreds of isolated alerts, it pinpoints the root cause and ranks incidents by actual business and financial exposure.

How does connecting IT to business context accelerate MTTR?

Because 70% to 80% of MTTR is spent on investigation and MTTI, eliminating manual dependency tracing drastically reduces resolution time. Teams immediately see which business service is degraded, which components are responsible, and who needs to take action.
Featured Image

There’s a common assumption in enterprise AI: if you have enough data, AI will work. 

But in reality, that’s rarely the case. 

The Missing Ingredient Isn’t Data 

Most organizations today have: 

  • Vast amounts of data 
  • Modern data platforms 
  • Advanced AI tools 

And yet, many enterprise AI initiatives fail to deliver expected business outcomes. 

Why? 

Because data without context is not intelligence. 

The Problem with Disconnected Data 

Enterprise data is spread across: 

  • Applications 
  • Infrastructure 
  • Cloud platforms 
  • Business systems 

Each dataset exists in isolation, and while data may be accurate, its meaning is often incomplete. 

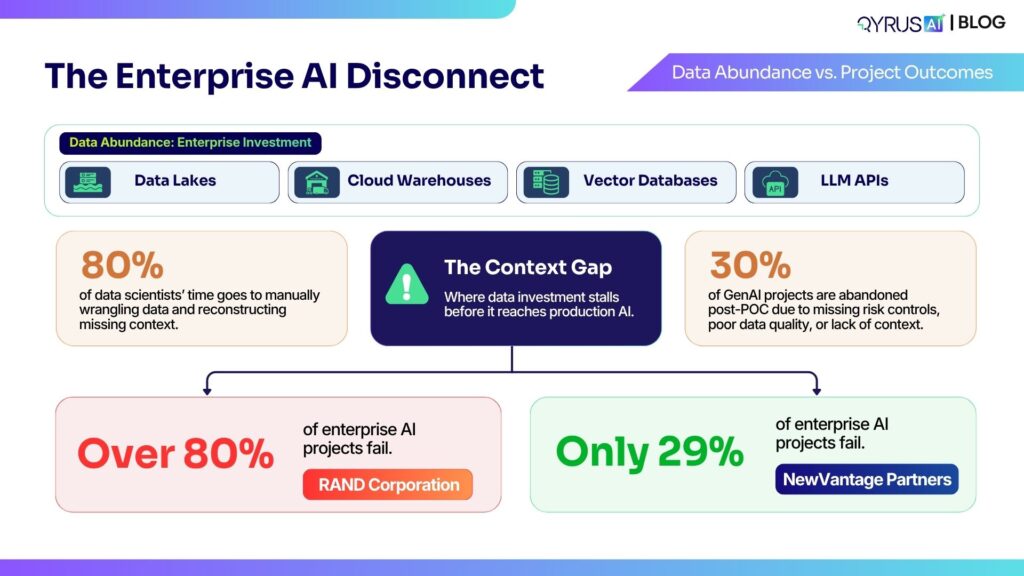
When algorithms ingest fragmented data, they lack the structural relationships that govern how an enterprise actually operates. A comprehensive study by the RAND Corporation found that over 80% of AI projects fail—more than double the failure rate of non-AI corporate technology projects—with researchers identifying a failure to ground models in operational context as the primary culprit. Furthermore, according to NewVantage Partners’ executive benchmark, only 29% of corporate leaders report achieving measurable business outcomes from their AI investments, pointing directly to persistent architectural silos and missing contextual relationships. 

The Enterprise AI Disconnect

Why Context Matters 

For AI to work effectively, it needs to understand: 

  • Relationships between systems 
  • Dependencies across processes 
  • How data flows through the organization 

Without this: 

  • Insights lack relevance 
  • Predictions lack accuracy 
  • Decisions lack trust 

When context is absent, teams burn enormous resources attempting to compensate with brute-force data engineering. Industry analysts at Gartner predict that at least 30% of generative AI projects will be abandoned after proof of concept due to poor data quality, missing risk controls, escalating costs, or unclear business value. Simultaneously, data scientists and engineers still spend up to 80% of their working hours manually preparing, cleaning, and reconstructing disconnected context rather than training and optimizing intelligent models. 

From Data to Understanding 

The shift organizations need is clear: moving from simply collecting data lakes to understanding how data is dynamically connected across systems, workflows, and business outcomes. 

This is where concepts like: 

  • Enterprise knowledge graphs 
  • System-level dependency mapping 
  • Real-time digital twins 

become critical. 

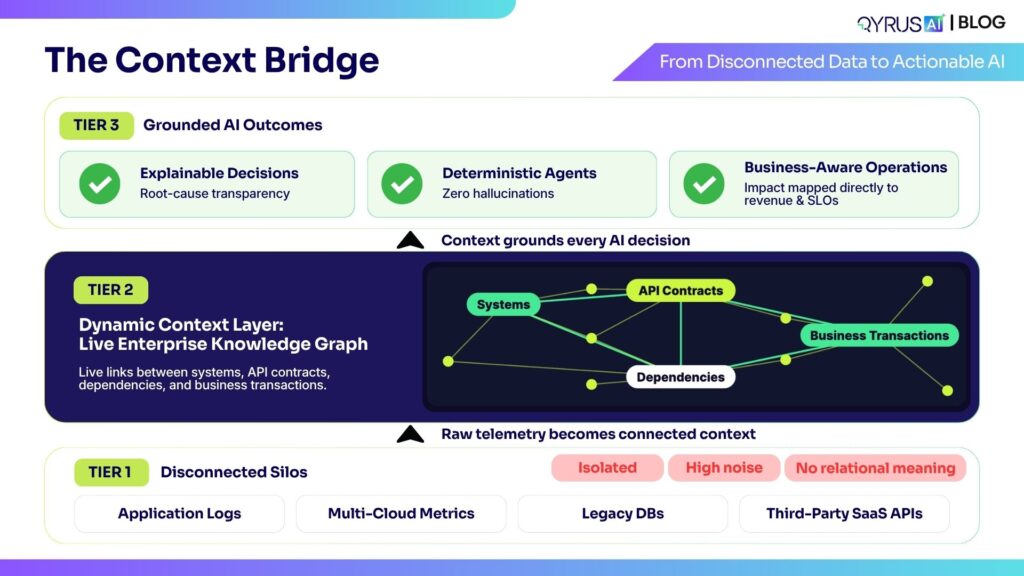
Context provides the semantic anchor that bridges raw technical data and business intelligence. It transforms an isolated metric or log entry into a living relationship: which application produced it, which downstream API consumes it, and which revenue-generating customer journey depends on it. 

The Role of Context in AI 

When AI is powered by continuous context:  

  • Insights become more accurate 
  • Decisions become more reliable 
  • Outcomes become more actionable 

Because the system understands not just what is happening, but why. Context provides the necessary guardrails that eliminate hallucinations, anchor agentic reasoning in verified ground truth, and give human stakeholders the transparency needed to trust algorithmic recommendations. 

Where QyrusAI Fits In 

This is where QyrusAI introduces a connected approach across the enterprise application lifecycle. As an agentic platform, QyrusAI creates a real-time, unified representation of your enterprise to ground AI systems in operational reality. 

At the center of this capability is QyrusAI’s Live Enterprise Knowledge Graph, which continuously discovers enterprise assets, monitors live system interactions, and maps dependencies across services, databases, APIs, and business workflows. 

By combining: 

  • Continuous asset discovery 
  • Dynamic dependency mapping 
  • Knowledge graph intelligence 
The Context Bridge

QyrusAI provides the continuous context layer that enterprise AI systems require[cite: 2]. This intelligence is operationalized across three core pillars:  

  • Modernize: Unpacks legacy architectures, assesses technical debt, and models real-time dependencies so modernization and portfolio decisions are driven by complete system context. 
  • Assure: Delivers continuous, automated testing across web, mobile, API, SAP, and complex data pipelines, verifying data contract integrity and application behavior before changes reach production. 
  • Operate: Brings operational intelligence across AIOps, observability, BizOps, and FinOps, directly correlating technical signals and operational anomalies with business outcomes. 

This enables organizations to:  

  • Build more reliable, hallucination-resistant AI models 
  • Improve explainability and governance across automated decisions 
  • Accelerate time-to-value from AI investments 

Frequently Asked Questions (FAQs) 

  1. Why do enterprise AI projects fail even with massive data lakes?

Data volume is not the same as data understanding. Data lakes store raw data in isolated silos without architectural or business relationships. Without contextual mapping, AI models cannot determine which processes, transactions, or services that data actually influences. 

  1. What is an Enterprise Knowledge Graph, and why does AI need it?

An Enterprise Knowledge Graph is a dynamic, semantic model that connects disparate data assets, applications, and workflows based on real-world relationships. It provides AI models with deterministic context, preventing hallucinations and enabling autonomous agents to reason accurately about complex systems. 

  1. How does QyrusAI provide context to enterprise operations?

QyrusAI uses continuous discovery and automated dependency mapping to build a Live Enterprise Knowledge Graph. This connects raw telemetry, data pipelines, and infrastructure to the specific business workflows they support.

  1. How does contextual intelligence improve AI governance and explainability?

When AI makes a recommendation or triggers an automated remediation, context reveals the exact dependency path and reasoning behind the decision. This transparency makes models auditable, safe, and trustworthy for enterprise leadership.  

The Bottom Line 

AI doesn’t fail because of a lack of data. It fails because of a lack of context. 

The question that helps you separate experimentation from real impact is no longer: 

“Do we have enough data for AI?” 

It is: 

“Do we understand our data well enough for AI to work?” 

Ready to move from disconnected data to contextual intelligence? 

Discover how QyrusAI connects your data, systems, and business outcomes into a living operational Knowledge Graph.

Talk to an Expert 

Business Impact in IT Operations

The Cost You Can Measure and the Cost You Can’t 

Enterprises are very good at measuring certain things like: 

  • Infrastructure spend. 
  • Cloud usage. 
  • Licensing costs. 

These numbers are visible, trackable, and often discussed. But there’s another category of cost that rarely appears clearly on any dashboard and that is the cost of not understanding business impact. 

When an Incident Happens 

Consider a typical incident. An application slows down, an alert is triggered and teams begin investigating. 

But before anything else, there’s uncertainty. 

  • Is this affecting a critical service? 
  • Are customers impacted? 
  • Is revenue at risk? 

And until these questions are answered, the response remains cautious. Or at worst misdirected. 

The Cost of Delay 

In many cases, the biggest cost is not the incident itself. It’s the time taken to understand its impact. Because during that time: 

  • Teams are aligning across functions 
  • Information is being gathered manually 
  • Decisions are being deferred 

And all of this adds up, minutes turn into hours and the impact grows. 

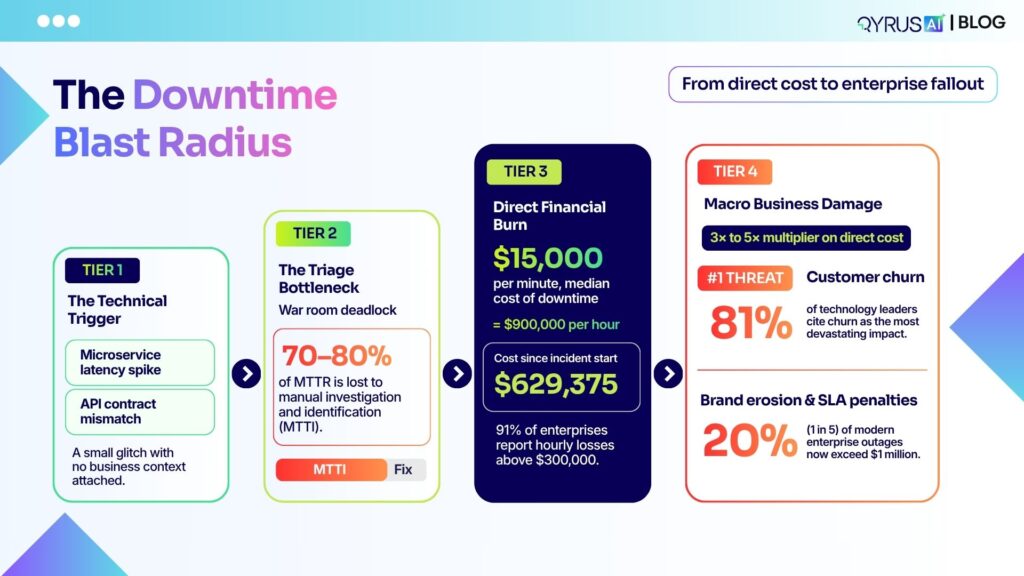
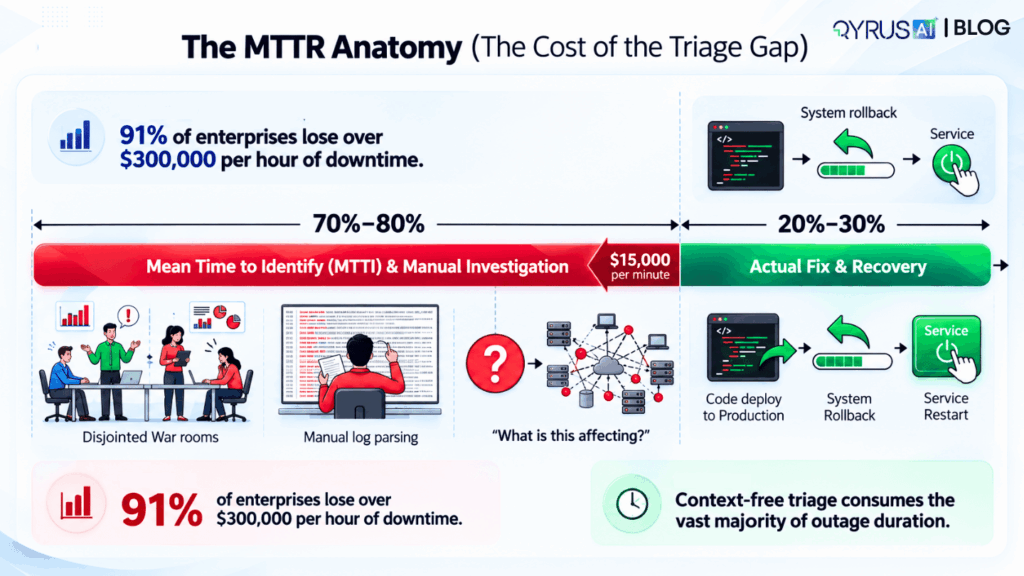
Industry benchmarks indicate that 70% to 80% of Mean Time to Resolution (MTTR) is spent solely on investigation and Mean Time to Identify (MTTI)—manually tracing dependencies, gathering logs, and determining what broke. When the median enterprise cost of downtime has climbed to approximately $15,000 per minute ($900,000 per hour), every minute spent searching for context in an active war room translates directly into catastrophic financial exposure. Furthermore, 91% of enterprises report that a single hour of IT downtime costs them more than $300,000. 

MTTR Breakdown

When Effort Doesn’t Match Importance 

Without clear business context, teams often fall into a common pattern. They respond to what is visible, not what is important. A technically complex issue may get immediate attention while a business-critical issue, if less visible, may take longer to surface. This misalignment is subtle but over time, it becomes expensive for the business. 

Research reveals that 44% of IT incidents stem from detectable failures—technical issues that telemetry monitored, but teams failed to interpret or prioritize correctly in time. Worse yet, 47% of outages are reported by customers before internal monitoring catches them, exposing how traditional component alarms leave operational teams blind to real customer journeys and transactional bottlenecks. 

The Ripple Effect Across the Organization 

The lack of business impact visibility doesn’t just affect IT. It affects: 

  • Business teams waiting for updates 
  • Leadership trying to make decisions 
  • Customers experiencing disruptions 

And because the impact is not clearly understood, communication becomes fragmented. Different teams operate with different assumptions. The result is an accelerated sense of chaos. 

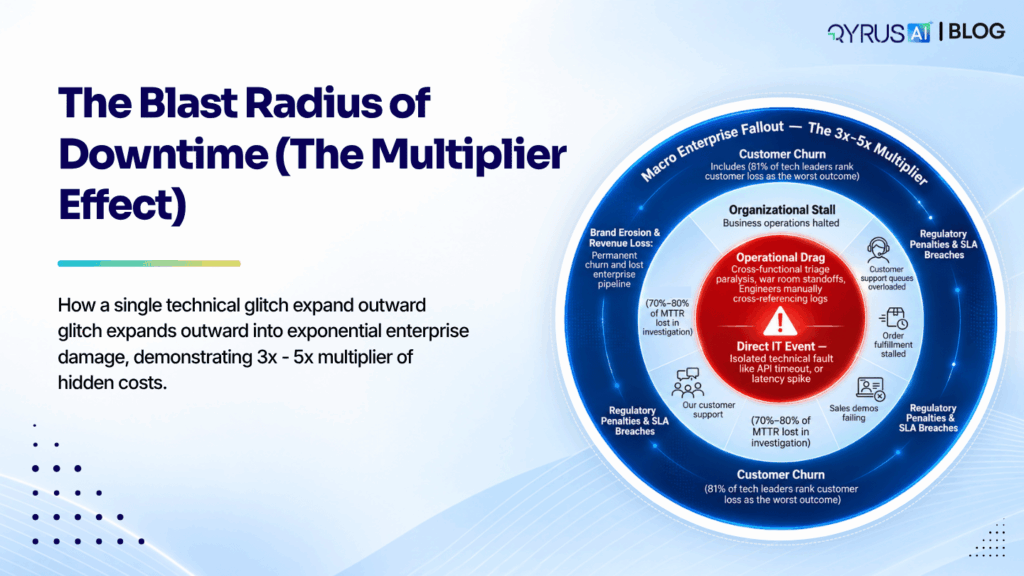
The true toll extends far beyond immediate remediation fees. Studies indicate that enterprises face 3x to 5x hidden costs—encompassing lost cross-departmental productivity, regulatory penalties, and brand equity damage. In fact, 81% of technology leaders cite customer loss and churn as the most damaging long-term consequence of operational downtime. 

The Downtime Blast Radius

Why This Problem Persists 

Most organizations do not intentionally ignore business impact. They simply lack a way to see it in real time. This is because systems and business services are not clearly connected. Without that connection, the true nature and quantum of impact has to be guessed and this is both often inaccurate and risky. 

This blind spot is a primary driver behind why 1 in 5 organizations (20%) report that their most recent major outage exceeded $1 million in total losses. Across the Global 2000, unplanned downtime siphons an estimated $400 billion annually—not because telemetry was missing, but because isolated signals lacked structural and commercial context. 

From Reaction to Clarity 

The organizations that handle this well do something differently. They don’t wait to understand impact after an incident. They already know it. Because their systems are mapped to business services, the dependencies are visible and the context is always available. This helps to avoid decisions that come from inaccurate guesswork. 

Where QyrusAI Fits In 

QyrusAI enables this shift by connecting systems to business services and continuously mapping dependencies, allowing organizations to understand impact instantly. 

As an agentic platform designed to unify the enterprise application lifecycle, QyrusAI grounds operational workflows across three core pillars: 

  • Modernize: Unpacks legacy architectures, illuminates hidden technical debt, and rationalizes application portfolios with comprehensive dependency context. 
  • Assure: Delivers continuous, automated testing across web, mobile, API, SAP, and data pipelines to catch defects long before code reaches production. 
  • Operate: Brings actionable operational intelligence across AIOps, observability, BizOps, and FinOps, directly correlating infrastructure alerts with customer journeys and business outcomes. 

At the core of the platform is QyrusAI’s Live Enterprise Knowledge Graph, which maintains a continuously observed, real-time model of applications, integrations, and business processes. 

So instead of asking: 

“What does this affect?” 

Teams already know. And instead of delaying decisions, they act immediately with clarity. 

Frequently Asked Questions (FAQs) 

  1. What is the hidden cost of IT downtime?

The hidden cost refers to secondary and long-term damages—such as lost employee productivity, brand erosion, missed sales opportunities, regulatory penalties, and customer churn. Research shows these indirect damages are typically 3x to 5x higher than the immediate direct costs of system recovery. 

  1. Why does traditional IT monitoring fail to identify business impact?

Traditional monitoring tracks component-level telemetry (CPU, memory, server uptime, network packets) in isolation. It cannot determine whether a 500ms database delay affects a non-critical background task or halts an active checkout flow for high-tier enterprise clients. 

  1. How does QyrusAI establish real-time business context?

QyrusAI utilizes its Live Enterprise Knowledge Graph to continuously discover assets, map dynamic dependencies, and bind technical telemetry directly to business services, workflows, and KPIs. This ensures teams see the commercial blast radius of any incident in real time. 

  1. How does understanding business impact reduce Mean Time to Resolution (MTTR)?

Because 70% to 80% of MTTR is typically spent on investigation (MTTI), providing immediate topological and business context eliminates the guesswork. Teams instantly know which service is broken, which business workflow is impacted, and who needs to remediate it. 

The Bottom Line 

The cost of not understanding business impact is not always visible, it shows up in: 

  • Delayed responses 
  • Misaligned priorities 
  • Increased disruption 

The real question to ask here is: 

How much is uncertainty costing you today? 

Still reacting before understanding impact? 

See how QyrusAI helps you identify, prioritize, and act on what truly matters to your business in real time. 

Talk to an Expert 

Technology spend is no longer predictable by looking at last month’s bill. Cloud, SaaS, on-premises infrastructure, and AI workloads now move too quickly, consume too differently, and depend on too many disconnected systems for traditional FinOps reporting to keep up. 

This whitepaper explains why enterprises must move beyond visibility and build an architecture for cost predictability — one that connects billing data with telemetry, attribution, dependency context, AI usage signals, and decision intelligence. 

Why Cost Visibility Should Be Your Priority 

Most enterprises can see what they spent. Far fewer can explain why spend changed, which teams or applications drove the increase, or what will happen before the next invoice arrives. 

The gap is not just a tooling issue. It is a data architecture issue. Predictable technology spend requires more than dashboards. It requires a connected model that understands usage, ownership, dependencies, utilization, AI token economics, and planned engineering change.

98% 

of FinOps practitioners now manage AI spend. 

90% 

manage SaaS spend as FinOps expands beyond cloud. 

29% 

estimated IaaS/PaaS waste in 2026, driven by growing workload complexity. 

What You’ll Learn in This Whitepaper 

  • Why historical cost forecasting fails in dynamic cloud, SaaS, hybrid, and AI environments 
  • How AI workloads introduce new attribution challenges through tokens, agents, retries, reasoning steps, and shared API usage 
  • The five root causes of technology cost unpredictability 
  • Why billing data alone cannot support finance-grade forecasting 
  • How QyrusAI combines cost data, telemetry, attribution, dependency mapping, and AI intelligence into a cost predictability architecture 
  • How enterprises can detect anomalies, explain cost drivers, and take action before spend becomes a month-end surprise 

Built for Leaders Who Need Predictable Technology Spend 

This whitepaper is designed for CTOs, CIOs, FinOps leaders, cloud leaders, engineering executives, finance stakeholders, and technology operations teams responsible for governing spend across modern, multi-source technology estates. 

How QyrusAI Helps Enterprises Move from Visibility to Predictability 

QyrusAI helps enterprises unify technology cost data across cloud, SaaS, on-premises infrastructure, licenses, and AI providers. By enriching billing data with telemetry, utilization signals, dependency maps, and AI usage instrumentation, QyrusAI turns cost reporting into cost intelligence. 

  • Unified cost data: Normalize spend across cloud, SaaS, AI providers, software licensing, and on-premises infrastructure. 
  • Telemetry-enriched attribution: Connect cost to real usage, resource efficiency, application behavior, and ownership. 
  • AI-powered forecasting: Forecast spend at enterprise, business unit, application, service, and resource levels. 
  • Anomaly intelligence: Detect cost deviations, identify root causes, route them to the right owners, and recommend actions. 
  • AI cost attribution: Track token, model, feature, agent, retrieval, and retry-level consumption to understand AI unit economics. 
  • Change impact simulation: Understand the financial effect of infrastructure, workload, and AI architecture changes before they happen. 

Explore QyrusAI for FinOps

Learn how enterprises can build a cost predictability architecture for the AI era — and how to give Finance and Engineering a shared, actionable view of what spend is doing, why it is changing, and what can be done before the cost occurs. 

Featured Image

October 26, 2026 | Madison, Wisconsin 

Every SAP change comes with a practical question: will the business processes people rely on still work as expected? 

That’s a conversation worth having in person. QyrusAI is heading to Madison, Wisconsin, on October 26, 2026, for the ASUG Wisconsin Chapter Fall Meeting and Social to explore how AI can help teams approach SAP change with greater confidence. 

From planning modernization initiatives to testing everyday updates, SAP teams have plenty to balance. A change in one application can affect integrations, data, and workflows across the business. Understanding those connections—and validating them—is essential to moving forward. 

QyrusAI brings application discovery, AI-powered testing, and operational intelligence together to help teams see the bigger picture. In Madison, we’re looking forward to conversations about: 

  • Understanding dependencies across SAP and connected applications. 
  • Strengthening testing for critical, end-to-end business processes. 
  • Reducing repetitive manual work as systems evolve. 
  • Connecting modernization decisions with software quality and operational reliability. 

We also want to hear your side: what’s taking too long, where testing gets complicated, and what your team hopes to improve next. 

If you’ll be joining the ASUG community in Madison, let’s connect. Bring your questions and your toughest SAP testing challenges—we’d love to talk them through. 

See you in Madison on October 26!