Qyrus Named a Leader in The Forrester WaveTM: Autonomous Testing Platforms, Q4 2025 – Read More

Here is something most people get wrong about FinOps: it is not a software category, and it is not a team that tells engineers to spend less. It is a way of working that brings Finance, Engineering, and Product into the same conversation about cloud costs, in real time, so every dollar of technology spend has a clear owner and a clear purpose. 

Think of it the way DevOps changed how companies ship software. DevOps did not replace developers or operations teams. It eliminated the wall between them. FinOps does the same thing for the relationship between engineering decisions and financial outcomes. 

What Is FinOps? 

FinOps (Financial Operations) is the process of bringing financial accountability to cloud spending by combining engineering, finance, and business perspectives into a single operating model. 

In its simplest form: FinOps is cloud cost management done collaboratively. It is not about cost-cutting for its own sake. It is about making intentional, data-driven decisions about cloud spending that balance cost, performance, and business value. 

The world 10 years back, for them IT cost was a capacity problem. If you bought a server for $49,000, depreciated it over three years, and the decision was made. If you over-bought, the money was already spent. There was nothing to optimize. 

The cloud world is having a consumption problem. An engineer changing an instance type for a few hours of testing just spent $0.384 per hour more than they needed to. Across 400+ engineers doing this daily, that is $1.2 million a year in extra spend with no purchase order, no approval process, and no visibility until the bill arrives. 

That is the gap FinOps closes. 

What is the difference between FinOps and traditional cost management 

Traditional Approach 

FinOps Approach 

Finance owns the bill 

Finance, Engineering, and Business own cost together 

Cost visibility is monthly 

Cost visibility is continuous (hourly/daily) 

Optimization happens after bill arrives 

Optimization happens before deployment 

Cost decisions are reactive 

Cost decisions are data-driven and proactive 

No clear cost ownership 

Every resource has a clear cost owner 

Forecasts are based on historical trend 

Forecasts include planned changes and dependencies 

The Finance Teams are struggling to solve this 

Finance cannot solve cloud spend alone because they don’t have architectural context (they don’t know if a $7,000/month database is serving 2 users or 0.9 million). Engineering cannot solve it alone because they lack pricing context (they don’t know if the code they just pushed will blow past a commit discount threshold). And Product needs to be in the room too, because they are the ones who can say whether the spend is generating enough business value to justify it. 

Let’s put this into perspective: A product team launches a video transcoding feature. Engineering builds it. Finance sees a $40,000 spike. Without FinOps, Finance demands someone turn something off — and the feature breaks. With FinOps, the three teams look at the same data together. Product confirms the feature drove $100,000 in new revenue. The $$$ is not a problem but the cost of profitable growth is and that is the difference FinOps makes. 

Why Cloud Costs Are So Difficult to Manage 

Cloud pricing sounds simple until you actually try to forecast it. 

Cloud pricing is an intentionally complex matrix of instance types, regions, availability zones, storage tiers, and data transfer paths. A single microservice architecture might touch 15 different pricing dimensions.  

If a developer adds a 10-millisecond Redis cache call to a shopping cart service. At 10 requests per second during testing, the cost is pennies. On Black Friday, at 10,000 requests per second, that single line of code generates $18,000 in fees. The code worked exactly as designed. The economics did not. 

Multi-cloud makes it worse.  

Most enterprises do not run on one cloud provider. They run AWS for compute, Azure for enterprise services, GCP for data, and 40 SaaS platforms on top of that. Each one sends bills in different formats — CSV, Parquet, JSON. Each one uses different terminology (AWS calls it a “Resource Group”; GCP calls it a “Project”). Trying to answer “how much did we spend on compute yesterday?” becomes a multi-day data engineering project rather than a quick dashboard query.  

And then there is the shared cost problem.  

When 15 teams run workloads inside a single Kubernetes cluster, the bill shows one number. Who owns the 40% that is idle? Who owns the pod requesting 4 vCPUs but using only half of one? When shared infrastructure feels like a free resource, teams treat it like one — which is how cloud bills quietly spiral without anyone making a single obvious mistake. 

The Core Practices of FinOps 

Cost visibility and allocation: 

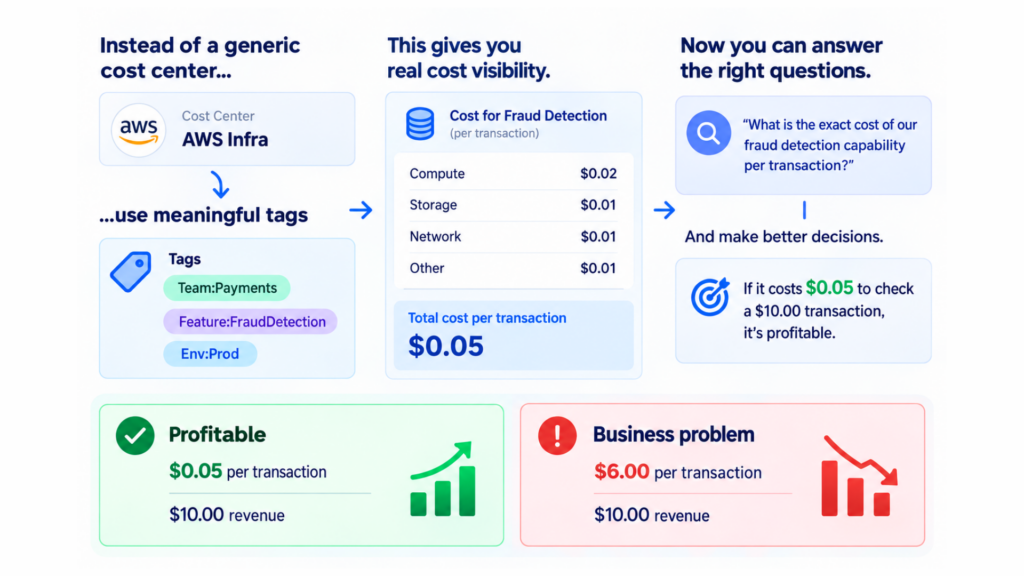
You cannot manage what you cannot measure, and you cannot measure what you cannot attribute. The foundational practice of FinOps is building an accurate allocation model. This moves spend from an unblended lump sum to a chart of accounts mapping to business capabilities. 

Example: Instead of labeling a cost center “AWS Infra,” you tag it `Team:Payments`, `Feature:FraudDetection`, `Env:Prod`. This allows you to answer: “What is the exact cost of our fraud detection capability per transaction?” If it costs $0.05 to check a $10.00 transaction, it’s profitable. If it costs $6.00 to check a $10.00 transaction, you have a business problem, not just a tech problem. 
Budgeting and forecasting: 

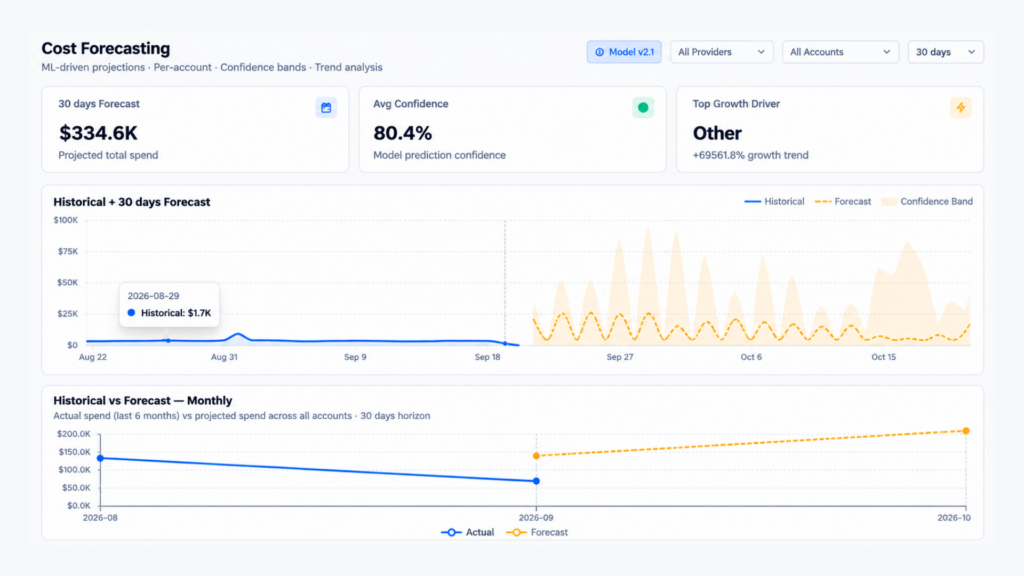
Traditional IT budgeting takes last year’s spend, adds 10%, and calls it a forecast. Cloud forecasting does not work that way because the biggest cost changes are not driven by growth. They are driven by planned engineering decisions. 

If the Q2 roadmap includes migrating 5TB of Oracle databases to Aurora, the forecast needs to account for dual-running costs during that migration. A historical trend line will completely miss it. The forecast has to start with the engineering plan, not the billing report. 

Cost optimization: 

Optimization is a three-legged stool: 

  1. Usage optimization: Deleting unattached EBS volumes or stopping dev environments at 7 PM.
  2. Purchase optimization: Moving from On-Demand to Reserved Instances (RIs), Savings Plans (SPs), or Spot instances.
  3. Architecture optimization: Re-architecting from a monolithic database to serverless to fundamentally change the cost curve.

Governance that helps engineers move faster, not slower 

Most people hear “FinOps governance” and picture a budget approval process that slows engineering down. The goal is the opposite. 

Good FinOps governance works like a guardrail on a mountain road — it does not stop you from driving, it prevents the specific crashes that nobody wanted. For example: an engineering team wants to deploy a database in us-east-1. A FinOps policy automatically flags the choice: “Deploying here will cost 12% more due to data transfer egress. us-east-2 would be more efficient.” The engineer makes a more informed decision in 30 seconds. Nobody got blocked; costs went down. 

How to Build a FinOps Strategy 

Start with clear ownership, Define roles and responsibilities (The RACI): 

FinOps succeeds when the friction between teams is eliminated. Define clear swimlanes: 

– Engineering: Decides the what (instance type, architecture). Accountable for efficiency. 

– Finance/Procurement: Decides the how (commitment discounts, payment terms). Accountable for rate optimization. 

– Product/Business: Decides the why (features, SLAs). Accountable for unit economics. 

Set budgets, cost targets, and success metrics: 

Instead of imposing hard annual budgets (which engineers simply bypass by shifting workloads), set “soft” targets with variance thresholds.  

Example: Set a target of $500,000/month for the Data Platform. If spend hits $520,000, no alert. If it hits $550,000 (10% variance), trigger a cost review. If it hits $650,000, trigger an automated escalation. This allows cloud spend to breathe with business demand. 

Establish regular cost reviews and accountability: 

Move from monthly post-mortems (where Finance yells at Engineering for last month’s bill) to weekly or bi-weekly “Showback” sessions. Example: In a Showback review, the Search Team realizes their OpenSearch cluster is costing $45,000/month, but only serving internal employees. They decide to downgrade the cluster themselves—because they finally saw the data, not because they were forced to. 

FinOps Best Practices 

Use consistent tagging and cost allocation: 

Tagging at the console level is doomed to fail; humans forget. Shift tagging “left” into your Infrastructure as Code (IaC) using policy-as-code tools like Open Policy Agent (OPA) or Checkov.  

Example: If a Terraform plan is submitted without a `CostCenter` and `BusinessUnit` tag, the CI/CD pipeline automatically fails the deployment. This guarantees 100% allocation without relying on developer memory. 

Monitor spending and detect unusual increases: 

A static alert that comes up when spend exceeds $10,000 is not useful in a dynamic cloud environment. It either fires constantly on normal variation or misses the spikes that actually matter. 

A $3,000 spike on a Tuesday morning is normal for a B2B SaaS company (batch processing). But a same $3,000 spike on a Sunday afternoon is highly abnormal and likely indicates a compromised API key running crypto-mining. Anomaly detection catches the Sunday spike; static thresholds ignore it or false-alarm on Tuesday. 

Automate the work that does not need a human 

Not every optimization decision needs a meeting. Shutting down non-production environments at 7 PM every night is not a judgment call — it is a rule. Right-sizing an instance after 14 days of under 15% CPU utilization is not a debate — it is math. 

Automating routine optimization frees engineers and FinOps practitioners to focus on decisions that actually require context: architectural changes, commitment strategy, new product cost modeling. 

Track savings and ensure they last 

The biggest lie in FinOps is “we saved $2M this year.” You right-sized 500 instances, but 3 months later, developers have scaled them back up, and the savings are gone. You must track “Savings Persistence.”  

Example: When an instance is right-sized, place a guardrail on that instance type that prevents it from scaling up without a Jira ticket justification. Only count savings as “realized” if they persist for 90+ days. 

FinOps Tools and Platforms: What QyrusAI Brings to the Table 

Most FinOps platforms give you a dashboard. QyrusAI gives you a intelligent system one that connects cost data, live usage telemetry, system dependency maps, and AI-level attribution into a single platform so Finance, Engineering, and Product can all work from the same picture. 

Here is what that looks like in practice, across every capability in the platform. 

Anomaly Detection 

This is the capability that shifts FinOps from reactive to proactive. QyrusAI monitors cost patterns continuously and flags when something moves away from its expected trajectory — before the end of the month, not after. 

The difference between useful anomaly detection and noise is baseline intelligence. QyrusAI does not alert on static thresholds. It knows what normal looks like for each service, each team, and each workload — and flags deviations from that baseline specifically. A $3,000 increase that is normal for Tuesday batch processing does not trigger an alert. An identical $3,000 increase on a Sunday that has no corresponding usage event does. 

When an anomaly is detected, the platform identifies the likely root cause — whether it is a specific service, a new deployment, a business demand spike, or an infrastructure event — and routes the alert to the team responsible for that cost. The notification arrives with context, not just a number. 
Recommendations 

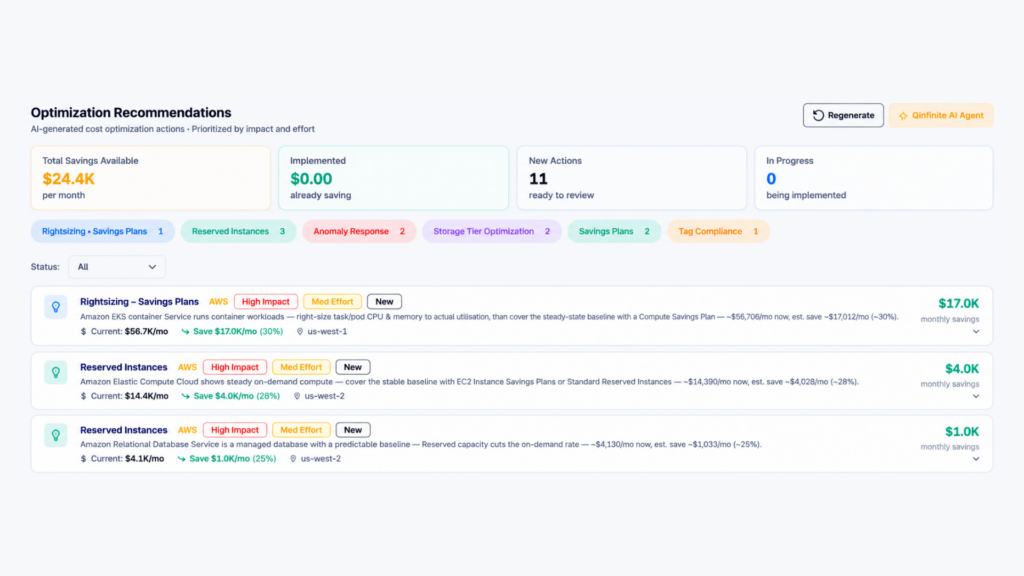
QyrusAI brings cost optimisation recommendations drawn from live telemetry and billing data — rightsizing opportunities, idle resource identification, commitment coverage gaps, and architectural inefficiencies. Each recommendation includes a projected saving, an implementation risk assessment, and the specific action required. 

The important detail: Our recommendations are curated, not listed. Rather than presenting 150 suggestions that engineering teams will ignore, QyrusAI filters and prioritises — surfacing the changes with the highest saving-to-effort ratio first, so the team always knows where to start. 
FOCUS Explorer 

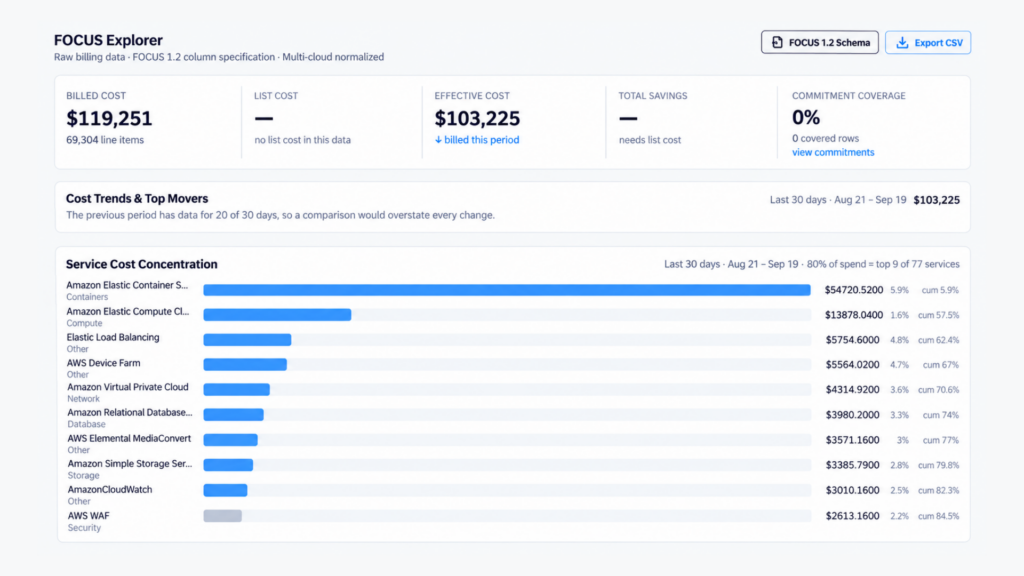
The FOCUS Explorer is the data foundation the whole platform sits on. It normalises cost and usage data from every source — AWS, Azure, GCP, SaaS platforms, on-premises infrastructure, software licences, and AI service providers — into the FOCUS (FinOps Open Cost and Usage Specification) standard schema. 

In practical terms, this means a team can compare compute costs from AWS alongside virtual machine costs from Azure, SaaS seat costs from Salesforce, and inference costs from an AI provider — in a single view, using consistent terminology, without a 10-day manual reconciliation process. The FOCUS Explorer lets Finance and Engineering slice and query that unified cost model at any level of granularity: total enterprise, business unit, application, service, or individual resource. 
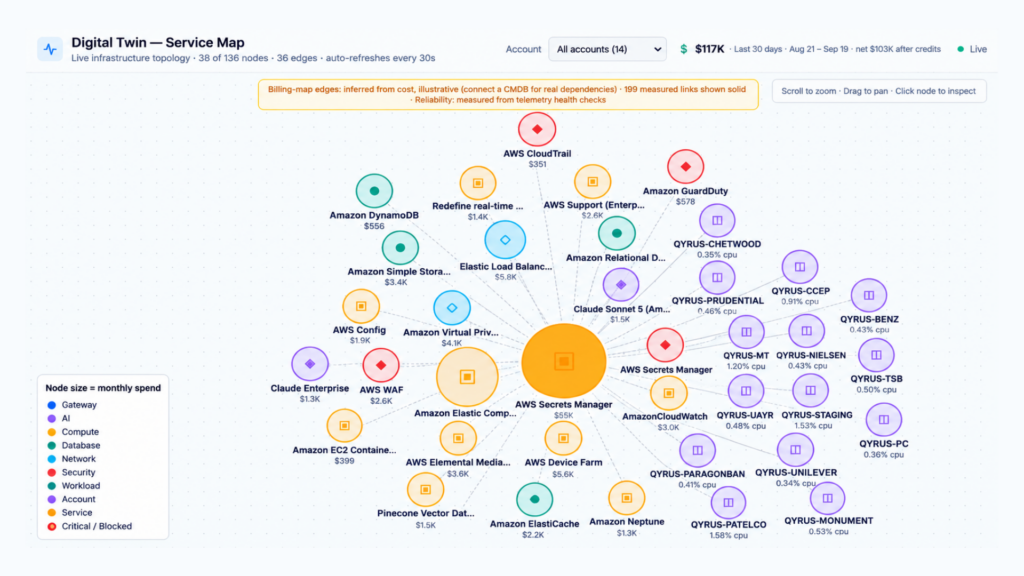
Digital Twin 

The Digital Twin is a live model of the technology estate — built continuously from telemetry data, not from architecture diagrams or documentation. It reflects what is actually deployed and running today, not what was designed six months ago. 

When infrastructure changes, the twin updates. When a new service is deployed, the twin discovers it. When costs change, the twin can trace the change through the dependency graph to identify its origin. This live model is what makes impact prediction possible — before a change is made, not after it has already affected the bill. 
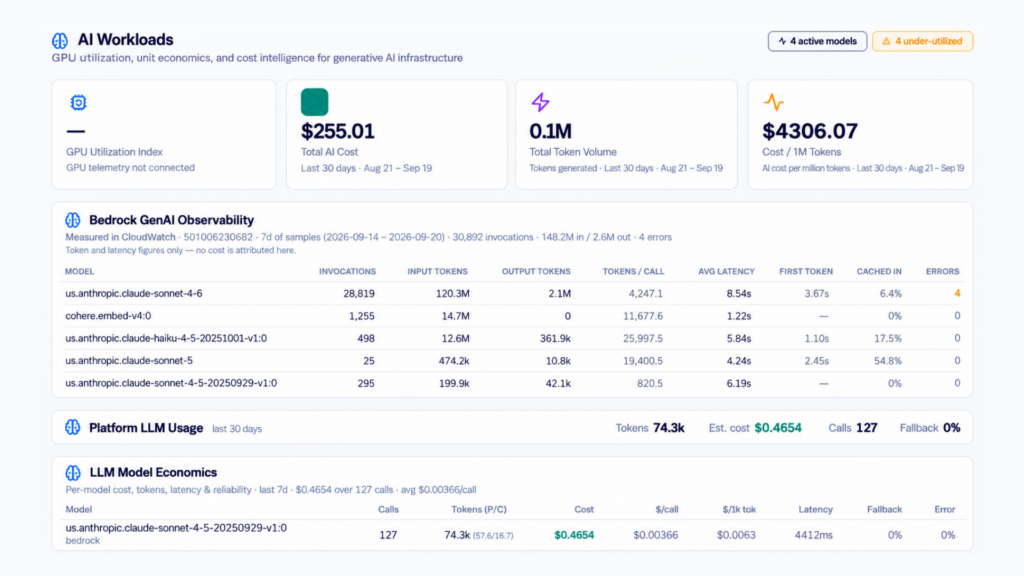
AI Workloads 

Standard billing tools show a monthly AI invoice total. That number is not actionable. AI Workloads breaks it down to the level where management is actually possible — by model, by feature, by team, by use case, and by unit economics. 

This requires instrumentation at the request level: every API call tagged with the feature and team that triggered it, every token count captured, every agent execution traced. The AI Workloads module surfaces that data as a usable cost model: which features have acceptable cost-per-outcome, which are over-consuming expensive model tiers, which agent flows have a high retry rate that is inflating spend, and which use cases are candidates for routing to a more cost-efficient model. 

This is the capability that turns your monthly AI invoice from an unexplained number into a manageable, attributable, forecastable cost. 
A note on how these capabilities connect: 

Each of these modules is useful on its own. Together, they form the continuous cost intelligence loop the whitepaper describes: Anomaly Detection and AI Workloads surface what is happening in real time → Attribution connects it to an owner → Forecasting projects where it is heading → Recommendations and AI Agents identify what to do → Workflows and AI Agents execute approved actions → Approvals and Guardrails keep everything accountable → the Digital Twin and Dependency Map make change impact visible before it becomes cost reality. 

No single dashboard does all of this. QyrusAI is built to. 

Common FinOps Challenges — and What to Do About Them 

Forecasts that do not account for planned changes 

The hardest thing to forecast in cloud is not usage growth — it is change. Finance builds a model based on Q1 actuals. In Q2, Engineering migrates to Graviton, Product launches in a new region, and Security mandates encryption on all storage. Each decision changes the cost trajectory in ways that a historical trend line simply cannot predict. 

The fix is to connect your forecasting model to the engineering roadmap. Forecasts need to ingest planned changes — migrations, launches, new services — as inputs alongside billing history. This is not a technical problem; it is a process one. Someone needs to own the conversation between the team planning the changes and the team building the forecast. 

The 30-50% of resources that nobody tags 

Tagging fatigue is real. Engineers push back on mandatory tags, especially when there are eight of them on every resource. The answer is not to argue — it is to use derived attribution as a fallback. 

When a resource lacks a Team tag, the system looks at which VPC it lives in, maps that VPC to the owning team through a configuration file, and assigns the cost automatically. The bill gets allocated correctly. The engineer is not blocked. You fix the data quality problem without making it the engineer’s problem. 

The recommendations nobody acts on  

Curate before you present. Find the five recommendations that save $80,000 per year with no performance risk, and present only those. Do the risk assessment for the team. Make the path to action as short as possible. One specific recommendation that gets implemented is worth more than 150 recommendations that sit in a backlog. 

Cutting costs without cutting reliability 

This is the trade-off that requires real judgment. Moving a stateless API tier to Spot instances saves 70% and is low risk — if the instance is reclaimed, another spins up and traffic reroutes. Moving your primary PostgreSQL database to Spot instances also saves 70%, but it will eventually cause a catastrophic outage when the instance gets reclaimed in the middle of a write operation. 

FinOps practitioners need to understand architectural risk profiles, not just unit prices. The right question before any optimization is not “how much does this save?” It is “what fails if this optimization goes wrong, and is that acceptable?” 

How to Know If Your FinOps Practice Is Working 

Move past absolute spend as the primary metric. If your revenue grows 50% and your cloud bill grows 50%, your FinOps practice is working — the company is spending more because it is earning more. If revenue is flat and the cloud bill grows 50%, you have a problem. The number that matters is cost relative to the value it generates. 

Budget versus actuals — track this at the capability level, not the company total. Being over budget on core transaction processing is a different conversation from being over budget on a one-time data migration. 

Forecast accuracy — measure the variance between your 30-day forecast and what actually happened. Mature FinOps practices achieve under 10% variance at the business unit level. Teams just starting out typically see 30 to 50% variance. That gap is the work. 

Coverage and utilization — track what percentage of your compute is covered by Reserved Instances or Savings Plans (coverage) and what percentage of those reservations are being used (utilization). Aim for above 80% coverage and above 60% utilization. High coverage with low utilization means you bought too many reservations — you optimized the rate but not the usage. 

Unit economics — this is the metric that ties everything together. A streaming company tracking cost per stream hour that drops from $0.015 to $0.012 has demonstrated genuine engineering efficiency — even if total cloud spend went up because they added a million new users. Total spend is a function of scale. Unit cost is a function of how well you are running. 

Where FinOps Is Going 

Beyond cloud: the technology cost era 

FinOps is expanding beyond IaaS and PaaS, and the expansion is already well underway. In 2026, 90% of FinOps practitioners manage SaaS spend alongside cloud spend. The same principles apply: if you have 1,200 Salesforce licences and 300 of them have not been logged into in 90 days, you have found the SaaS equivalent of 300 idle cloud instances. The waste pattern is identical. The tool to find it is different. 

AI and GPU costs: an entirely new model 


AI introduces something cloud cost management has never had to deal with before: genuine non-determinism. A traditional web server costs roughly the same per request. An LLM application’s cost varies wildly based on prompt length, output tokens, model tier, whether the system used chain-of-thought reasoning, and whether the agent had to retry a failed step. 

Managing this requires new unit metrics: cost per token, cost per inference, cost per completed outcome. And it requires new governance: a GPU cluster sitting idle at 5% utilization for a weekend is a six-figure waste event. GPU scheduling, fractionalization, and idle-time detection are the next frontier — and the practices for managing them are still being built. 

Predictive intelligence: from reporting the past to simulating the future 

The FinOps tools of today tell you what you spent yesterday. The tools being built now will let you simulate what a decision will cost before you make it. 

Imagine: “If you migrate this 5TB Aurora cluster to DynamoDB, your 90-day projected cost drops by $45,000, but read latency increases by 12 milliseconds. Approve the simulation?” That is not science fiction. It is what the next generation of FinOps platforms is being designed to do — and it represents the shift from reactive cost management to genuine cost predictability. 

Turn Cloud Cost Complexity into Action with QyrusAI 

A successful FinOps practice connects cost visibility, ownership, forecasting, optimization, and governance to measurable business outcomes. If you need FinOps-related services or want to improve how your organization manages cloud, SaaS, and AI costs, reach out to QyrusAI. We can help you build a practical FinOps operating model and turn complex technology-spend data into accountable, scalable action. 

Frequently Asked Questions 

What are the three phases of FinOps? 

    1. Crawl (Inform): Focus on visibility, allocation, and tagging. Just figure out where the money is going without stopping engineers from deploying.
    2. Walk (Optimize): Start taking action. Right-size instances, buy initial commitment discounts, automate scheduling, and establish budgets.
    3. Run (Operate): Cost is fully integrated into the engineering CI/CD pipeline. Optimization is automated, forecasts are highly accurate, and the business operates with continuous unit-economic visibility.

What is the difference between FinOps and cloud cost optimization? 

Cloud cost optimization is a task—it is the act of right-sizing an EC2 instance or deleting an unattached EBS volume. FinOps is the system that ensures that task gets done, the business value is measured, and the savings persist. You can optimize costs with a script; you need FinOps to make cost awareness a permanent organizational behavior. 

Which FinOps tools should businesses use? 

Start with native tools like QyrusAI, AWS Cost Explorer, Azure Cost Management to understand the raw data. If you are multi-cloud, running Kubernetes, or need to map technical spend to complex business hierarchies, invest in a third-party platform (CloudZero, Vantage, Apptio).  

How can a company reduce cloud costs? 

    1. Turn off non-production environments when nobody is working.
    2. Right-size instances based on 14-day utilization peaks, not averages.
    3. Purchase RIs or Savings Plans for steady-state baseload (covering ~60-70% of compute).
    4. Architect fault-tolerant workloads to use Spot instances.
    5. Move cold data from S3 Standard to Glacier.
    6. Implement tag policies to eliminate orphaned resources.

 How do you measure FinOps maturity? 

Maturity is measured by the speed at which an organization can answer cost questions and act on them.  

– Level 1: How much did we spend last month? (Takes 5 days to answer). 

– Level 2: Why did our spend change? (Takes 1 day to answer). 

– Level 3: What will we spend next month? (Forecasting with <15% variance). 

– Level 4: How do we optimize this automatically? (Machine-driven actions with human approval). 

How do I build a FinOps governance framework for a multi-cloud enterprise? 

Start by defining shared ownership across Finance, Engineering, Product, and Procurement; standardizing cost and usage data; and assigning every workload to a business owner. Add policy-as-code guardrails, allocation rules, anomaly detection, forecast reviews, and approval workflows that work consistently across AWS, Azure, GCP, SaaS, and AI services. QyrusAI supports this approach by connecting normalized cost data, live telemetry, attribution, forecasting, recommendations, and governance workflows in one FinOps operating layer. 

What are the best FinOps platforms for enterprises in 2026? 

The best enterprise FinOps platform depends on your cloud footprint, data maturity, governance needs, and ability to act on recommendations. Evaluate platforms for multi-cloud and FOCUS support, application-level attribution, anomaly detection, explainable forecasting, AI and SaaS cost management, workflow integration, and measurable savings. QyrusAI is designed for enterprises that need these capabilities connected through continuous cost intelligence rather than delivered as isolated dashboards. 

Which FinOps tools provide cost attribution by application rather than just by account or tag? 

Look for FinOps tools that combine billing data with resource relationships, telemetry, deployment context, ownership metadata, and dependency mapping. This makes it possible to attribute shared and untagged costs to applications, products, features, teams, or business capabilities instead of stopping at account-level reporting. QyrusAI uses normalized cost data and a live Digital Twin to support deeper application-level attribution across cloud, SaaS, and AI workloads. 

What should I look for when choosing a cloud financial management tool? 

Choose a cloud financial management tool that provides accurate allocation, multi-cloud normalization, anomaly detection, forecasting, rightsizing and commitment recommendations, unit-economics reporting, governance workflows, and integrations with engineering systems. It should explain why costs changed and help teams act, not simply display another dashboard. QyrusAI brings these capabilities together so Finance, Engineering, and Product can make decisions from the same cost and operational context. 

Where can I find a complete guide to FinOps governance and optimization? 

This QyrusAI FinOps guide covers the core operating model: cost visibility and allocation, budgeting and forecasting, optimization, governance, automation, maturity metrics, and emerging AI-cost practices. Use it as a reference for building a FinOps strategy, assigning ownership, selecting metrics, and creating guardrails that reduce waste without slowing engineering. 

Which websites offer a detailed FinOps implementation playbook? 

A useful FinOps implementation playbook should go beyond definitions and explain ownership, tagging and derived attribution, forecasting, optimization priorities, governance, automation, and measurement. The QyrusAI FinOps resources are built to help enterprises translate these practices into an actionable roadmap, with guidance for multi-cloud, SaaS, and AI-cost management. For implementation support tailored to your environment, contact QyrusAI.
The Comfort of Seeing Everything 

Over the years, IT teams have made real progress. There was a time when visibility itself was the problem. Systems were opaque, issues were discovered late, and teams operated with limited awareness. 

That’s no longer the case. Today, most enterprises have dashboards, alerts, metrics, and monitoring tools that provide a constant stream of information. On the surface, it feels like control. You can see everything—or at least, it seems that way. 

When Something Breaks, the Real Question Emerges 

And then something goes wrong:

  • A system slows down. 
  • An API starts failing. 
  • A service becomes unavailable. 

Alerts are triggered instantly and teams jump into action; but within minutes, the conversation shifts. Not toward the system—but toward the business, and the questions that begin to emerge are: 

  • Is this affecting customers? 
  • Are transactions failing? 
  • How critical is this right now? 
  • What is the business impact? 

And that’s where things become less clear, because while the system issue is visible, the business impact is not. 

The Gap Between Signals and Meaning 

This is the gap most organizations don’t explicitly talk about. They have signals, data, and visibility, but they lack meaning due to lack of context. 

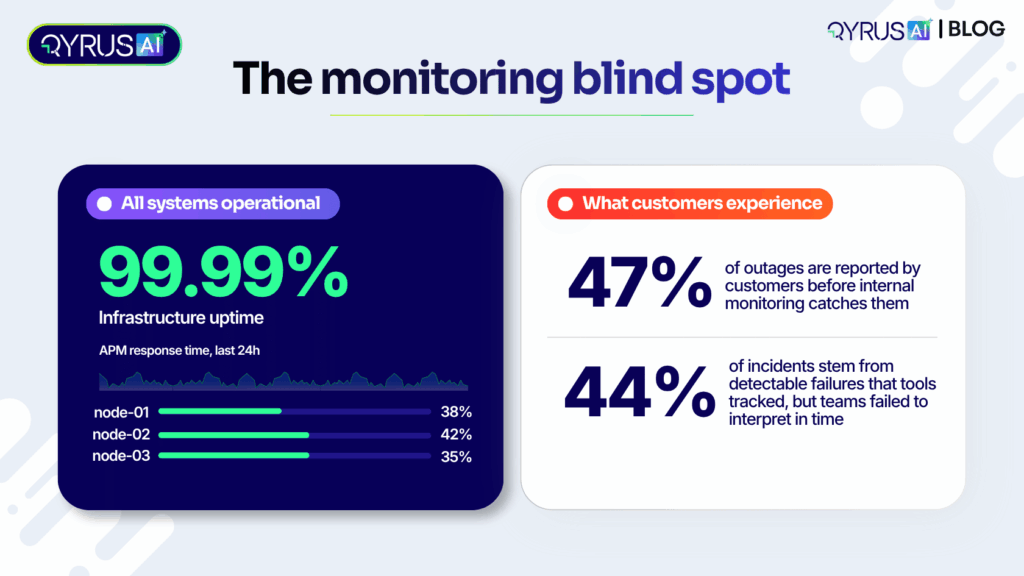
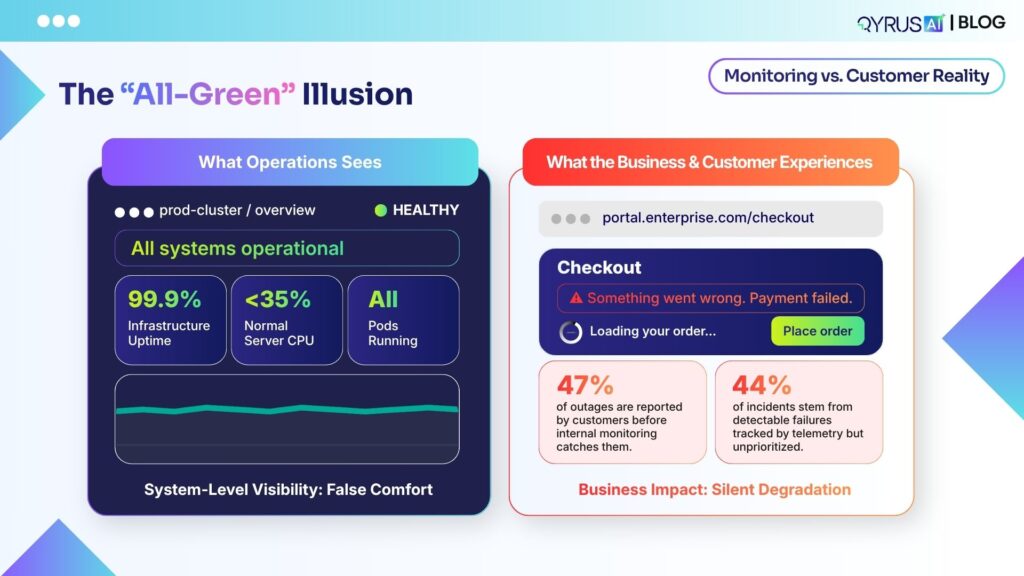
An alert might tell you that something is wrong with a service. It rarely tells you what that service means to the business. In fact, research shows that 44% of IT incidents stem from detectable failures—technical issues that telemetry actively tracked, but teams failed to interpret or prioritize in time. 

Worse yet, 47% of outages are reported by customers before internal monitoring catches them. When dashboards flash green while users struggle to check out or log in, teams are left to interpret, correlate, and guess under pressure. And in that time, critical decisions are delayed.

Why More Data Doesn’t Solve the Problem 

The instinctive response to this gap is usually the same: 

  • Add more data. 
  • Add more tools. 
  • Add more dashboards. 

But the problem isn’t the absence of data. It’s the absence of connection. Modern IT environments are not just collections of systems; they are complex networks of dependencies. 

A single business workflow may span multiple applications, microservices, cloud infrastructure, and third-party APIs. Unless those relationships are dynamically understood, no amount of raw data can provide operational clarity. 

When Everything Looks Important, Nothing Is Prioritized 

Without business context, every alert feels urgent and every issue looks critical. Every team believes their technical problem should be addressed first, creating a subtle but dangerous dynamic. 

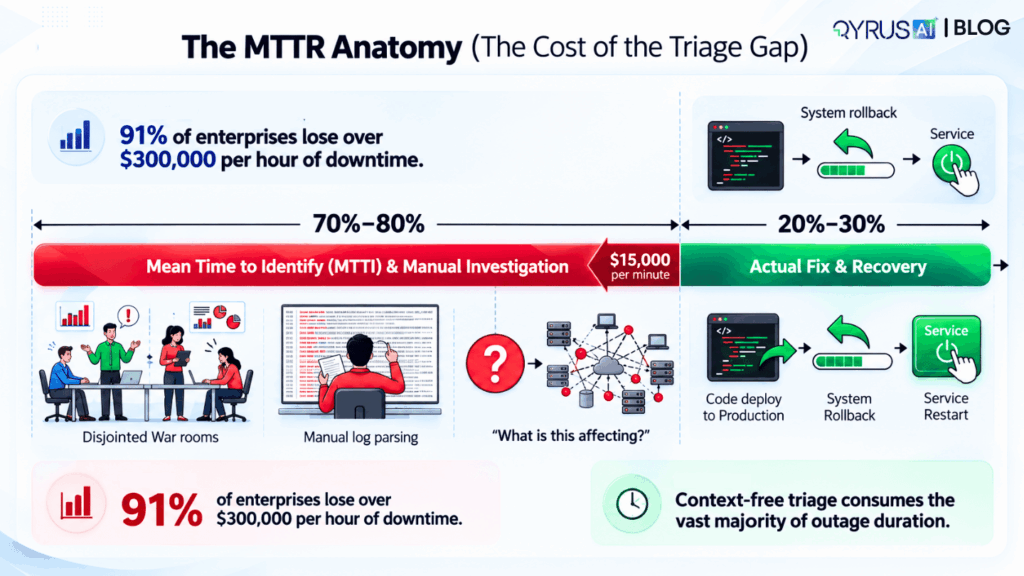
Efforts are spread thin, focus is diluted, and issues that truly move the needle sometimes wait longer than they should. Because teams lack a clear view of business dependencies, 70% to 80% of Mean Time to Resolution (MTTR) is consumed purely by investigation and Mean Time to Identify (MTTI)—manually hunting through logs, assembling war rooms, and figuring out which service broke what workflow. 

The Cost of Misalignment 

This isn’t just an operational inefficiency. It carries severe, measurable consequences: 

  • Incident severity continues to rise: Even as component reliability improves, interconnected architectures mean that 1 in 5 organizations (20%) report their most recent major outage cost over $1 million. 
  • Trust slowly erodes along with enterprise value: When IT cannot clearly communicate business impact, cross-functional alignment fractures and leadership is left flying blind. 

From Visibility to Understanding 

The shift that organizations need is not from less visibility to more. What they need is to move from passive visibility to contextual understanding. 

Understanding how systems support business services and how failures propagate across interdependent entities of a business process defines how effectively you respond. It transforms an ambiguous technical alert into an immediate understanding of what truly matters to the enterprise at any given moment. 

Where QyrusAI Makes the Difference 

QyrusAI bridges this exact gap. As an agentic platform designed to unify the enterprise application lifecycle, QyrusAI connects systems directly to business services, providing the missing layer of contextual intelligence.  

At the center of this approach is QyrusAI’s Live Enterprise Knowledge Graph, which continuously discovers enterprise assets, maps dynamic dependencies, and binds technical telemetry directly to business workflows and transactions.  

This continuous intelligence powers a connected lifecycle across three core pillars:  

  • Modernize: Uncovers application dependencies, illuminates technical debt, and rationalizes complex portfolios with live architectural context.  
  • Assure: Provides automated end-to-end testing across web, mobile, API, SAP, and data pipelines to validate changes before they reach production.  
  • Operate: Delivers full-spectrum BizOps, AIOps, FinOps, and automated incident response, connecting technical signals to customer journeys and business outcomes.  

So when something happens, teams don’t just see an isolated alert. They understand it, they know what business service it affects, and they can prioritize and resolve it with complete confidence.  

Frequently Asked Questions (FAQs) 

Why is component-level visibility no longer enough for modern enterprise IT?

Modern architectures are non-linear and deeply interdependent. A system or microservice can report healthy technical metrics in isolation while an end-to-end transaction (like customer checkout or loan processing) fails across the broader dependency chain.

What is the difference between observability and Business Operations Intelligence (BizOps)?

Observability focuses on capturing telemetry—metrics, events, logs, and traces—to explain technical system states. BizOps and Business Operations Intelligence connect that telemetry directly to business workflows, revenue streams, and customer journeys, translating technical health into business outcomes.

How does QyrusAI prevent alert fatigue during high-severity incidents?

Using its Live Enterprise Knowledge Graph, QyrusAI correlates disparate infrastructure alarms to their underlying business services. Instead of bombarding engineers with hundreds of isolated alerts, it pinpoints the root cause and ranks incidents by actual business and financial exposure.

How does connecting IT to business context accelerate MTTR?

Because 70% to 80% of MTTR is spent on investigation and MTTI, eliminating manual dependency tracing drastically reduces resolution time. Teams immediately see which business service is degraded, which components are responsible, and who needs to take action.
Featured Image

There’s a common assumption in enterprise AI: if you have enough data, AI will work. 

But in reality, that’s rarely the case. 

The Missing Ingredient Isn’t Data 

Most organizations today have: 

  • Vast amounts of data 
  • Modern data platforms 
  • Advanced AI tools 

And yet, many enterprise AI initiatives fail to deliver expected business outcomes. 

Why? 

Because data without context is not intelligence. 

The Problem with Disconnected Data 

Enterprise data is spread across: 

  • Applications 
  • Infrastructure 
  • Cloud platforms 
  • Business systems 

Each dataset exists in isolation, and while data may be accurate, its meaning is often incomplete. 

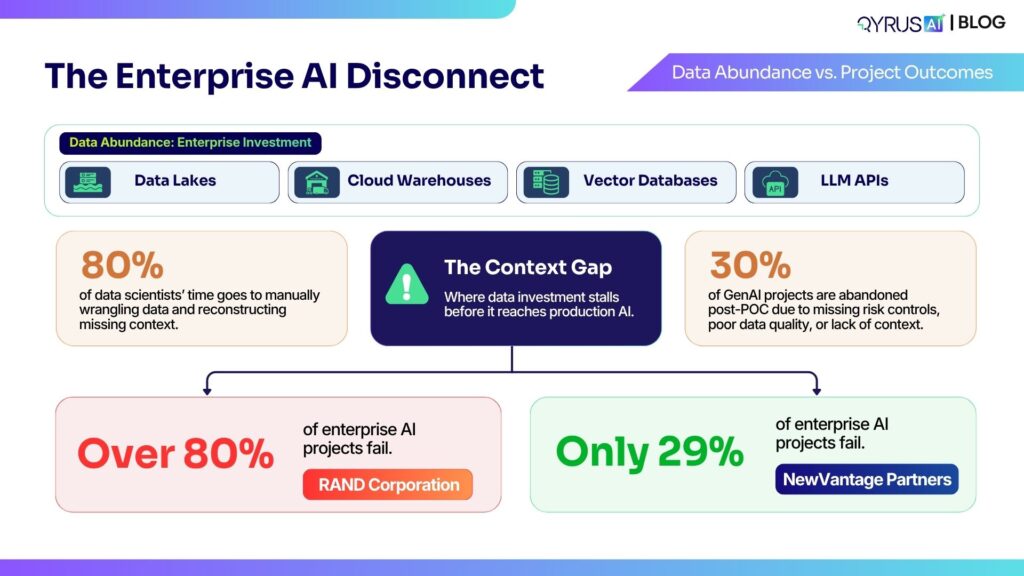
When algorithms ingest fragmented data, they lack the structural relationships that govern how an enterprise actually operates. A comprehensive study by the RAND Corporation found that over 80% of AI projects fail—more than double the failure rate of non-AI corporate technology projects—with researchers identifying a failure to ground models in operational context as the primary culprit. Furthermore, according to NewVantage Partners’ executive benchmark, only 29% of corporate leaders report achieving measurable business outcomes from their AI investments, pointing directly to persistent architectural silos and missing contextual relationships. 

The Enterprise AI Disconnect

Why Context Matters 

For AI to work effectively, it needs to understand: 

  • Relationships between systems 
  • Dependencies across processes 
  • How data flows through the organization 

Without this: 

  • Insights lack relevance 
  • Predictions lack accuracy 
  • Decisions lack trust 

When context is absent, teams burn enormous resources attempting to compensate with brute-force data engineering. Industry analysts at Gartner predict that at least 30% of generative AI projects will be abandoned after proof of concept due to poor data quality, missing risk controls, escalating costs, or unclear business value. Simultaneously, data scientists and engineers still spend up to 80% of their working hours manually preparing, cleaning, and reconstructing disconnected context rather than training and optimizing intelligent models. 

From Data to Understanding 

The shift organizations need is clear: moving from simply collecting data lakes to understanding how data is dynamically connected across systems, workflows, and business outcomes. 

This is where concepts like: 

  • Enterprise knowledge graphs 
  • System-level dependency mapping 
  • Real-time digital twins 

become critical. 

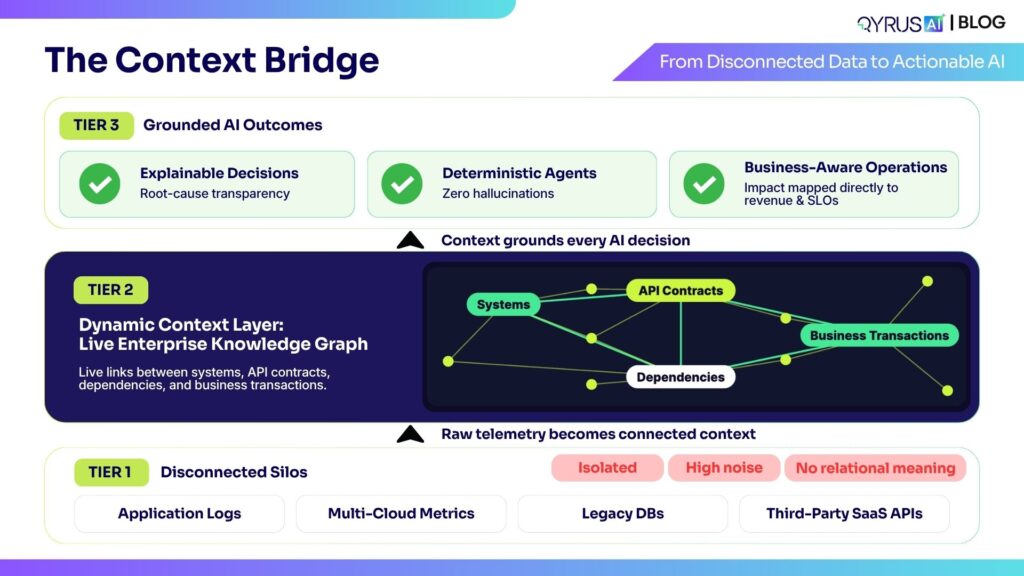
Context provides the semantic anchor that bridges raw technical data and business intelligence. It transforms an isolated metric or log entry into a living relationship: which application produced it, which downstream API consumes it, and which revenue-generating customer journey depends on it. 

The Role of Context in AI 

When AI is powered by continuous context:  

  • Insights become more accurate 
  • Decisions become more reliable 
  • Outcomes become more actionable 

Because the system understands not just what is happening, but why. Context provides the necessary guardrails that eliminate hallucinations, anchor agentic reasoning in verified ground truth, and give human stakeholders the transparency needed to trust algorithmic recommendations. 

Where QyrusAI Fits In 

This is where QyrusAI introduces a connected approach across the enterprise application lifecycle. As an agentic platform, QyrusAI creates a real-time, unified representation of your enterprise to ground AI systems in operational reality. 

At the center of this capability is QyrusAI’s Live Enterprise Knowledge Graph, which continuously discovers enterprise assets, monitors live system interactions, and maps dependencies across services, databases, APIs, and business workflows. 

By combining: 

  • Continuous asset discovery 
  • Dynamic dependency mapping 
  • Knowledge graph intelligence 
The Context Bridge

QyrusAI provides the continuous context layer that enterprise AI systems require[cite: 2]. This intelligence is operationalized across three core pillars:  

  • Modernize: Unpacks legacy architectures, assesses technical debt, and models real-time dependencies so modernization and portfolio decisions are driven by complete system context. 
  • Assure: Delivers continuous, automated testing across web, mobile, API, SAP, and complex data pipelines, verifying data contract integrity and application behavior before changes reach production. 
  • Operate: Brings operational intelligence across AIOps, observability, BizOps, and FinOps, directly correlating technical signals and operational anomalies with business outcomes. 

This enables organizations to:  

  • Build more reliable, hallucination-resistant AI models 
  • Improve explainability and governance across automated decisions 
  • Accelerate time-to-value from AI investments 

Frequently Asked Questions (FAQs) 

  1. Why do enterprise AI projects fail even with massive data lakes?

Data volume is not the same as data understanding. Data lakes store raw data in isolated silos without architectural or business relationships. Without contextual mapping, AI models cannot determine which processes, transactions, or services that data actually influences. 

  1. What is an Enterprise Knowledge Graph, and why does AI need it?

An Enterprise Knowledge Graph is a dynamic, semantic model that connects disparate data assets, applications, and workflows based on real-world relationships. It provides AI models with deterministic context, preventing hallucinations and enabling autonomous agents to reason accurately about complex systems. 

  1. How does QyrusAI provide context to enterprise operations?

QyrusAI uses continuous discovery and automated dependency mapping to build a Live Enterprise Knowledge Graph. This connects raw telemetry, data pipelines, and infrastructure to the specific business workflows they support.

  1. How does contextual intelligence improve AI governance and explainability?

When AI makes a recommendation or triggers an automated remediation, context reveals the exact dependency path and reasoning behind the decision. This transparency makes models auditable, safe, and trustworthy for enterprise leadership.  

The Bottom Line 

AI doesn’t fail because of a lack of data. It fails because of a lack of context. 

The question that helps you separate experimentation from real impact is no longer: 

“Do we have enough data for AI?” 

It is: 

“Do we understand our data well enough for AI to work?” 

Ready to move from disconnected data to contextual intelligence? 

Discover how QyrusAI connects your data, systems, and business outcomes into a living operational Knowledge Graph.

Talk to an Expert 

Business Impact in IT Operations

The Cost You Can Measure and the Cost You Can’t 

Enterprises are very good at measuring certain things like: 

  • Infrastructure spend. 
  • Cloud usage. 
  • Licensing costs. 

These numbers are visible, trackable, and often discussed. But there’s another category of cost that rarely appears clearly on any dashboard and that is the cost of not understanding business impact. 

When an Incident Happens 

Consider a typical incident. An application slows down, an alert is triggered and teams begin investigating. 

But before anything else, there’s uncertainty. 

  • Is this affecting a critical service? 
  • Are customers impacted? 
  • Is revenue at risk? 

And until these questions are answered, the response remains cautious. Or at worst misdirected. 

The Cost of Delay 

In many cases, the biggest cost is not the incident itself. It’s the time taken to understand its impact. Because during that time: 

  • Teams are aligning across functions 
  • Information is being gathered manually 
  • Decisions are being deferred 

And all of this adds up, minutes turn into hours and the impact grows. 

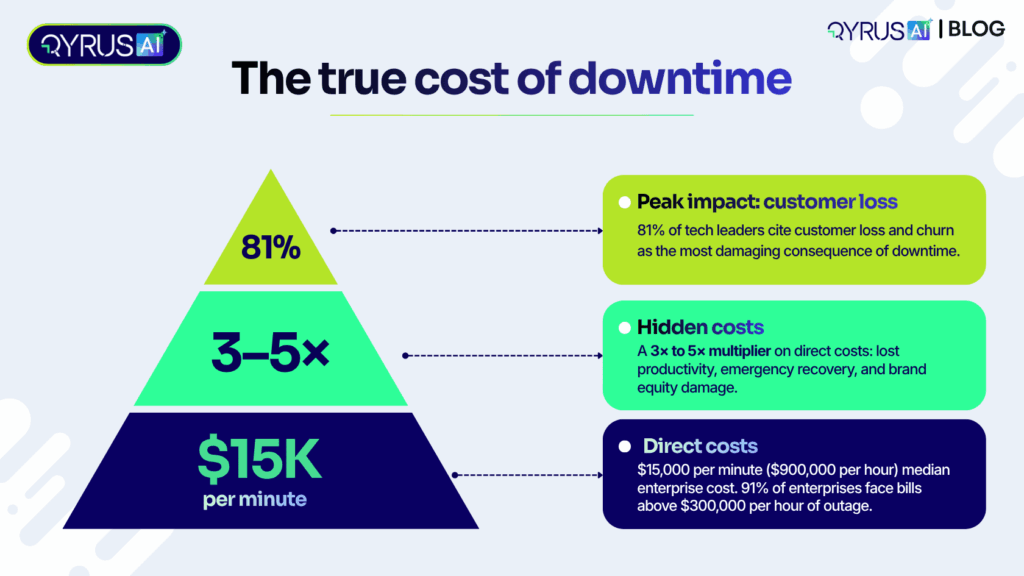
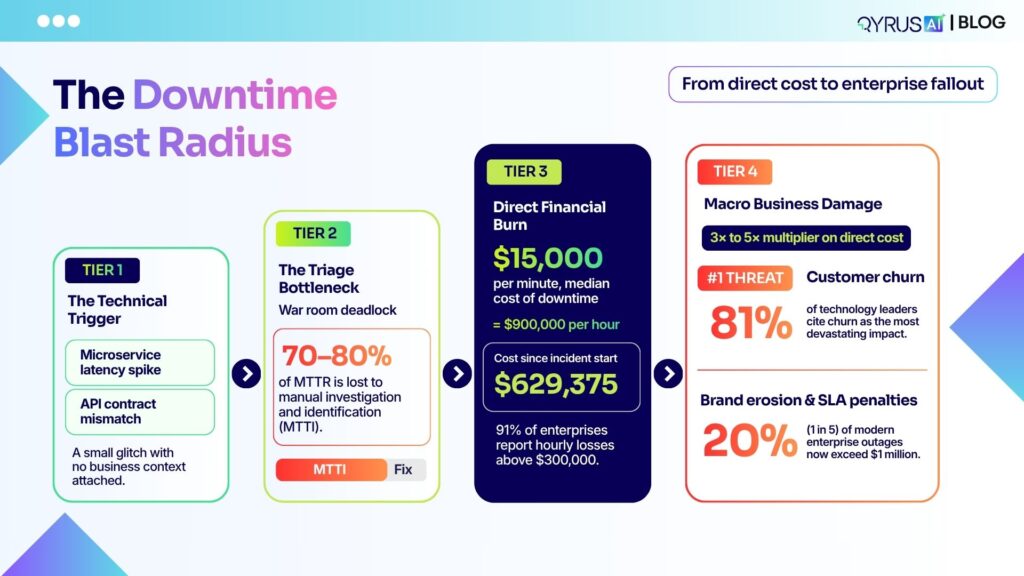
Industry benchmarks indicate that 70% to 80% of Mean Time to Resolution (MTTR) is spent solely on investigation and Mean Time to Identify (MTTI)—manually tracing dependencies, gathering logs, and determining what broke. When the median enterprise cost of downtime has climbed to approximately $15,000 per minute ($900,000 per hour), every minute spent searching for context in an active war room translates directly into catastrophic financial exposure. Furthermore, 91% of enterprises report that a single hour of IT downtime costs them more than $300,000. 

MTTR Breakdown

When Effort Doesn’t Match Importance 

Without clear business context, teams often fall into a common pattern. They respond to what is visible, not what is important. A technically complex issue may get immediate attention while a business-critical issue, if less visible, may take longer to surface. This misalignment is subtle but over time, it becomes expensive for the business. 

Research reveals that 44% of IT incidents stem from detectable failures—technical issues that telemetry monitored, but teams failed to interpret or prioritize correctly in time. Worse yet, 47% of outages are reported by customers before internal monitoring catches them, exposing how traditional component alarms leave operational teams blind to real customer journeys and transactional bottlenecks. 

The Ripple Effect Across the Organization 

The lack of business impact visibility doesn’t just affect IT. It affects: 

  • Business teams waiting for updates 
  • Leadership trying to make decisions 
  • Customers experiencing disruptions 

And because the impact is not clearly understood, communication becomes fragmented. Different teams operate with different assumptions. The result is an accelerated sense of chaos. 

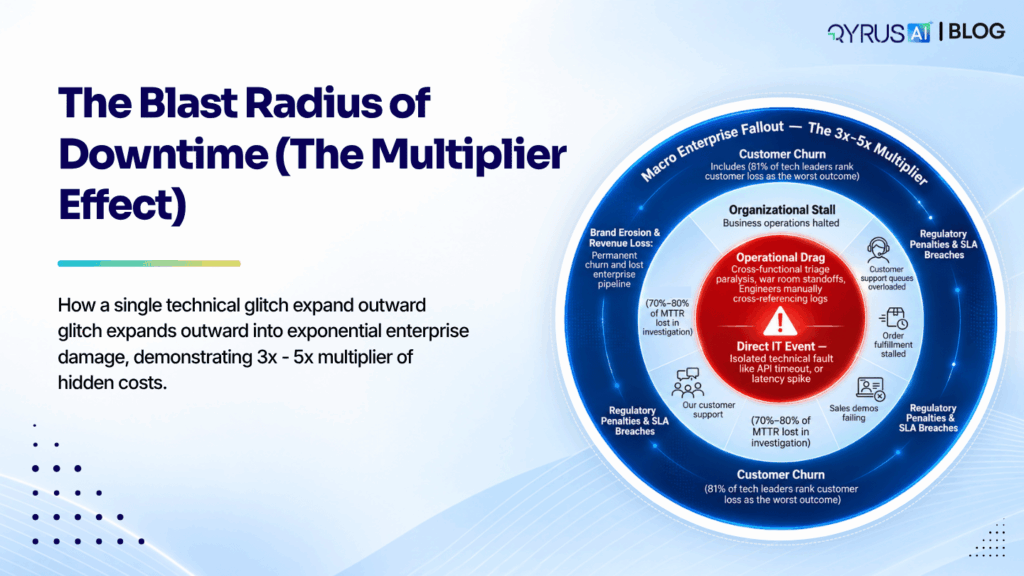
The true toll extends far beyond immediate remediation fees. Studies indicate that enterprises face 3x to 5x hidden costs—encompassing lost cross-departmental productivity, regulatory penalties, and brand equity damage. In fact, 81% of technology leaders cite customer loss and churn as the most damaging long-term consequence of operational downtime. 

The Downtime Blast Radius

Why This Problem Persists 

Most organizations do not intentionally ignore business impact. They simply lack a way to see it in real time. This is because systems and business services are not clearly connected. Without that connection, the true nature and quantum of impact has to be guessed and this is both often inaccurate and risky. 

This blind spot is a primary driver behind why 1 in 5 organizations (20%) report that their most recent major outage exceeded $1 million in total losses. Across the Global 2000, unplanned downtime siphons an estimated $400 billion annually—not because telemetry was missing, but because isolated signals lacked structural and commercial context. 

From Reaction to Clarity 

The organizations that handle this well do something differently. They don’t wait to understand impact after an incident. They already know it. Because their systems are mapped to business services, the dependencies are visible and the context is always available. This helps to avoid decisions that come from inaccurate guesswork. 

Where QyrusAI Fits In 

QyrusAI enables this shift by connecting systems to business services and continuously mapping dependencies, allowing organizations to understand impact instantly. 

As an agentic platform designed to unify the enterprise application lifecycle, QyrusAI grounds operational workflows across three core pillars: 

  • Modernize: Unpacks legacy architectures, illuminates hidden technical debt, and rationalizes application portfolios with comprehensive dependency context. 
  • Assure: Delivers continuous, automated testing across web, mobile, API, SAP, and data pipelines to catch defects long before code reaches production. 
  • Operate: Brings actionable operational intelligence across AIOps, observability, BizOps, and FinOps, directly correlating infrastructure alerts with customer journeys and business outcomes. 

At the core of the platform is QyrusAI’s Live Enterprise Knowledge Graph, which maintains a continuously observed, real-time model of applications, integrations, and business processes. 

So instead of asking: 

“What does this affect?” 

Teams already know. And instead of delaying decisions, they act immediately with clarity. 

Frequently Asked Questions (FAQs) 

  1. What is the hidden cost of IT downtime?

The hidden cost refers to secondary and long-term damages—such as lost employee productivity, brand erosion, missed sales opportunities, regulatory penalties, and customer churn. Research shows these indirect damages are typically 3x to 5x higher than the immediate direct costs of system recovery. 

  1. Why does traditional IT monitoring fail to identify business impact?

Traditional monitoring tracks component-level telemetry (CPU, memory, server uptime, network packets) in isolation. It cannot determine whether a 500ms database delay affects a non-critical background task or halts an active checkout flow for high-tier enterprise clients. 

  1. How does QyrusAI establish real-time business context?

QyrusAI utilizes its Live Enterprise Knowledge Graph to continuously discover assets, map dynamic dependencies, and bind technical telemetry directly to business services, workflows, and KPIs. This ensures teams see the commercial blast radius of any incident in real time. 

  1. How does understanding business impact reduce Mean Time to Resolution (MTTR)?

Because 70% to 80% of MTTR is typically spent on investigation (MTTI), providing immediate topological and business context eliminates the guesswork. Teams instantly know which service is broken, which business workflow is impacted, and who needs to remediate it. 

The Bottom Line 

The cost of not understanding business impact is not always visible, it shows up in: 

  • Delayed responses 
  • Misaligned priorities 
  • Increased disruption 

The real question to ask here is: 

How much is uncertainty costing you today? 

Still reacting before understanding impact? 

See how QyrusAI helps you identify, prioritize, and act on what truly matters to your business in real time. 

Talk to an Expert 

Most enterprise IT environments weren’t designed. They accumulated. A system that ran fine on its own five years ago has since picked up two integrations, a merger’s worth of inherited applications, and a handful of workarounds nobody documented. None of that shows up as a problem, until someone tries to change it.  

That’s the real challenge behind modernization: it’s rarely about deciding whether something needs updating. It’s about knowing what else gets affected when it is. Application discovery and dependency mapping is how enterprise architects, IT operations teams, and CIOs answer that question, by building an accurate picture of what’s actually running across an environment and how each piece depends on the rest, before anything gets touched.  

What Application Discovery and Dependency Mapping Actually Means  

Application discovery and dependency mapping is really two linked steps. Discovery identifies what exists — the applications, services, servers, and infrastructure running across an environment. Dependency mapping traces how those pieces connect: which service calls which database, which application sits on top of which infrastructure, and which business process breaks if a given component goes down.  

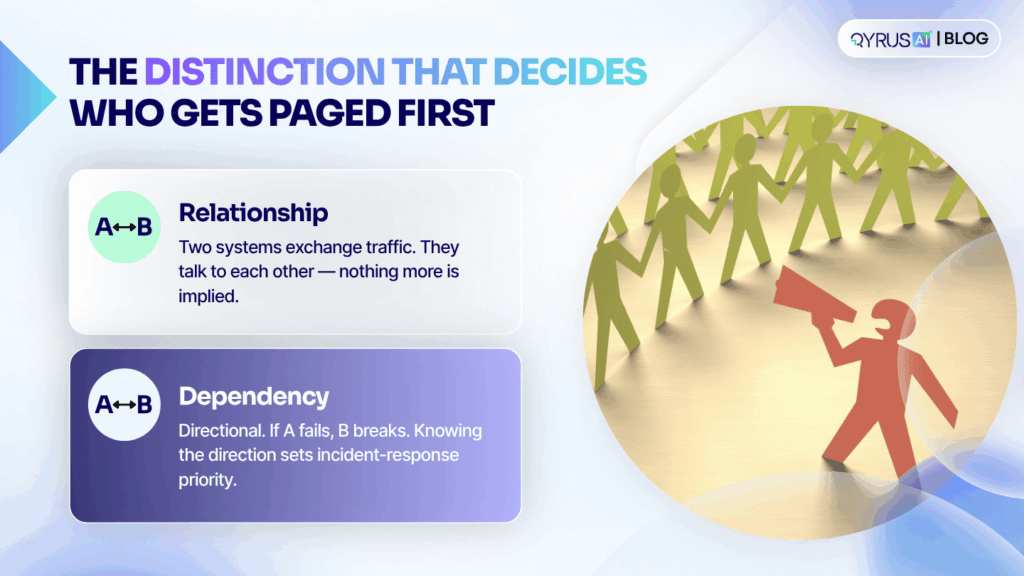
That second part carries more weight than it first appears to. A relationship just means two systems exchange traffic, they talk to each other. A dependency is directional: it means one system’s failure will break another. A payment gateway and an authentication service might have a relationship in a topology diagram, but if the authentication service fails, the payment gateway is the one that stops working, not the other way around. Knowing which direction that failure travels is what determines who gets paged first during an incident, and what teams prioritize before a planned change.  

Static inventories and manually maintained configuration management databases (CMDBs) were built for slower-moving environments. They capture what’s there at a point in time, but they don’t hold up once infrastructure starts changing weekly instead of quarterly, which is now the norm, not the exception, for organizations running hybrid cloud and containerized workloads.  

Why This Is Harder Than It Used to Be  

Enterprise environments have gotten more complex faster than the tools tracking them have kept pace. A typical environment today spans hybrid cloud infrastructure, containerized microservices, distributed APIs and SaaS applications, and infrastructure that scales continuously rather than on a fixed schedule. Layer in a few acquisitions or a legacy system nobody’s fully documented, and the gap between what’s on paper and what’s actually running starts to widen.  

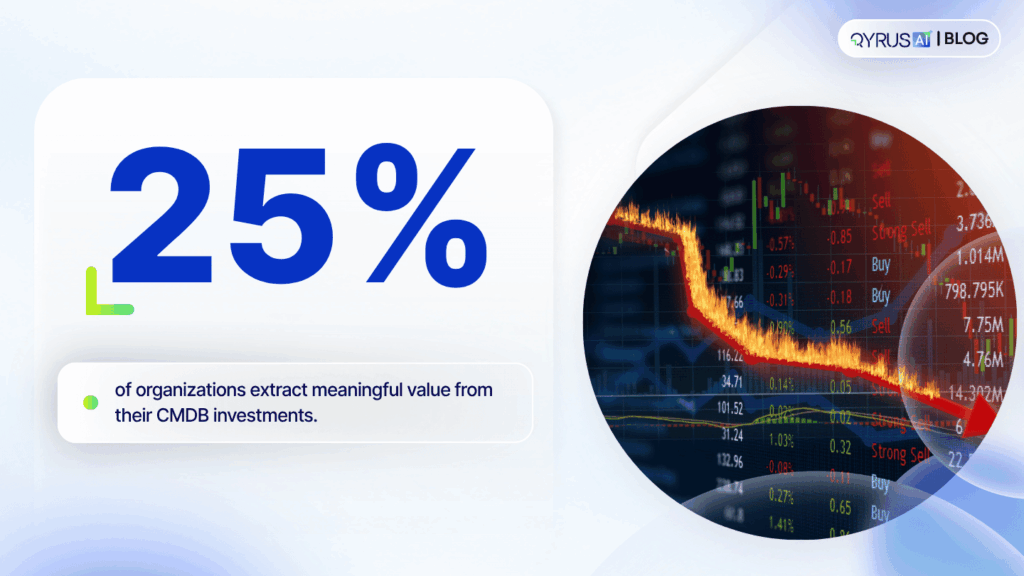
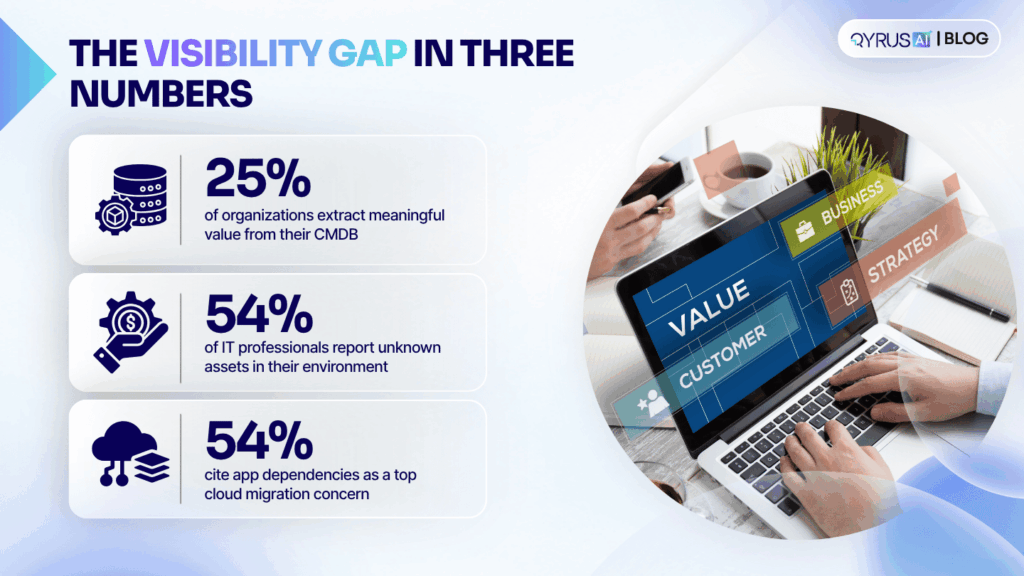
The numbers back this up. Gartner has found that only 25% of organizations extract meaningful value from their CMDB investments, the rest are working from data that’s incomplete, stale, or simply not trusted enough to act on. Separately, Forrester research cited by Virima found that 54% of IT professionals report unknown assets in their environments, systems nobody currently tracks are still running, still connected to something else, and still capable of breaking a change nobody saw coming.  

That visibility gap has a direct line to project risk. Application dependencies are one of the most commonly cited concerns IT teams raise about cloud migration projects, and budget overruns tied to unplanned rework are common enough that they show up in nearly every year’s IT leadership surveys. Periodic discovery scans and manually updated spreadsheets can’t keep up with environments that change this often, which is why the shift underway across the industry is toward continuous, automated discovery instead.  

From Discovery to a Living Model: The Knowledge Graph  

A one-time discovery scan produces a snapshot, accurate the day it’s run, and progressively less accurate after that. Continuous discovery instead produces something closer to a living model: infrastructure changes get detected automatically, dependencies stay current as the environment evolves, and the resulting map doesn’t need to be manually reassembled every time someone asks for it.  

The more useful shift is what happens to that discovery data next. Rather than sitting in a dashboard as a point-in-time diagram, discovered assets and their dependencies can feed into a persistent knowledge graph, a structured, queryable model of the environment that stays current as things change. That’s a meaningfully different architecture than “run a scan, export a report.” It turns discovery into infrastructure other systems can build on: incident response tools that can trace an issue back through its dependency chain automatically, planning tools that can simulate the impact of a proposed change, and automation that can act on accurate, current context instead of a document that was correct six months ago.  

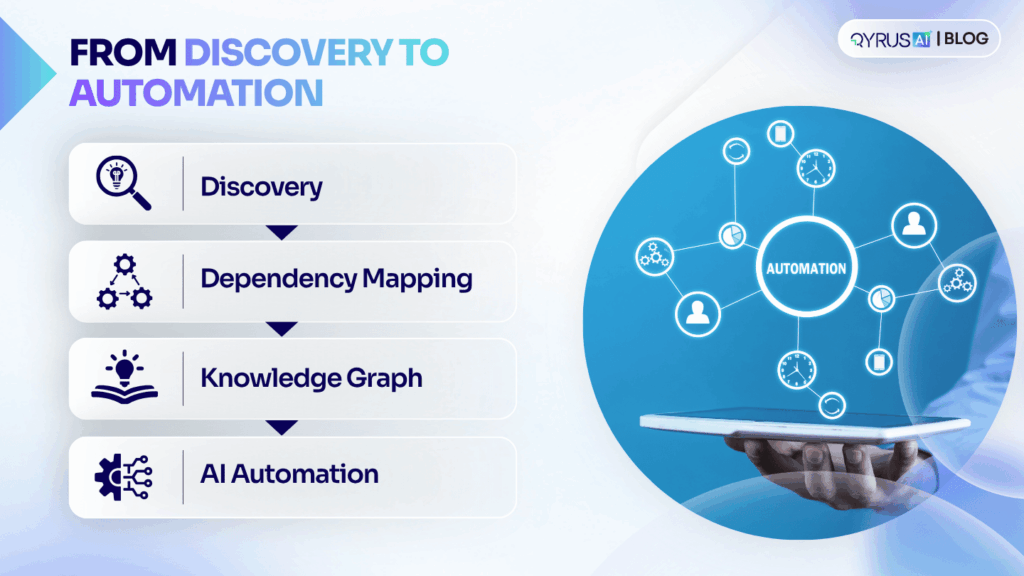
Put together, the pattern looks like a pipeline rather than a single tool: discovery identifies what’s running, dependency mapping traces how it connects, a knowledge graph holds that model in a form other systems can query, and from there, automated and AI-driven operations become possible because they’re finally working from something trustworthy. Skip the first two steps, and everything built on top of them inherits the same blind spots.  

Where This Shows Up: Cloud Migration  

Cloud migration is where the cost of skipping discovery becomes concrete fastest. Moving an application to the cloud is rarely just moving the application. It may depend on a database that isn’t moving on the same timeline, communicate with a service that stays on-premises, or support a larger business process that spans systems nobody thought to check.  

If those dependencies surface after the move, the project has a problem: a service that worked fine in testing breaks in production because something it depended on didn’t come along or came along on a different schedule. If they surface beforehand, the same information becomes a planning input instead of an incident. Teams can sequence the migration around what actually needs to move together, flag the dependencies that need special handling, and set expectations before a cutover date gets missed.  

This is also where discovery connects to the rest of the modernization lifecycle rather than standing apart from it. The same dependency data that de-risks a migration is what later informs application rationalization — deciding which systems are redundant or safe to retire — and technical debt assessment, which starts from knowing what’s actually in the environment before deciding what to fix. Discovery isn’t a standalone exercise; it’s the input every later modernization decision draws on.  

How QyrusAI Approaches Auto Discovery  

QyrusAI is an enterprise AI platform built around three workspaces — Modernize, Assure, and Operate — covering how organizations understand, test, and run their IT environments. Auto Discovery sits under Modernize, where it works alongside dependency mapping, application rationalization, and technical debt analysis to help enterprise teams understand what they’re working with before they change it.  

Auto Discovery continuously scans an organization’s IT environment across cloud, on-premises, and hybrid infrastructure, identifying what’s actually running, applications, services, infrastructure, and mapping the dependencies between them. It traces those relationships upstream and downstream and feeds the results into QyrusAI’s Enterprise Knowledge Graph, building a continuously updated model of the environment rather than a static diagram that has to be manually maintained.  

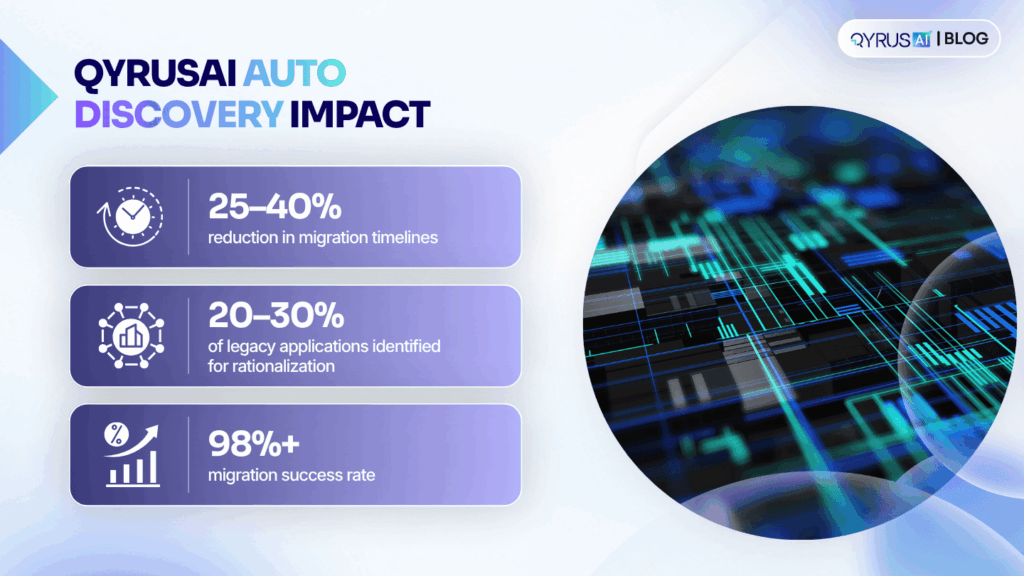
That shift from periodic to continuous, knowledge-graph-backed discovery shows up in the numbers: organizations applying this approach to their modernization lifecycle have seen a 25–40% reduction in migration timelines, 20–30% of legacy applications identified for rationalization, and a 98%+ migration success rate, driven by earlier, more accurate dependency visibility rather than late-stage surprises. The goal isn’t just a more complete inventory — it’s giving teams a foundation they can actually plan against before a project starts, not one they reconstruct after something breaks.  

Frequently Asked Questions  

What’s the difference between application discovery and dependency mapping?  

Discovery identifies what’s running in an environment — applications, services, infrastructure. Dependency mapping traces how those components connect and rely on each other. They’re typically delivered together because discovery data is what dependency mapping is built from.  

Is application discovery and dependency mapping the same as a CMDB?  

No. A CMDB is a database that stores configuration item records, often updated manually or on a schedule. Application discovery and dependency mapping is the process — increasingly automated and continuous — that keeps that data current and can feed directly into a CMDB rather than replace it.  

How often should IT environments be re-discovered?  

As close to continuously as the tooling allows. Environments that scale, deploy, or reconfigure weekly can go stale within days under a periodic scan model, which is why the industry trend is toward continuous, automated discovery rather than scheduled scans.  

Does application discovery work across hybrid and multi-cloud environments?  

Modern discovery tools are generally built to span cloud, on-premises, and hybrid infrastructure in a single pass, rather than requiring separate tools per environment. That unified view is what makes dependency mapping useful — a dependency that crosses environments is invisible if the discovery tool only sees one side of it.  

What happens if you skip dependency mapping before a migration?  

Dependencies tend to surface anyway — just later, and usually as an incident instead of a planning input. A database, service, or business process that wasn’t accounted for can break after a cutover, turning a planned migration into unplanned rework.  

Understand It Before You Change It  

Modernization projects don’t start with the first change — they start with understanding what’s already there. Application discovery and dependency mapping gives enterprise architects, IT operations teams, and CIOs the visibility to plan migrations, rationalize applications, and manage change with fewer surprises along the way.  

QyrusAI’s Auto Discovery continuously maps environments across cloud, on-premises, and hybrid infrastructure and feeds that model into the Enterprise Knowledge Graph — giving teams a current, connected view of their systems rather than a static inventory. Request a demo to see how QyrusAI Auto Discovery maps your environment before you modernize it. 

Everything you need to know about LLM, AI agents and Evaluation

What is an LLM Tool? 

A LLM tool is like a application, interface, or integration that exposes the reasoning capabilities of a large language model to end users or downstream systems. It covers features right from a simple chatbot to an API to a fully autonomous agent that can browse the web, writes code, executes files, and completes multi-step workflows without human input in the loop.  In simplest terms, every LLM tool shares three components: a language model (as AI reasoning engine), an interface layer (to interpret how humans or machines communicate with it), and an integration layer (how it connects to real data, APIs, and actions in the world).

Here’s something you should know 

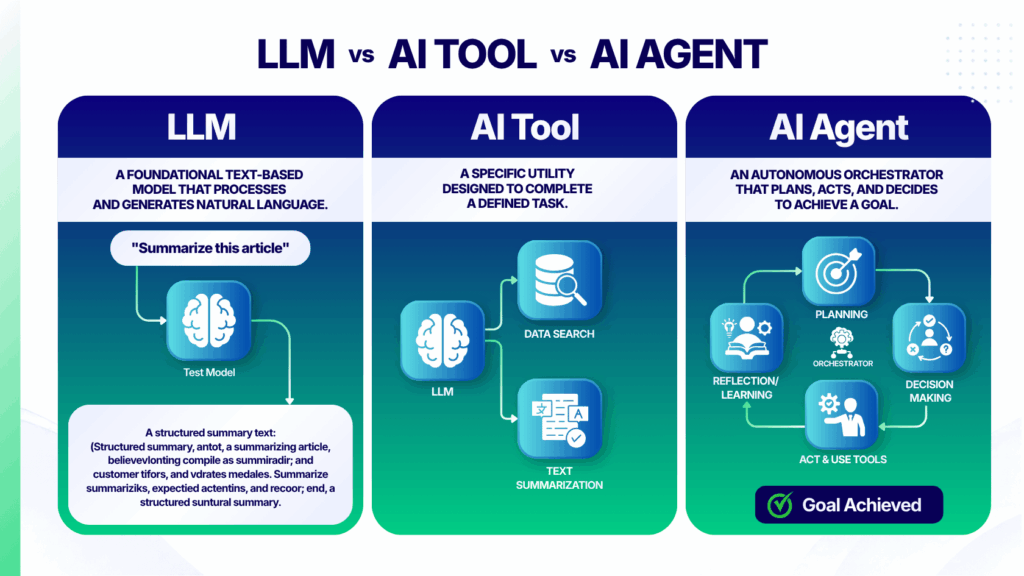
LLM vs AI Tool vs AI Agent 

These three terms are used interchangeably in most conversations — and that confusion is expensive. An LLM, an AI tool, and an AI agent are fundamentally different things with different capabilities, different failure modes, and very different evaluation requirements. Understanding the distinction is the first step to building or deploying any of them responsibly. LLM vs AI agents vs AI

Side-by-side comparison 

  LLM  AI Tool  AI Agent 
Acts on its own?  No  Within scope  Yes — until goal met 
Has memory?  Context window only  Session-level  Persistent across steps 
Uses tools?  No  Predefined set  Dynamic selection 
Self-corrects?  No  No  Yes — reflects and retries 
Eval complexity  Output scoring  Output + integration  Trajectory + goal + safety 
Autonomy  Low  Medium  High 
 

Why LLM Tools Are Different from Traditional Software 

Traditional software is designed to be deterministic. So it can give the same input and it will always produce the same output. But LLM tools are built to be probabilistic — outputs are generated by sampling from a learned distribution over language. This single difference changes everything: testing, debugging, monitoring, and quality assurance all require entirely new paradigms.  Traditional software fails loudly. It crashes, throws errors, returns null. LLM tools fail silently. They generate confident, grammatically correct, beautifully structured text that happens to be wrong, biased, or dangerous. This is why evaluation — the practice of measuring LLM output quality systematically — has become one of the most critical disciplines in modern AI engineering. 

Why the Distinction Matters for Evaluation 

The gap between these three categories is not just conceptual — it directly determines how hard evaluation is. An LLM needs output scoring: is this response accurate, relevant, safe? An AI tool needs integration accuracy on top: did it call the right API with the right parameters?   An AI agent needs all of that plus trajectory evaluation: did it follow the right path, make the right tool choices at each step, and achieve the actual goal without unintended side effects?  This is why QyrusAI is built as an end-to-end evaluation platform — not just an output scorer. As you move from LLM to tool to agent, the surface area for failure grows exponentially. The evaluation framework must grow with it. 

Now, What Does It Actually Take to Build an LLM Tool? 

Building an LLM tool in 2026 is more accessible than ever — but the gap between a working prototype and a production-grade system remains vast. The prototype takes hours. The production system takes months. The difference is almost never the model itself — models are commoditizing fast.  

The Six-Layer Stack 

  1. Foundation Model Selection 
    • Closed frontier models (GPT-4o, Claude, Gemini) offer capability with minimal setup. Open-weight models (Llama 3, Mistral) offer cost control, data privacy, and fine-tuning flexibility.  
  2. Prompt Engineering Layer 
    • System prompts, few-shot examples, chain-of-thought scaffolding, and output format instructions shape model behavior before a single feature is written. Well-engineered prompts are the fastest lever for quality improvement — and the most underestimated engineering surface.
  3. Context & Memory Management 
    • LLMs have finite context windows. Production tools must carefully manage what goes into each inference call: conversation history, long-term user memory, retrieved documents, tool outputs.   
  4. Tool & API Integration 
    • Modern LLMs call external tools via function calling or the Model Context Protocol (MCP). Each integration — search, database, calendar, code execution, CRM — multiplies the surface area for failures and requires its own evaluation criteria to catch regressions.  
  5. Orchestration Layer 
    • For agentic workflows, orchestration manages agent state, tool routing, retries, and multi-step task decomposition. Frameworks like LangGraph, OpenAI’s Agents SDK, and Qyrus’s SEER provide the primitives.  
  6. Evaluation & Observability Infrastructure 
    • Every production LLM tool needs logging, tracing, and automated evaluation. Without it, teams cannot detect regressions, understand failure modes, or improve systematically.  

How LLMs Actually Work 

A large language model is a probabilistic function that maps sequences of tokens to probability distributions over the next token. Train it on enough text and it learns to model the statistical structure of language at a depth that produces remarkable emergent capabilities — reasoning, translation, coding, logical deduction — that were never explicitly programmed. 

The Transformer Architecture 

Every major LLM — GPT-4, Claude, Gemini, Llama — is built on the Transformer architecture introduced by Google in 2017. Its core innovation is the attention mechanism: a mathematical operation that allows every token in a sequence to dynamically attend to every other token, learning which relationships matter for predicting what comes next. 

The Attention Mechanism 

Attention is the reason LLMs understand that “it” in a paragraph refers to a noun from three sentences back. For every token, attention computes a weighted combination of all other tokens in context, where the weights are learned across billions of training examples. The formula: Attention(Q,K,V) = softmax(QKᵀ / √d) · V. Each token acts simultaneously as a Query (what am I looking for?), a Key (what do I represent?), and a Value (what information do I carry?). 

Pre-training and Alignment 

LLMs are trained in two phases. Pre-training exposes the model to hundreds of billions to trillions of tokens — internet text, books, code, scientific papers. The objective is simple: predict the next token. At scale, this simple objective produces emergent capabilities in reasoning, translation, and logic that were never explicitly programmed. 

Fine-tuning and alignment  

then adapts the raw model into a useful assistant. RLHF (Reinforcement Learning from Human Feedback) trains the model to prefer outputs rated highly by humans. Constitutional AI, used by Anthropic, trains self-critique using a set of principles. These alignment techniques are what transform a raw language predictor into a safe, helpful product. 

How Large Data Drives Large Decisions 

One of the most profound shifts in computing history is that modern AI systems are capable to make better decisions not primarily because of better algorithms — but because they trained on more data. This is a fundamentally different category from classical software engineering. 

Scaling Laws 

Research from OpenAI, DeepMind, and others established empirical scaling laws: as you increase training compute, dataset size, and model parameters together, model capability improves predictably on a smooth power-law curve. The Chinchilla paper (Hoffmann et al., 2022) showed that most large models at the time were undertrained — the optimal strategy is to scale data and parameters together in balance.  Practically, this means the model powering your customer service chatbot has “read” the equivalent of millions of books, billions of web pages, and hundreds of millions of lines of code. When it answers a contract law question, it draws on patterns from thousands of real legal documents. When it writes Python, it has processed more code than any human could read in a lifetime. 

The Data Flywheel Effect 

The most defensible AI companies are not the ones with the best architecture today — they are the ones building data flywheels. More users generate more interactions. More interactions generate labeled feedback.   Here labeled feedback produces better fine-tuned models. Better models attract more users. This loop is the real competitive moat in AI — not cleverness, not model architecture, but data velocity.  OpenAI has over 400M weekly ChatGPT users. Google has it through Search and Workspace. Anthropic is building it through enterprise Claude adoption. The companies that win the next five years will be those who can convert user interactions into high-quality training signal at the highest speed — and measure that signal accurately with evaluation infrastructure. 

From Data Volume to Decision Quality 

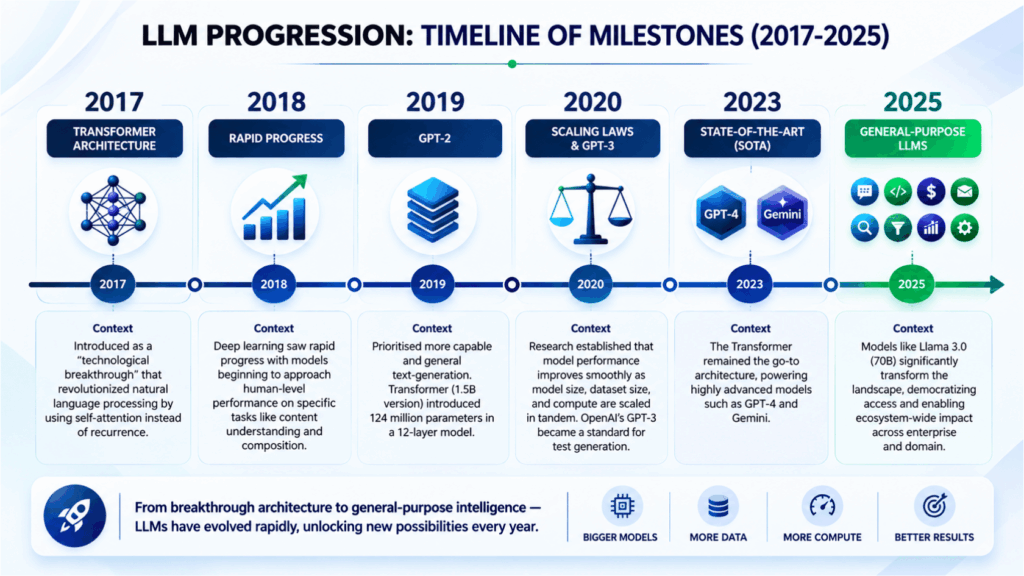
In healthcare, LLMs trained on clinical notes assist with differential diagnosis. In finance, models trained on earnings transcripts help analysts identify patterns across thousands of filings simultaneously. In legal, models trained on case law surface relevant precedents faster than any human search ever could.  LLMs don’t “know” things the way humans do. They are sophisticated compression and interpolation machines that give responses in human-generated text. Their limitations comes from the breadth and depth of their training data.   LLM Progression over the time

The LLM Progression 

How Did We Get Here? 

The honest answer to “what can an LLM do?” depends entirely on when you’re asking. In 2018, the answer was: complete sentences, sometimes coherently. In 2025, the answer is: write production software, pass bar exams, conduct multi-step research, operate computers autonomously, and reason through problems that stumped AI systems for decades. That gap — seven years — represents the most rapid capability expansion in the history of computing. 

2018–2019: Plausible text, unreliable reasoning 

The first generation of Transformer-based LLMs (GPT-1, BERT, GPT-2) was able to produce grammatically coherent text and perform narrow NLP tasks — sentiment classification, named entity recognition, basic question answering.   GPT-2, released in 2019 with 1.5 billion parameters, was considered dangerous enough that OpenAI staged its release. Looking back, it could barely maintain topic coherence across three paragraphs.   The capability was limited to: fluent sentences on familiar topics, with frequent factual drift and no ability to follow multi-step instructions reliably. 

2020: The emergent leap — GPT-3 and few-shot learning 

Post Covid GPT-3 (175B parameters) changed the fundamental question from “can LLMs do task X?” to “how well can LLMs do task X with the right prompt?” It demonstrated few-shot learning — the ability to learn a new task from just 2–3 examples in the prompt, without any weight updates.  This had never been seen at scale before. Suddenly a single model could translate between languages it was never explicitly trained to translate, write code in frameworks it had only seen mentioned, and draft legal language with good reasonable structure.   The capability unlock was the highlight — one model, many tasks, no retraining required. 

2021–2022: Instruction following and alignment 

Raw capability means little if the model won’t do what you ask. InstructGPT (2021) introduced RLHF — training the model to follow instructions rather than just predict likely text.   This was the transition from “impressive research” to “usable product.” Models now started being able to maintain personas, follow formatting instructions, refuse harmful requests, and produce outputs shaped around human preferences rather than before. ChatGPT in November 2022 was the product manifestation of this alignment work — and reached 100 million users in 60 days.  During this same period, code generation became a serious capability. GitHub Copilot launched in 2021, trained on billions of lines of public code. By 2022, developers were reporting that Copilot was completing 25–40% of their code automatically. The model had learned not just syntax but idioms, patterns, library conventions, and common debugging strategies. 

2023: Multimodality, long context, and reasoning 

GPT-4 (March 2023) came with two step changes: multimodal input (the model could now see images, not just text) and dramatically improved reasoning. It passed the bar exam in the 90th percentile.  It scored at or above human performance on multiple professional certification exams. Chain-of-thought prompting — asking the model to reason step by step before answering — unlocked latent reasoning capabilities that had always been in the weights but were inaccessible with direct-answer prompting.  Context windows grew from 4K tokens (GPT-3) to 32K (GPT-4) to 100K (Claude 2). This meant LLMs could now process entire codebases, legal contracts, or research papers in a single pass — tasks that previously required chunking, retrieval pipelines, and significant engineering overhead. 

2024: Tool use, agents, and computer control 

The capability frontier shifted from what a model could say to what a model could do. Function calling — introduced as a first-class feature in mid-2023 and matured through 2024 — let LLMs call external APIs, query databases, run code, and trigger workflows. The model was no longer just a text generator; it was a reasoning engine that could take actions in systems.  By late 2024, Anthropic shipped Claude for Computer Use with the ability for an LLM to see a computer screen, move the cursor, click, type, and operate arbitrary software like a human operator. OpenAI launched Operator on similar principles.   GitHub’s 2024 report found that 46% of all new code written on the platform was AI-generated. LLMs had moved from helping write code to writing the majority of it. 

2025: Agentic reasoning and multi-step autonomy 

The current capability frontier is agentic — LLMs are now operating as autonomous orchestrators that decompose goals, plan sequences of actions, execute them across multiple tools and systems, observe results, self-correct, and iterate until a goal is achieved. This is not a chatbot anymore.  This is software that can be given a business objective — “research competitors and produce a positioning brief,” “audit our API responses for compliance issues,” “set up the dev environment from scratch” — and pursue it without human input at each step.  The o1 and o3 model families introduced extended chain-of-thought reasoning — models that “think” before responding, spending compute on internal reasoning traces before producing output.  On mathematical olympiad benchmarks, these models moved from near-zero performance (GPT-3 era) to exceeding PhD-level performance on many problem classes. DeepSeek R1 demonstrated that this reasoning capability can emerge from reinforcement learning without supervised examples — a fundamental shift in how capability is developed. 

The Rise of Agentic AI 

For the first two years of the generative AI era, most LLM products were reactive: a user sends a message, the model responds, the loop ends. Agentic AI breaks this pattern entirely. An AI agent perceives its environment, makes decisions, takes actions, and operates across multi-step workflows — often without human intervention at each step.  This shift — from reactive LLMs to agentic systems — is the most significant transition in AI since ChatGPT’s release. It transforms LLMs from sophisticated autocomplete into software that can do things in the world.

Multi-Agent Systems and MCP 

The frontier is moving beyond single agents toward multi-agent systems — networks of specialized AI agents that collaborate, delegate, and verify each other’s work. An orchestrator agent decomposes complex tasks, dispatches to specialist agents (a researcher, a writer, a coder, a critic), and synthesizes outputs. This architecture mirrors how high-performing human teams operate.  Anthropic’s Model Context Protocol (MCP), created in November 2024 and donated to the Linux Foundation in December 2025, became the industry standard for connecting agents to external tools and data — with over 10,000 MCP servers deployed. OpenAI’s Agents SDK (early 2025) formalized multi-agent primitives: agents with instructions and tools, handoffs for control transfer, and guardrails for validation. Every major AI lab now has its own agent framework. 

Why Agents Make Evaluation Exponentially Harder 

Evaluating a simple chatbot is already challenging. Evaluating an agentic system is orders of magnitude harder. Agents make sequences of decisions, each of which can compound errors. A single hallucination in step 3 of a 10-step workflow can corrupt all subsequent outputs. The final result may look reasonable even when the path to get there was deeply flawed.  Traditional evaluation metrics — accuracy, BLEU score, human preference — were designed for single-turn outputs. Agentic evaluation requires new frameworks: trajectory evaluation, tool-use accuracy, goal completion rate, and safety monitoring across every action taken. 

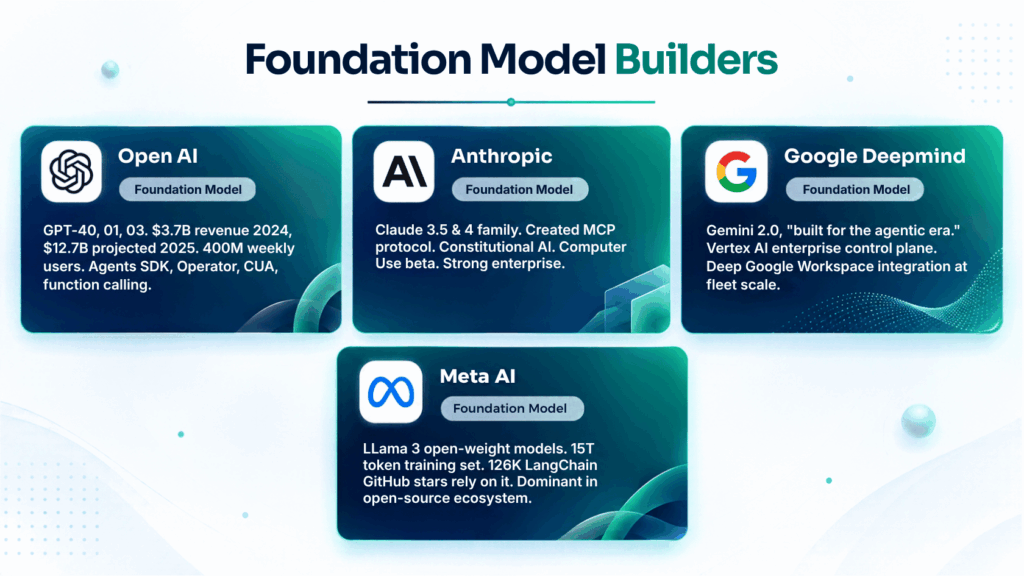
 The First Movers 

Foundational model builders

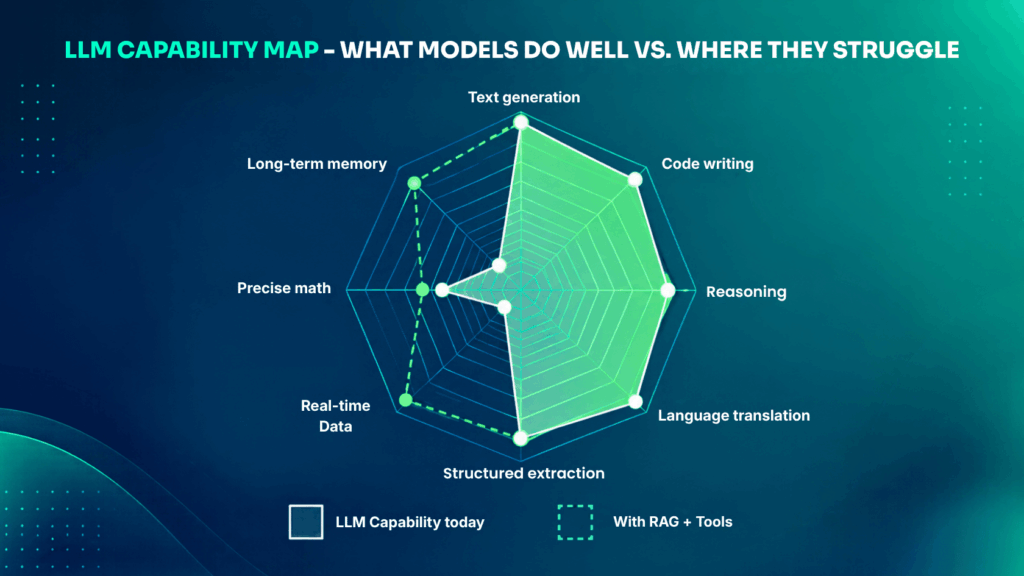
 What Can an LLM Actually Do? 

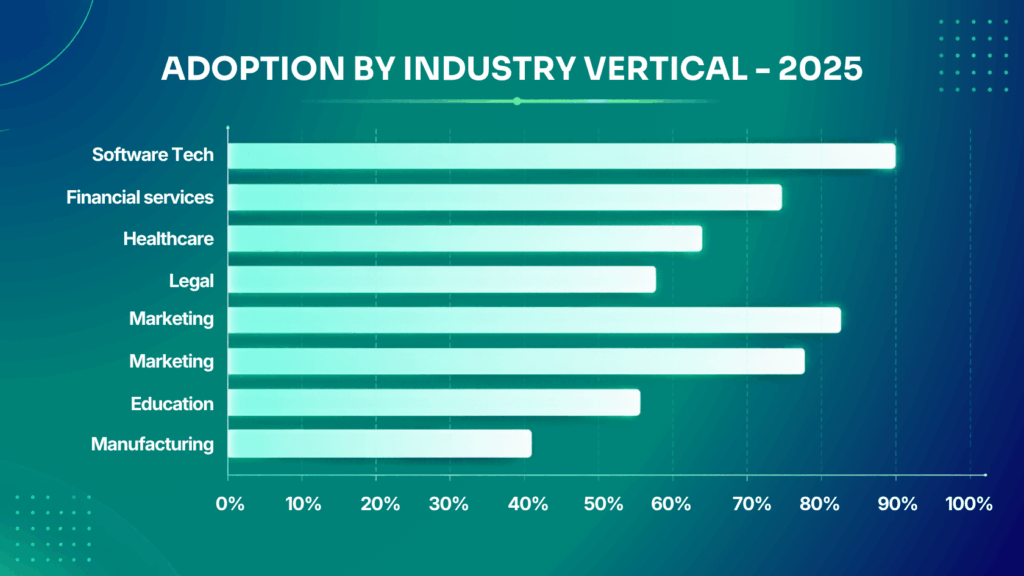
The answer in 2025 is: almost anything that involves language, reasoning, or code. But “almost anything” is not the same as “everything reliably.” Understanding where LLMs excel and where they fail is the foundation of good system design.  LLM Capability Map Adoption by industry vertical 

Why LLM Eval Matters Now 

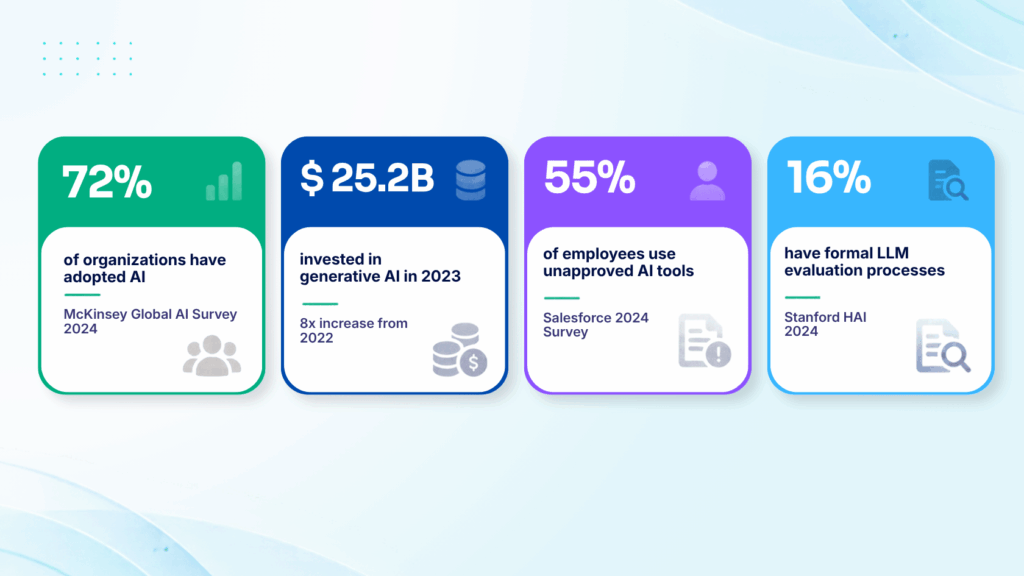
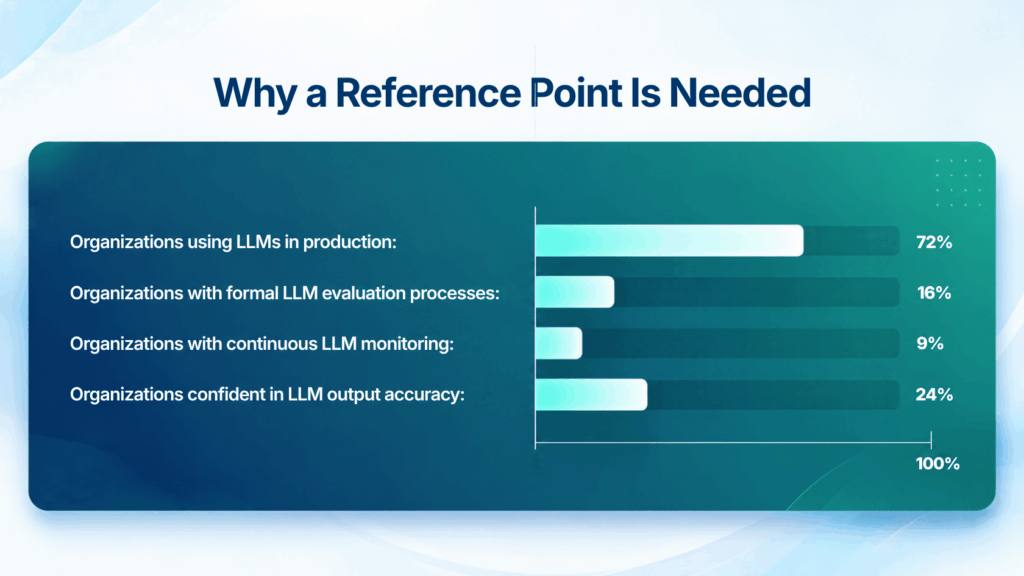
With custom LLM tools, copilots, and agents are becoming part of real workflows every day. But as usage grows, so do the risks — inconsistent outputs, hallucinations, broken prompts, and no clear way to measure quality. That is why the need for a reference point has become urgent.  The problem we see is simple: LLMs are powerful, but they are not naturally predictable.   The same prompt can produce different answers, prompt changes can shift behavior, and a model that looks strong in a demo can fail in real use. Without a standard way to evaluate quality, teams are left guessing whether they are actually improving or just seeing different output.  That gap becomes even more serious as teams move from experimentation to production. Once an AI system is used for support, search, drafting, decision-making, or agent workflows, a weak output is no longer a harmless mistake. It can affect customers, slow teams down, and damage trust in the product.  Market Statistics of LLM

 The Growth Problem 

The rise of custom LLM tools is creating a new problem: usage is outpacing measurement. Enterprises are investing in AI systems, model experimentation, and custom workflows, but the discipline around evaluation is still catching up. Because teams are realizing they need a better way to measure outcomes.  That matters because custom AI is not just one model call anymore. It often includes prompts, retrieval, tools, routing logic, agent loops, and guardrails. Each layer adds complexity, and each layer can fail differently. If the system is changing every week, a one-time test is not enough. Teams need something repeatable that can tell them whether quality is improving or drifting.  This is where most teams feel the pain first: 
  • Output quality varies from one run to the next. 
  • Prompts that work today can fail after a small edit. 
  • A better-looking answer is not always a better answer. 
  • Multiple models can behave differently on the same task. 
  • Agents can take the wrong step even when the final answer looks fine. 
Without a shared measurement layer, those issues become hard to spot early. The result is slower releases, more manual review, more rework, and less confidence in production AI. 
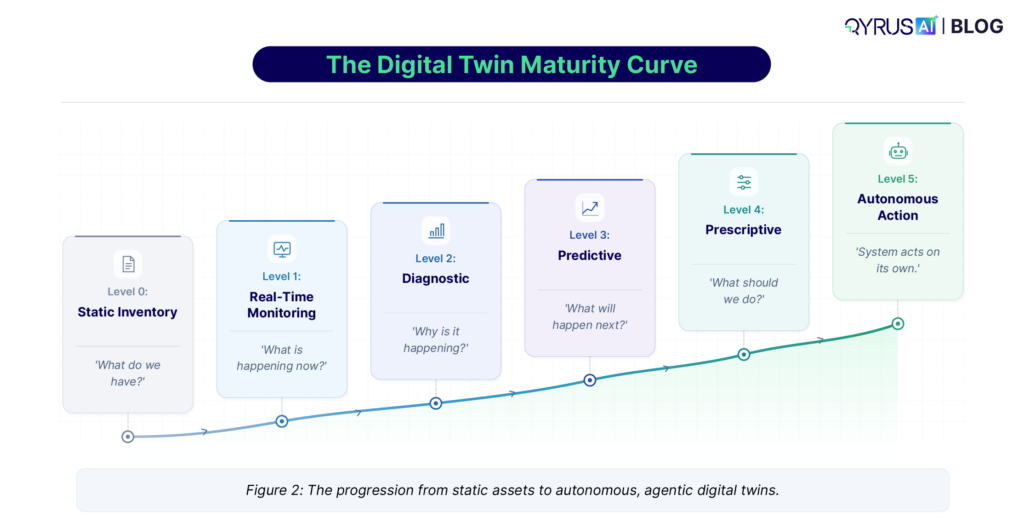
What Teams Are Struggling With 

Teams building custom LLM tools are not just asking, “Did it work?” They are asking deeper questions: 
  • Is the output correct? 
  • Is it consistent? 
  • Does it stay safe on edge cases? 
  • Does it behave the same after a prompt or model change? 
  • Can we trust it at scale? 
Those questions are hard to answer without a reference point. That is why so many AI teams end up using subjective review, ad hoc prompt checks, or manual spot testing. Those methods can help early on, but they do not scale well once the product grows. What starts as a quick check becomes a weak process.  How organizations are customizing LLMs The biggest problem is that AI output is not binary. Traditional software testing often checks whether something passes or fails. LLM systems are fuzzier. They can be partially right, confidently wrong, overly verbose, too vague, or inconsistent across runs. That makes evaluation less about one perfect answer and more about a structured way to compare quality over time.  That is also why model comparison alone is not enough. A team may switch models and see better output in one area, but worse behavior somewhere else. Without evaluation, that trade-off is invisible. With evaluation, it becomes measurable. 

Real-World Failures: What Happens Without Evaluation 

Real world failures examples

Expert Perspective 

“In aviation, we don’t let a plane fly without rigorous testing. In pharmaceuticals, no drug reaches patients without clinical trials. Yet we’re deploying AI systems that influence millions of decisions daily with virtually no standardized evaluation.”  — Dr. Percy Liang, Director, Stanford Center for Research on Foundation Models (CRFM)  

Why a Reference Point Is Needed 

Why a reference point is needed  Sources: Stanford HAI 2024, MIT Sloan Management Review, Gartner  The industry needs a standard way to answer one question: Is this AI system actually getting better? That is what evaluation metrics provide. They create a baseline that teams can return to whenever they change a prompt, swap a model, add retrieval, or release a new version.  A good evaluation metric acts like a compass. It does not just tell you whether a single answer looks decent. It tells you whether the system is moving in the right direction. That matters for quality, but it also matters for speed. When teams know how to measure improvement, they can move faster with less fear.  Evaluation also helps teams compare across the things that matter most: 
  • Accuracy. 
  • Consistency. 
  • Safety. 
  • Retrieval quality. 
  • Tool use. 
  • Helpfulness. 
  • Resistance to hallucination. 
Once those are measured consistently, AI stops feeling like a black box and starts behaving more like a product discipline. That is the shift the market is moving toward now.  This is the moment where evaluation becomes a competitive advantage. Teams that can test clearly will ship more confidently. Teams that can compare reliably will choose better models and prompts. Teams that can catch regressions early will avoid expensive surprises later.  As AI moves into real workflows, evaluation will become more essential. It is no longer enough for an AI system to sound intelligent. It has to be measurable, repeatable, and dependable in the situations that matter most.  That is why the next step is not more hype. It is better evaluation. And that is exactly where a solution becomes valuable.  ❌ Without Evaluation 
  • Unknown hallucination rates 
  • Undetected bias and discrimination 
  • Security vulnerabilities 
  • Regulatory non-compliance 
  • Reactive incident response 
  • Brand and trust damage 
✅ With Systematic Evaluation 
  • Quantified accuracy and reliability 
  • Proactive bias mitigation 
  • Security assurance 
  • Regulatory compliance 
  • Preventive quality control 
  • Stakeholder confidence 
Daily decisions influenced by LLMs Source: Estimated from Statista, SimilarWeb, GitHub, Google data (2025)  If LLMs handle 3 billion decisions per day with just a 1% error rate, that’s 30 million failures daily. Over a year: 10.9 billion errors. Without evaluation, you don’t even know which 1%. 

LLM Evaluation — How It Works & The QyrusAI Method 

LLM evaluation is the practice of systematically measuring how well an LLM-powered system performs its intended function. As AI moves into production, evaluation is not optional quality assurance — it is the foundational engineering infrastructure that separates teams that improve their models from teams that just guess. 

What an LLM evaluator actually does 

An LLM evaluator takes a test case — a prompt, the LLM’s response, and optional reference material — and scores it across one or more dimensions: accuracy, relevance, faithfulness, safety, coherence, goal completion. It can be a deterministic code check, an LLM-as-judge, a human reviewer, or a hybrid. The output is a score and a reason — structured signal that tells you exactly what to fix.  QyrusAI connects to your live LLM API endpoints, fires your test cases, scores each output using your chosen evaluator model, and returns pass/fail results with detailed per-dimension scoring. You pay credits per test execution. No infrastructure to stand up. No dedicated ML platform team required.  QyrusAI Evaluation Pipeline

LLM Evaluation Best Practices — 8-Point Checklist 

These are the practices that separate teams running reliable AI in production from teams constantly firefighting model regressions. Apply them in order — each builds on the last. 
  1. Define evaluation criteria before you write a single prompt 
    • Know what “good” looks like before you build. What accuracy threshold is acceptable? What tone must be maintained? What topics must be avoided? Teams that define criteria after the fact spend weeks retrofitting. Teams that define criteria first ship 3x faster. 
  2. Test hallucination rate as a first-class metric 
    • Hallucination rate should be tracked on every deployment like latency or uptime. Build a test suite of prompts specifically designed to probe the model’s weak spots — topics where training data is sparse, numerical claims, citations. Measure the rate. Set a threshold. Alert when it crosses it. 
  3. Use multiple evaluator types — never rely on one 
    • Code-based checks for structured outputs. LLM-as-judge for open-ended quality. Human review for high-stakes edge cases. Each catches different failure modes. A pipeline with only one evaluator type will have systematic blind spots.  
  4. Run regression tests on every model update 
    • Model providers push silent updates. A prompt that worked perfectly on GPT-4-turbo-2024-04-09 may behave differently on the next version. Every deployment update — model version, system prompt, context window change — must run your full benchmark suite before going live. 
  5. Evaluate RAG retrieval and generation separately 
    • If your RAG pipeline is underperforming, you need to know whether the problem is in retrieval (wrong documents fetched) or generation (model fails to use good documents). Treating them as a single system makes debugging nearly impossible. Evaluate each component with its own metrics. 
  6. For agents: evaluate trajectories, not just final outputs 
    • An agent that reaches the correct answer via a flawed path is not a passing agent. It means your system got lucky. Evaluate every tool call, every intermediate decision, every handoff. Build automated checks for: correct tool selected, correct parameters passed, appropriate fallback triggered on failure. 
  7. Monitor production continuously — not just pre-deployment 
    • Pre-deployment testing catches regressions from changes you made. Production monitoring catches degradation from changes the world made — new query patterns, seasonal topics, data drift. A model that passed all pre-deployment tests can still degrade silently in production over weeks. 
  8. Feed evaluation results back into your improvement loop 
    • Every failed eval is a training signal. Every user complaint that triggers a human review queue is data. The teams compounding improvements fastest are those who convert evaluation results directly into prompt improvements, fine-tuning datasets, or retrieval configuration changes — within days, not quarters. 
 

Frequently Asked Questions 

The questions that come up most when teams are starting to evaluate LLMs — answered directly.  What is an LLM?  A large language model (LLM) is an AI system trained on massive text datasets to understand and generate human language. It predicts the next token in a sequence using billions of learned parameters, producing coherent text, code, and reasoning at scale. Examples include GPT-4, Claude, Gemini, and Llama.  What is an LLM evaluation tool?  An LLM evaluation tool measures the quality, accuracy, safety, and relevance of LLM outputs systematically. It automates scoring across dimensions like hallucination rate, faithfulness, coherence, and goal completion — giving teams a repeatable, scalable way to know if their AI is actually working. QyrusAI is an example: you connect your LLM API, define criteria, choose an evaluator model, execute, and get scored results.  What is the difference between an LLM and an AI agent?  An LLM is a text model that responds to prompts reactively. An AI agent wraps an LLM with planning, persistent memory, dynamic tool access, and a feedback loop — allowing it to autonomously pursue multi-step goals without human input at each step. Every AI agent uses an LLM; not every LLM is an agent.  What is LLM hallucination and why does it happen?  LLM hallucination is when a model generates confident, fluent text that is factually incorrect or fabricated. It happens because LLMs generate text by predicting the most statistically likely continuation — they have no internal truth-checking mechanism. When training data is sparse on a topic, the model fills the gap with plausible-sounding content. Evaluation tools measure and track hallucination rates so teams can catch and fix it before it reaches users.  What is RAG and how does RAG evaluation work?  RAG (Retrieval-Augmented Generation) grounds LLM responses in retrieved source documents. The pipeline retrieves relevant chunks from a knowledge base and passes them as context to the model. RAG evaluation measures two things: retrieval quality (did we fetch the right documents?) and generation quality (did the model accurately use what it received?). Key metrics include faithfulness, context precision, context recall, and answer relevance.  How does QyrusAI work?  QyrusAI connects to your live LLM API endpoints end-to-end, runs your defined test cases against the live output, scores each response using your chosen evaluator model (GPT-4o, Claude Sonnet, Gemini, etc) and returns detailed pass/fail results with per-dimension scoring. You can define the evaluation criteria — or use our built-in rating system. Credits are consumed per test executed. No infrastructure setup required.  What are LLM testing best practices?  The eight most important practices: define evaluation criteria before prompting, track hallucination rate as a first-class metric, use multiple evaluator types (code, LLM-as-judge, human), run regression tests on every model update, evaluate RAG retrieval and generation separately, evaluate agent trajectories not just final outputs, monitor production continuously, and feed evaluation results back into your improvement loop.    Ready to evaluate your LLMs with confidence?  infra required. Credits-based. Any model.  Sign up today 
Featured image

For years, IT operations has been built around a relatively simple premise: if systems are functioning as expected, the business will function as expected. That assumption shaped how teams monitored environments, prioritized incidents, and measured operational success. System uptime, response times, and infrastructure health became proxies for business performance. In simpler, more linear environments, that model largely held true. 

The enterprise environment has changed. Modern businesses depend on interconnected applications, APIs, data pipelines, cloud services, and infrastructure layers that continuously interact. A single customer action such as placing an order, completing a transaction, or accessing a service may traverse multiple systems, each with its own dependencies and performance characteristics. The relationship between system health and business outcome is no longer direct. It is mediated by complexity. 

When Complexity Breaks the Model 

While system component reliability has generally improved across isolated hardware layers, rising enterprise dependency across multi-cloud and API ecosystems means cost-per-incident is steadily increasing even as event frequency levels off. Today, 1 in 5 organizations (20%) report that their most recent major IT outage cost over $1 million. 

The Limits of System-Level Visibility 

Teams may have comprehensive visibility into individual components such as servers, services, and applications, but that visibility does not automatically explain how those components collectively support business processes. Systems can appear healthy in isolation while the business experiences degradation in aggregate. Transactions slow down, customer journeys break, and workflows stall because something within the dependency chain is no longer functioning optimally. 

Highlighting this structural blind spot, 47% of outages are reported by customers before internal monitoring catches them—meaning nearly half of all major system disruptions are first flagged by end-users rather than internal technical alerts. Furthermore, 44% of incidents are caused by “detectable” failures, representing issues that technical telemetry actively tracked, but teams failed to interpret or prioritize correctly in time. 

The Gap Between Signals and Meaning 

The challenge is not necessarily a lack of data or visibility. Most organizations already have dashboards, alerts, monitoring, and observability tools. The challenge is context. These signals describe what is happening at a system level but often do not explain what it means at a business level. Teams are therefore forced to correlate signals manually, trace dependencies, and infer impact under time pressure and with incomplete information. 

The Cost of Operating Without Context 

The gap between system visibility and business understanding has tangible and severe financial consequences. The median cost of enterprise IT downtime has jumped to approximately $15,000 per minute ($900,000 per hour), and 91% of enterprises report that a single hour of IT downtime costs them more than $300,000.  

Beyond immediate direct losses, organizations face 3x to 5x hidden costs—including lost productivity, emergency recovery expenses, and brand equity damage. In fact, 81% of technology leaders cite customer loss and churn as the most damaging direct consequence of downtime.  

Incident response can slow down because teams lack clarity about impact. Prioritization can become inconsistent because technical severity does not always correspond to business importance. Communication between IT and business stakeholders can also become fragmented because each group is working from a different view of the environment. Over time, this misalignment creates operational inefficiency and strategic risk. 

A Shift in Perspective: Toward BizOps 

Business Operations Intelligence, often discussed in the context of BizOps, brings business goals and IT operations into a shared operating context. The goal is not to discard monitoring or observability. It is to connect technical signals to the services, workflows, KPIs, and business outcomes they support. The unit of analysis moves from the individual component toward the service, workflow, transaction, and outcome. 

This broader approach is also reflected in the evolution of business observability. Rather than looking only at technical telemetry, business observability connects operational data with business metrics and context so teams can understand how technology affects business performance. 

From Components to Relationships 

This requires relational visibility rather than isolated visibility. Teams need to understand how systems are connected, how dependencies are structured, and how changes or failures propagate across the environment. More importantly, those relationships need to be mapped to business services so that the impact of an issue can be understood in terms that matter beyond IT. An alert becomes more useful when it can indicate which service, workflow, or customer journey may be affected. 

Why Static Approaches Fall Short 

Traditional approaches such as CMDBs, manual service mapping, and periodic documentation exercises can struggle to keep pace with modern environments. Systems evolve, dependencies shift, and new services are introduced continuously. A static representation can therefore become outdated between documentation cycles. For organizations operating across hybrid, cloud, and legacy environments, maintaining an accurate picture of the estate requires continuous discovery and relationship mapping. 

The Need for Continuous Intelligence 

What is required is a continuously evolving model of the enterprise that reflects the current state of systems, their relationships, and their connection to business outcomes. This changes how teams perceive their environment, prioritize work, and make decisions under pressure. The emphasis shifts from collecting more signals to creating usable context from the signals already available. 

Where QyrusAI Fits In 

This is where QyrusAI brings a business-aware operations approach into the broader enterprise application lifecycle. As an agentic platform, QyrusAI is designed to help enterprises modernize, assure, and operate their enterprise applications through a connected lifecycle.   

QyrusAI continuously discovers enterprise assets, maps dependencies, and connects technical relationships to business services. At the core of this approach is QyrusAI’s Live Enterprise Knowledge Graph, which provides a continuously observed model of applications, dependencies, and business services. This creates a shared context for understanding operational issues rather than relying solely on isolated alerts or static documentation. 

This connected lifecycle is delivered across three key pillars: 

  • Modernize: Helps enterprises discover applications and dependencies, assess technical debt, rationalize portfolios, and plan and execute modernization with greater architectural context.  
  • Assure: Focuses on testing and validation across web, mobile, API, SAP, data, and test orchestration, helping teams validate application changes before they reach production.  
  • Operate: Brings operational intelligence across AIOps, observability, BizOps, FinOps, automation, and incident response, helping teams connect technical health with business impact. Its Operate capabilities extend this context directly into operations, including BizOps, where technical signals can be connected to the business services and transactions they affect.  

 Together, these pillars create a connected view across the application lifecycle, with a shared Knowledge Graph and operational context that can flow seamlessly between modernization, quality, and operations. 

From Reaction to Clarity 

When business context is connected to technical signals, incident response can become more precise because impact is easier to identify. Prioritization can be grounded in business relevance rather than technical severity alone. Decision-making can also become faster because teams can work from a shared, contextual understanding of the environment instead of piecing together fragmented information. 

This approach aligns with the broader direction of enterprise observability. IBM notes that business observability connects technical signals with business metrics and context, helping teams understand how IT system health affects core business outcomes. The underlying principle is straightforward: visibility becomes more valuable when teams can connect what changed in technology to what matters to the business. 

The Real Shift 

The deeper shift is in how IT operations is measured. It is no longer sufficient to know that systems are running. Teams also need to understand whether the services and business processes those systems support are running as intended. That requires visibility into relationships, dependencies, service health, and business impact.  

Frequently Asked Questions (FAQs) 

  1. What is the main difference between traditional IT monitoring and Business Operations Intelligence (BizOps)?

Traditional IT monitoring focuses on isolated component metrics such as CPU loads, server uptime, and response latency. BizOps bridges the gap between IT and business goals by connecting those technical signals directly to the workflows, transactions, services, and business outcomes they support.  

  1. How does QyrusAI eliminate manual dependency mapping?

QyrusAI utilizes its Live Enterprise Knowledge Graph to continuously discover enterprise assets, map real-time technical dependencies, and link them automatically to business services without relying on outdated static documentation or manual CMDB spreadsheets.  

  1. Why do traditional CMDBs fail in modern hybrid environments?

Modern multi-cloud and microservice architectures evolve rapidly through continuous deployment pipelines and automated scaling. Traditional CMDBs and periodic documentation exercises quickly become obsolete, creating critical blind spots during active outages.  

  1. How does QyrusAI help reduce alert fatigue for SRE and IT Operations teams?

By mapping technical anomalies within the Live Enterprise Knowledge Graph and correlating raw telemetry against actual business workflows, QyrusAI groups related alerts and prioritizes them based on true commercial impact rather than isolated technical thresholds. 

Closing Thought 

The question is no longer whether your systems are healthy. 

It is whether you understand what that health actually means for your business. 

Ready to move from system-level visibility to business-level understanding? Explore QyrusAI BizOps to see how technical signals, dependencies, services, and business impact can be connected in a single operational context. 

Talk to an Expert 

Featured Image

Picture an enterprise with hundreds of applications. A few run business-critical services. Several do almost the same job. Some barely get used. Application rationalization is the discipline of sorting that portfolio: reviewing every application and deciding whether to modernize it, consolidate it, retire it, or leave it alone.  

The decision matters because modernization budgets are finite. When every outdated application becomes a modernization project, teams spend months upgrading systems that should have been merged or switched off. This guide shows a practical way to make the call, based on business role, usage and cost rather than technical age alone.  

Why an old application isn’t automatically a modernization candidate  

Ask most teams where to start, and they point at the oldest systems. The instinct makes sense. Older applications often run on aging frameworks, with limited vendor support and more security exposure.  

But age measures technical condition. It says little about how much the business relies on the application. A decade-old billing system may sit behind every invoice you send. A recently bought workflow tool may have a dozen users and no clear owner.  

Gartner’s TIME model captures this by plotting each application on two axes, business value and technical fit, then sorting it into Tolerate, Invest, Migrate, or Eliminate, as LeanIX explains. Age feeds into technical fit. But it is only one input beside maintainability, compatibility and vendor support. Enterprise architects use the result to see which applications deserve money. The same logic gives you four cases to remember:  

  • Old and business critical: modernize, carefully. The application has earned the investment.  
  • Old and low value: retire it. Modernizing it would only preserve something the business doesn’t need.  
  • New and business critical: keep investing and keep it healthy.  
  • New and low value: question it. It often overlaps with something you already own.  

Treating all four the same is how modernization budgets get spread thin.  

The four decisions a portfolio review produces  

Frameworks use different labels. TIME says Tolerate, Invest, Migrate and Eliminate. Cloud-focused models talk about rehosting, replatforming, retiring and retaining. Underneath the vocabulary, a portfolio review comes down to four practical outcomes.  

Decision  

When it fits  

Roughly maps to  

Modernize  

The business needs the application, but its technology holds it back  

Migrate  

Consolidate  

Several applications do the same job, so one survives and the others’ users and data move across  

Migrate, then Eliminate  

Retire  

The application has low value, low use or a redundant role; switch it off and keep any data you must retain  

Eliminate  

Leave alone  

It works, costs little and nobody is asking for more  

Tolerate or Invest  


Look at what that table implies. Three of the four outcomes reduce the amount of modernization you need to fund. Consolidation merges projects. Retirement removes them. Leaving an application alone avoids them. Cost, usage and business role drive each choice, not the year the application was built. That is why the review should come before the modernization budget, not after it.  

A worked example: three departments, one job  

Here is an illustrative scenario, not a customer result. Sales, customer support and field services each run their own application to track customer requests. Each was a sensible purchase at the time. Now each carries its own licenses, infrastructure, upgrades and support contract.  

Without a portfolio view, a modernization program sees three separate applications and funds three projects. Each team defends its own tool, and the work starts from the assumption that all three will survive.  

A rationalization review asks different questions. How many people use each application every week? What does each cost to run? Which business process depends on it? Suppose the answers show that one application covers nearly everything the other two do, while the other two serve small teams for features the first already offers.  

Now the team can consolidate: keep one application, migrate the users and data from the others, and retire two. Three modernization projects become one, or none if the survivor is already healthy. Overlap isn’t always waste, though. If one department needs a regulated workflow the others lack, the duplication may be justified, and the review should say so.  

The same thinking applies to supporting systems. Test environments multiply in the same way, which is why we’ve written about how infrastructure consolidation lowers testing costs.  

Five steps that start with evidence  

A review is only as good as the data behind it. These five steps put evidence ahead of opinion.  

  1. Build the inventory from the environment, not from surveys 

Most portfolios are bigger than the people running them believe. Zylo found that organizations underestimate their application count by about 1.7 times and their software spend by about 3 times, according to its analysis of SaaS sprawl. Ownership is scattered too. Business units control 81% of SaaS spend, while IT directly manages 15%, per Zylo’s 2026 SaaS Management Index. And Torii puts the average large enterprise at 2,191 business applications.  

A spreadsheet that people fill in by hand will miss much of that. Automated discovery gives you one application inventory that works as a single source of truth for every later decision.  

  1. Score usage, cost and business role 

For each application, record how often people actually use it, what it costs to run (licenses, infrastructure and support) and which business capabilities depend on it. Owners understandably defend their tools, so measured usage settles debates that opinion can’t.  

  1. Map dependencies before you decide 

A low-usage application can still feed a critical process. Map what each application connects to, including data feeds, integrations and shared infrastructure, before you assign an outcome. Finding a dependency before the decision is cheap. Finding it after the shutdown is not.  

  1. Decide per application 

Assign one of the four outcomes to each application in scope. Start with one business capability or department rather than the whole portfolio, so every decision stays reviewable. If a decision involves moving an ERP, plan the testing early; our guide to performance testing for a stable SAP S/4HANA go-live shows what to check. Whichever application survives a merger will also absorb new users and data, so it needs solid regression coverage. Here is how automated regression testing improves release quality.  

  1. Sequence by risk and payoff 

Retire clear duplicates first. They free up budget quickly and carry the least risk. Consolidations come next. Then modernize the critical applications, funded in part by what the earlier steps released. Revisit the plan each quarter as usage data changes.  

Retiring an application without breaking what depends on it  

Retirement looks like the easy win. It isn’t always. Legacy applications often feed reports, manual exports and indirect integrations. Those links can stay hidden until the system is gone, according to CIGen’s decommissioning guide.  

The opposite failure is the zombie application. Teams mark it retired and restrict access, but the database stays online and old integrations keep running. The savings never fully arrive, and nobody is sure the system can be switched off, a pattern that Archon describes in its decommissioning framework.  

A safer retirement follows four checks:  

  • Discover: confirm what the application does today, who uses it and what data it holds.  
  • Map dependencies: list every upstream and downstream connection, including undocumented ones.  
  • Analyze impact: model what changes for connected systems and business processes before anything is switched off.  
  • Preserve knowledge: archive required data and record the business logic, so the organization keeps what the application knew after it is gone.

That last check matters more than most plans admit. When the people who understand an old system move on, the application itself is often the only record of how a process really works. Capture that before shutdown.  

Why a one-time cleanup doesn’t last  

A rationalized portfolio starts drifting the day you finish. Business units buy most SaaS themselves, so new tools rarely pass through central review. AI is speeding that up. BetterCloud reports that 22% of SaaS applications are now AI-powered, up from 7% a year earlier.  

New applications arrive faster than an annual review can catch them. Rationalization works best as a continuous practice: assess usage, overlap and cost as applications enter the portfolio, not once a year. Continuous assessment also keeps the inventory current, so the next decision starts from evidence instead of another survey.  

How QyrusAI supports application rationalization  

QyrusAI is a single AI platform that unites application modernization, software testing and autonomous IT operations. It organizes that work into three connected workspaces. Qyrus Modernize discovers, maps and modernizes the enterprise estate. Qyrus Assure validates every change through AI-driven test automation. Qyrus Operate detects and resolves issues in production. All three share one Knowledge Graph of the estate, so what one workspace learns informs the other two.  

Application rationalization sits inside Modernize, alongside application discovery, dependency mapping, legacy modernization, cloud migration intelligence and technical debt analysis. QyrusAI Application Rationalization looks across the whole portfolio and weighs how each application is used, what it costs to operate and what role it plays in the business. That gives teams the context to choose between modernizing, consolidating and retiring, instead of judging by technical age alone.  

Four capabilities support the decision:  

  • Auto-discovery and dependency mapping build the inventory and the connection map from the live environment, which reduces reliance on manual surveys and on a few subject-matter experts.  
  • Digital Twin impact analysis predicts the ripple effects of decommissioning an application before anyone switches it off.  
  • Knowledge retention keeps business logic and data context available in the Knowledge Graph after a system retires.  
  • Continuous assessment helps stop redundancy from building up again after the first review.  

QyrusAI’s targeted outcomes include decommissioning 20–30% of redundant legacy applications and achieving 15–20% infrastructure cost savings through right-sizing environments. These are targets, not guarantees, and results depend on the starting portfolio.  

Frequently asked questions  

What is application rationalization?  

It is a structured review of an organization’s application portfolio that decides what to modernize, consolidate, retire or keep as it is. The decision rests on usage, cost and business role.  

How is it different from application modernization?  

Rationalization decides which applications deserve which treatment. Modernization is the technical work of upgrading or re-platforming the ones you chose to keep and improve. Running the review first keeps you from modernizing systems you should have retired.  

When should a company start?  

Common triggers include mergers and acquisitions, a planned cloud migration, budget pressure, the retirement of a legacy system and a sudden rise in departmental or AI tools. Any of these tends to expose overlap.  

How many applications should a review cover at once?  

Start with one business capability or department. A narrower scope keeps the data reviewable and the decisions defensible, and you can extend the same method to the next area.  

What are the main risks of retiring an application?  

The biggest ones are hidden dependencies, data-retention obligations and user adoption. Mapping dependencies, archiving required data and planning for the people who use the application reduce all three.  

Make the right change in the right place  

The goal of modernization isn’t to make everything newer. It is to make the right change, in the right place, for the right reasons. Application rationalization gives you the evidence to do that: which applications to modernize, which to merge, which to retire and which to leave alone.  

QyrusAI Application Rationalization brings usage, cost and business context into that decision, backed by discovery and dependency mapping across the estate. Request a demo to see how QyrusAI can help you decide what to modernize and what to retire.  

Beyond Dashboards Featured image


In early 2025 the European Central Bank experienced a 7-hour core banking outage that affected 11 million customers.  

Post-incident analysis showed the root cause in less than twenty minutes. Every monitoring dashboard had shown green until the moment it did not. The change that caused the failure had passed through staging without incident. The problem only appeared under the specific load profile that production carried on a Tuesday morning, on hardware that staging did not replicate, interacting with a third-party dependency that nobody had  modelled. 

Of course the team had more monitoring than ever. But what they lacked was a proper system that could have told them what that change would actually do before it moved to production. 

This is the problem that a living digital twin can solve.  

Not more dashboards. Not a faster alert. But a simple system that can hold a working model of your environment, update it continuously in real-time, and lets you ask the question that monitoring cannot answer: if we deploy this now, what will break? 

This QyrusAI guide covers this briefly: Why regular monitoring hits a structural ceiling, what the maturity curve from static model to living twin looks like, what a genuine intelligent twin does for IT operations, why most enterprise twin initiatives stall before they deliver value, and how to start in a way that produces results in weeks rather than years. 

Barclays too faced a similar IT and mainframe failure that triggered a severe core banking system outage. The incident forced millions of customers out of their accounts, locked over 50% of digital and online transactions. 

The Limits of Your Monitoring Strategies  

The ‘single pane of glass’ term has been the goal of IT operations tooling for the better part of a decade. Unify your metrics, logs, and traces, surface everything in one place. Build dashboards that show the state of every system at a glance. The problem is not that this goal is wrong but that it solves the wrong problem. 

Dashboards show state but they do not predict consequences. 

A monitoring dashboard is a rear-view mirror. It tells you what is happening right now, and it tells you what happened in the past. It does not tell you what will happen if your deployment goes out at 2pm, or what the blast radius of a failed database migration will be across downstream services that nobody mapped, or whether the ‘routine’ certificate rotation you scheduled for Friday will cascade into an authentication failure that affects your payment processing. 

This isn’t a tooling gap that more dashboards close but clearly a category gap. Monitoring observes state. Prediction requires a model — something that understands how the components of your environment relate to each other well enough to simulate what happens when one of them changes. 

What is the difference between a digital twin and monitoring? 

This is the question IT teams ask most often when evaluating twin technology, and the distinction is specific. 

Monitoring collects telemetry — metrics, logs, traces, events and displays it. It tells you that CPU utilization on node-14 is at 94% right now. It can alert you when that threshold is crossed. It cannot tell you why the utilization is high, what will fail if it stays there, or whether the memory pressure on the adjacent node is related. 

A digital twin holds a live model of the relationships between your systems. It knows that node-14 runs the order processing service, which depends on the inventory API, which is already running slow, and which serves the checkout flow that accounts for 40% of your revenue. When CPU spikes on node-14, the twin does not just alert but it goes a step ahead and it maps the impact: these downstream services are at risk, this revenue flow is exposed and this is the change that was deployed 22 minutes ago that is most likely the cause. 

Traditional Monitoring 1

Monitoring answers: what is the current state of each system? 

A digital twin answers: given the current state of each system, what is the likely state of the whole environment in the next 30 minutes, and what happens if we make change X right now? 

One is observation. The other is a working model with predictive capability. Both are necessary. Neither substitutes for the other. 

Why teams still get blindsighted 

The most common form of production incident in modern enterprise IT is not random failure — it is change-induced failure. A deployment, a configuration update, a certificate rotation, a dependency version bump. Something that usually looks correct in staging, passed all tests, and still caused a production outage. 

The reason staging does not catch these is structural:, staging environments are approximations. They do not carry the exact load profile of production. They do not have the same mix of background jobs, caching states, and in-flight transactions. They do not replicate the specific combination of hardware, OS, and dependency versions that exists in production for every service. And they do not model the relationships between services — the cascade paths that make one service’s failure another service’s outage. 

A digital twin built from production telemetry addresses this directly. It does not replicate the environment but it models it. When you simulate a change against the twin, you are simulating it against a model that reflects how production actually behaves, including the load patterns, the dependency relationships, and the historical failure modes of the specific components involved.

80% 

Of production incidents caused by changes to existing systems, not new failures 

22 min 

Average time to detect that a change has caused a production issue without twin-based impact prediction 

67% 

Of enterprise organizations planning to invest in digital twin technology in 2026 (Core Systems survey) 

The Digital Twin Maturity Curve: From Static Asset Model to Living System 

Most discussions of digital twins treat it as a binary — you either have one or you do not. The reality is a maturity curve with five distinct levels, each delivering different value and requiring different capability. Understanding where your organization sits on this curve is the most useful starting point for any twin initiative. 

Level 0 — 1: Asset inventory and static models 

Most organizations that believe they have a digital twin actually have a level 0 or level 1 system: an asset inventory with some relationship mapping. It describes what systems exist and how they are supposed to be connected, based on documentation and architectural diagrams. It does not reflect what is actually deployed, what the real dependency graph looks like at runtime, or how those dependencies behave under load. 

The value here is real but limited: a searchable CMDB with relationship data is more useful than spreadsheets. The ceiling is also real: a static model that is not fed by live telemetry drifts from reality within weeks of any significant deployment. Teams learn to distrust it, stop updating it, and eventually maintain it only for compliance purposes. 

Level 2 — 3: Telemetry-fed discovery and impact analysis 

A level 2 twin is fed by real telemetry: it discovers the actual dependency graph from network traffic, API call patterns, and service mesh data rather than from documentation. It knows what is actually calling at what frequency, with what latency profile. When something changes, it can show you what depends on it. 

Level 3 adds impact analysis: the ability to trace a failure or a change through the dependency graph and predict which following services can be affected. This is where the gap between monitoring and twin capability becomes operationally significant. A level 3 twin can answer ‘if this service goes down, what breaks?’ before the service goes down. 

Maturity Curve 1

Level 4 — 5: Predictive intelligence and autonomous action 

A level 4 twin predicts future states based on current telemetry trends. It does not wait for a threshold to be breached — it identifies that the trajectory of a metric will breach the threshold in approximately 18 minutes, and it surfaces that prediction with the context needed to act before the incident occurs.  

Level 5 is an autonomous twin that not only predicts but acts. It routes around failing components, triggers remediation workflows, and updates its own model in response to the changes it observes. This is where digital twin capability intersects with agentic AI: the twin becomes the perception layer through which an AI agent understands and acts on the environment. 

Why twins are expanding to business-process scope 

The twin’s scope is expanding for a specific reason: infrastructure failures are increasingly business failures. An SRE team that knows a service is down is useful. An IT operations team that knows a service is down, which customer journeys it affects, and what the revenue impact is per minute of downtime — and can communicate that to a business stakeholder in real time — is operationally essential. 

Business-process-level twins map IT system health to business outcome metrics. They connect the infrastructure layer — service availability, API latency, database response time — to business-layer metrics like transaction completion rate, checkout abandonment, and customer session drop-off. When an incident occurs, the twin can immediately answer the question that the business cares about: how much is this costing us, which customers are affected, and which product flows are broken? 

The Need for a Digital Twin for IT Operations

The conceptual case for digital twins is widely understood. The operational specifics are where teams lose clarity. Here is what a mature twin actually does — and what it changes about daily IT operations. 

Safe simulation: testing changes before they touch production 

Change management is the highest-risk activity in IT operations. More incidents are caused by changes than by spontaneous failures. The standard mitigation is staging environments, change windows, and rollback plans — all of which help but none of which provide advance certainty about what a change will do in production. 

A digital twin provides a third option: simulate the change against the model before applying it to the environment. Feed the twin the proposed change — a new deployment configuration, a dependency version update, a network topology modification — and let it evaluate the impact against the live model of your production environment. Which services are affected? Do any of them have dependency chains that create blast radius? Does this change touch a component that has had reliability issues in the last 72 hours? 

This does not replace staging or change controls. It adds a layer of intelligence that answers questions that staging cannot, because it operates against a model of how production actually behaves rather than an approximation. 

Chaos engineering as a twin use case, not a separate discipline 

Chaos engineering — deliberately introducing failures to test system resilience — is now a recognised discipline in enterprise IT. Gartner has listed it in its Hype Cycle for Platform Engineering and SRE for multiple years. The challenge has always been the same: chaos experiments carry inherent risk. You are intentionally breaking things, and if you do not understand the blast radius in advance, you may break more than you intended. 

A digital twin changes the risk profile of chaos engineering fundamentally. Instead of running a failure scenario in staging (where the results do not generalise to production) or carefully limiting production experiments (because you do not know the blast radius), you run the scenario in the twin first. The twin tells you which services will fail, which dependencies will cascade, and which paths will be affected — before you inject a single fault. You can then run the real experiment with confidence about what you are about to observe, and with a tighter scope because you already know where to look. 

Impact prediction for change management and deployments 

The twin’s most operationally immediate value is impact prediction during change management. When a change request is submitted, the twin evaluates it against the live model of the environment and produces an impact assessment: which services this change touches, what depends on those services, what is the predicted risk level based on the current state of those dependencies, and are there any open incidents or anomalies in the affected components that would increase risk. 

This transforms change management from a process based on checklist compliance — has the change been reviewed, has it been tested in staging, is there a rollback plan — to one based on actual environmental intelligence. The change request is evaluated against reality, not against documentation. 

Teams using twin-based change impact prediction consistently report two outcomes: fewer failed changes, because high-risk changes are identified before they go out, and faster post-incident recovery, because the twin’s dependency map accelerates root cause analysis when something does go wrong. 

Why Most Digital Twin Initiatives Stall — and Where They Actually Fail 

The failure rate of enterprise digital twin initiatives is high. A 2026 survey from StartUs Insights found the market growing rapidly but noted that ‘pilots still stall’ in the transition from experimentation to production-grade infrastructure. The failure points are consistent across organizations.

Initiatives Stall

The data boundary problem: IT/OT and dev/ops integration 

The most common failure point is the data boundary. A digital twin’s value is proportional to the completeness and accuracy of the telemetry it ingests. A twin that only knows about infrastructure metrics — CPU, memory, network — cannot predict the impact of a change on the application layer. A twin that only knows about application-layer performance cannot correlate it with the infrastructure events that caused it. 

Enterprise environments have two chronic data boundary problems. The first is the IT/OT boundary in organizations with physical infrastructure: the operational technology layer — manufacturing equipment, building systems, network hardware — typically uses different protocols, different data formats, and different ownership structures from the IT layer. Bridging this boundary requires normalisation work that most teams underestimate by a factor of three to five. 

The second is the dev/ops boundary. Development teams generate rich data about application behavior— test results, deployment records, code change history, performance benchmarks — that operations teams rarely have access to in structured form. Without this data, the twin’s model of the environment is missing the most predictive signal for change-induced incidents: what changed, when, by whom, and what the test results showed. 

Static twin decay: why your model becomes wrong faster than you update it 

The second failure mode is decay. A twin built from a point-in-time discovery exercise reflects the environment as it was on the day of discovery. In an enterprise environment with continuous deployment, infrastructure changes, and evolving dependencies, that model drifts from reality within weeks. Teams that do not invest in continuous telemetry-fed model updates find that their twin becomes increasingly unreliable — producing impact assessments based on a topology that no longer exists. 

The solution is continuous auto-discovery: the twin rebuilds its model from live telemetry  continuously, rather than from periodic manual inventory updates. This requires both the telemetry infrastructure to feed it and the ingestion architecture to normalise and process that telemetry in real time. 


The organizational boundary: who owns the twin? 

The third failure mode is organizational. A digital twin that is useful for IT operations, useful for development teams, and useful for business stakeholders requires cross-functional ownership that most organizations do not have a structure for. Infrastructure teams own the hardware layer. Platform engineering owns the application infrastructure. Development teams own the application code. Finance teams own the business metrics that the twin maps to IT events. 

Twin initiatives that are owned by one of these teams and built to serve only that team’s needs consistently produce a partial twin that cannot answer the cross-functional questions that make twins genuinely valuable. The initiatives that succeed treat the twin as shared infrastructure — like a data warehouse — and establish governance structures that reflect that. 


Failure mode 

What it looks like in practice 

What the fix requires 

Data boundary (IT/OT, dev/ops) 

Twin has infrastructure metrics but not app layer; or app performance but not infra context 

Unified telemetry ingestion across all layers; API integration with CI/CD and change management systems 

Static model decay 

Impact assessments based on topology that was last updated 6 weeks ago 

Continuous auto-discovery from live telemetry; no periodic manual update cycles 

Organizational boundary 

Twin owned by infra team; can’t answer dev or business questions 

Treat twin as shared platform infrastructure; cross-functional governance from day one 

Confidence problem 

Twin produces predictions but operators don’t trust them — ‘it said red but it was fine’ 

Calibration period with measured accuracy; feedback loop from outcomes to model tuning 


How QyrusAI’s Intelligent Twin Addresses This 

 QyrusAI is the Intelligent Twin of the operational layer at the centre of the platform. It is not a standalone visualisation tool. It is the working model of the IT environment that every other capability — AIOps, incident prediction, chaos engineering, ITSM automation operates against. 

Auto-discovery from live telemetry, not manual inventory 

QyrusAI builds and continuously updates the twin’s dependency graph from live telemetry — network traffic patterns, API call chains, service mesh data, log correlation — rather than from documentation or periodic discovery exercises. The model reflects how the environment actually behaves at this moment, not how it was documented at the last architecture review. When a new service is deployed, or an existing service changes its dependency pattern, the twin’s model updates automatically. 

This addresses the static twin decay problem directly: the model cannot drift from reality because it is rebuilt from reality continuously. 

Enterprise Knowledge Graph as the perception layer for agentic AI 

The twin’s dependency model connects to QyrusAI’s Enterprise Knowledge Graph — a structured representation of the relationships between IT systems, business processes, organizational units, and business outcome metrics. This connection is what enables the twin to answer business-layer questions from infrastructure-layer events. 

When the knowledge graph maps the checkout service to its revenue contribution, and the twin knows the checkout service depends on the payment API, and the payment API is showing anomalous latency — the system can immediately produce a business-level impact statement rather than an infrastructure alert. Not ‘payment API P99 latency is 1,400ms.’ But ‘checkout completion is likely to drop by 18% in the next 12 minutes based on current payment API degradation.’ 

This is also the architecture that enables agentic AI. The twin and knowledge graph together form the perception layer — the structured understanding of the environment — through which an AI agent can act. Without a live, accurate model of the environment, an AI agent acts on incomplete information. With the twin as its perception layer, the agent can evaluate the likely impact of its actions before taking them. 
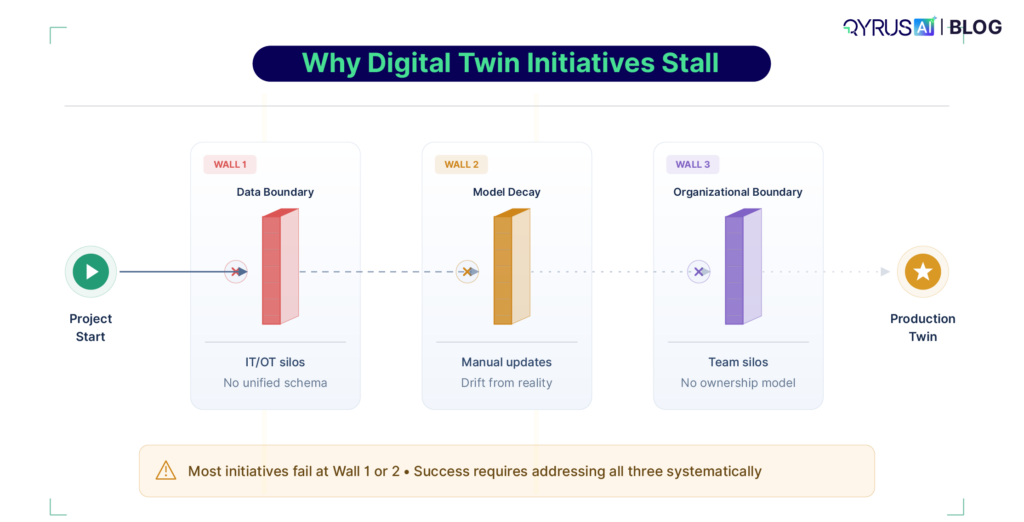
Change impact validation before deployment 

Our Auto Validate capability runs proposed changes against the live twin before deployment. A change request enters the system — a new deployment config, a dependency version update, a network change — and the twin evaluates its impact against the current model of the environment. Which services are in the blast radius? Are any of them currently degraded? Does this change touch a component with a history of instability? Is the proposed change window a high-traffic period for the affected services? 

Teams using Auto Validate report a consistent pattern: the changes that get flagged as high-risk by the twin are disproportionately the ones that would have caused incidents if they had gone out unmodified. The twin is not infallible, but its hit rate on identifying genuinely risky changes is substantially higher than human review of change requests alone, because it operates against the live environment model rather than against static documentation. 

MTTR reduction through twin-accelerated diagnostics 

When an incident does occur, the twin’s dependency map dramatically accelerates root cause analysis. Instead of an SRE manually tracing which services are affected, correlating logs from multiple sources, and building a picture of the cascade path — a process that routinely takes 20 to 45 minutes in complex environments — the twin surfaces the affected dependency chain immediately. It shows which components are failing, which upstream events preceded the failure, and which downstream services are at risk. 

The practical MTTR impact is not in detecting the incident faster — monitoring handles that. It is in the gap between detection and diagnosis, which in complex microservice environments is typically where most of the incident time is spent. The twin does not eliminate that work. It compresses it from 20–45 minutes to 3–8 minutes for the majority of incidents where the root cause is within a dependency the twin has  modeled. 

Analyst recognition 

QyrusAI has been recognized in Gartner Hype Cycles for Platform Engineering, SRE, I&O Automation, and Observability (2024–2025), specifically in the Chaos Engineering category. QyrusAI was named a Leader in the Forrester Wave for Autonomous Testing Platforms (Q4 2025) and featured as an AI-Augmented Testing vendor in Gartner’s April 2025 report on generative AI in the software delivery lifecycle. 

Where Do You Start: Twin Your Highest-Risk Systems First 

The failure mode of treating a digital twin initiative as an enterprise-wide infrastructure project is well-documented. The scope is too large, the data integration work takes too long, and the first value is too far away for the initiative to maintain organizational support. 

The approach that consistently produces results is narrower and faster: identify the two or three systems in your environment that carry the most risk — highest revenue exposure, most change frequency, most complex dependency graph, worst track record for change-induced incidents — and build the twin for those systems first. 

How to identify your highest-risk systems for twinning 

  • Change frequency — systems that are deployed to more than once per week are the highest-priority candidates because they generate the most change-induced incident risk 
  • Dependency centrality — systems that many other services depend on — payment APIs, authentication services, core data stores — have the highest blast radius when they fail 
  • Revenue exposure — systems that directly support revenue-generating flows should be prioritised, because the business case for twin investment is clearest and fastest to demonstrate 
  • Incident history — systems that have caused incidents in the last 12 months, particularly change-induced incidents, are proven high-risk areas where twin-based impact prediction delivers immediate value 

What a 90-day twin deployment looks like 

Weeks 1–2: Telemetry connection and auto-discovery. Connect the twin to the monitoring and observability stack for the target systems. Let auto-discovery run and validate the dependency graph against known architecture. Identify and fill data gaps. 

Weeks 3–6: Baseline and calibration. Run the twin in observation mode alongside normal operations. Validate that its impact predictions match real outcomes. Calibrate confidence thresholds. Build trust with the operations team by demonstrating prediction accuracy before using predictions for actual change decisions. 

Weeks 7–12: Active use in change management. Begin routing change requests for the target systems through the twin’s impact validation before deployment. Measure the rate of flagged changes that would have caused incidents. Begin expanding the dependency graph to adjacent systems. 

By week 12, a well-run deployment should have at least one measurable outcome: either a specific incident that was prevented by twin-based impact prediction, or a documented MTTR improvement for incidents that did occur. Both are straightforward to measure and straightforward to use as the business case for the next phase of expansion. 

Conclusion 

The monitoring problem in enterprise IT is not a tooling gap. It is a category gap. Monitoring tells you what the current state of each system is. It does not tell you what that state means for the rest of the environment, what the trajectory of that state will be in 20 minutes, or what will happen if you deploy a change into that state right now. No amount of additional monitoring closes that gap. 

A living digital twin closes it by providing something different in kind: a working model of the environment that understands relationships, evolves continuously from real telemetry, and can simulate what happens before it happens. The value is not in the visualisation. It is in the prediction — and in the operational decisions that prediction enables: changes that do not cause incidents, incidents that are diagnosed in minutes rather than hours, and business stakeholders who know what an infrastructure event means before they ask. 

The maturity curve from static asset model to living intelligent twin is not traversed in a single deployment. But it is traversed incrementally, and the value at each level is real. The organizations that start now — with a narrow scope, focused on their highest-risk systems and supported by telemetry-fed auto-discovery will have a three-year head start on the ones that wait for the category to mature further. 

Frequently Asked Questions 

What is a digital twin in IT operations? 

A digital twin in IT operations is a live, continuously updated model of your IT environment — its systems, services, dependencies, and relationships — that can simulate what happens when something changes or fails. Unlike monitoring, which observes the current state of each system, a digital twin understands how systems relate to each other, which allows it to predict the impact of changes and failures before they occur. Think of it as the difference between a speedometer (monitoring) and a navigation system that can predict traffic conditions and reroute based on what it knows about the road ahead (twin). 

What is the difference between a digital twin and AIOps? 

AIOps applies AI and machine learning to IT operations data — typically to detect anomalies, correlate alerts, and reduce noise. A digital twin is the environmental model that gives AIOps its context. AIOps without a twin can tell you that something looks anomalous. AIOps with a twin can tell you what that anomaly is likely to affect, what caused it, and what to do about it. The twin is the perception layer; AIOps is the analytical capability that operates on it. Most mature implementations combine both. 

How is a digital twin different from a CMDB? 

A CMDB (Configuration Management Database) is a record of what assets and configurations should exist in your environment, based on documentation and periodic discovery. It is manually maintained and typically reflects intended architecture rather than actual runtime  behavior. A digital twin is built from live telemetry and auto-discovery, reflecting what actually exists and how systems actually behave at runtime. The critical difference: a CMDB documents the environment as designed; a twin models it as deployed and operating. Most twin initiatives start with CMDB data as a seed and then update it continuously from live telemetry. 

How long does it take to build a digital twin for an enterprise IT environment? 

A functional twin for a specific set of high-priority systems can be operational within 4–8 weeks if the telemetry infrastructure is already in place. A comprehensive twin covering a full enterprise environment typically takes 6–18 months, depending on the complexity of data boundaries to cross, the quality of existing observability data, and the scope of business-layer integration. The most successful implementations start narrow — one business-critical system cluster — and expand progressively rather than attempting an enterprise-wide deployment from the start. 

What data does a digital twin need to work? 

At minimum: infrastructure metrics (CPU, memory, network, storage), service-level telemetry (API latency, error rates, throughput), and dependency discovery data (what is calling what). For full capability: application performance data, deployment records and change history, log correlation across services, business metric data (transaction volumes, conversion rates), and, in hybrid environments, OT/IoT sensor data for physical infrastructure. The more complete the telemetry, the more accurate the model. A twin built on incomplete data produces lower-confidence predictions and requires more calibration time. 

Can a digital twin be used for chaos engineering? 

Yes — and this is one of the highest-value use cases. A digital twin lets you run chaos scenarios against the model before introducing faults in the real environment. You can test what happens when a specific service fails, what the cascade looks like through the dependency graph, and which downstream systems are affected — without touching production. This does not replace real chaos experiments, but it dramatically reduces their risk by giving you advance knowledge of the blast radius. Teams use the twin to select safer experiment targets and to know exactly what to watch for when the experiment runs. 

Featured Image

Fifty-five percent of SAP customers have now deployed S/4HANA in some form. Only thirty-four percent have actually finished the transition. That gap between “live” and “done” is not a rounding error — it’s the story of most SAP migrations running right now, and it explains why so many of them slip past their own deadlines even when the underlying technology works exactly as designed.  

With SAP ERP 6.0’s mainstream maintenance ending December 31, 2027, for organizations on Enhancement Packages 6 through 8, the window to migrate without a rushed, high-risk scramble is closing. But new research from 2026 makes one thing clear: the organizations that miss this deadline mostly don’t miss it because of SAP. They miss it because of how the migration itself is run.  

The Deadline Everyone’s Watching, and the Number Nobody Talks About  

The mechanics of the deadline are simple enough. SAP ERP 6.0 on Enhancement Packages 6 through 8 loses mainstream maintenance on December 31, 2027. Extended maintenance is available as a bridge through December 31, 2030, at a 2 percentage-point surcharge on the maintenance base — after which only customer-specific maintenance remains, with no new fixes, no legal updates, and steadily increasing risk.  

What’s less discussed is where the industry actually stands against that date. SAPinsider’s 2026 ERP Migration and Transformation Benchmark puts current deployment at 55%, but only 34% of organizations have fully completed their transition. Of the rest, 41% plan to finish before the 2027 cutoff, 18% concede they won’t make it in time, and 7% have no migration plan at all.  

That 55%-to-34% gap is the number worth sitting with. An initial go-live is not a completed migration. Plenty of organizations are technically “live” on S/4HANA while running parallel systems, incomplete data models, and unresolved integration debt underneath — the exact conditions that turn a deadline-driven project into a multi-year scramble. If you’re mid-transition, our complete guide to SAP S/4HANA migration performance testing covers what a stable go-live actually requires. 

What Actually Derails SAP S/4HANA Migrations  

The ISG Data  

ISG’s State of SAP Migrations report, published in February 2026 and based on a survey of more than 200 senior decision-makers at large global companies, found that nearly 60% of SAP migration projects run late or over budget. The report’s authors point to underestimated complexity, scope that expands mid-project, and internal constraints nobody accounted for going in.  

The mechanism behind that number is organizational, not technical. Most migration programs run through multiple system integrators, SAP service providers, and niche specialists at once — and ISG’s research points to a lack of clear decision-making rights and acceptance criteria between them as a primary driver of the delays. Nobody owns the call, so the call doesn’t get made until it’s already a problem.  

A Second Study Says the Same Thing  

That pattern isn’t unique to one study. A 2025 Horváth survey of 200 SAP customer companies in the DACH region found the same 60% figure for projects missing budget, schedule, or quality targets — and identified business-process change as the single biggest hurdle, cited by 49% of respondents. It also surfaced a leadership gap: at smaller firms, the CEO personally leads the S/4HANA program in just 14% of cases.  

Two independent studies, on different populations, converging on the same root cause: this keeps getting run like an IT upgrade when it’s actually an enterprise transformation program. Our piece on navigating the SAP testing strategic approach to optimizing S/4HANA goes deeper on what that distinction means for test strategy specifically.  

The Quiet Trade-Off: Stability Now, Transformation Deferred  

Here’s what that pressure actually produces in practice. ISG’s research found that fewer than one in five organizations (18%) reimplement their processes and technology during the move to S/4HANA. Nearly half (49%) carry out little to no re-engineering at all, choosing instead to preserve legacy processes and data structures largely as they are.  

That’s a rational response to deadline pressure — moving data and process logic over unchanged is faster than redesigning it. But it doesn’t make the underlying problem disappear. It just moves it. Master data that’s fragmented or stale in ECC doesn’t become clean by virtue of running on HANA; it just runs faster. Every report, every forecast, and eventually every AI agent built on top of that data inherits whatever was already broken underneath it.  

Why This Matters More Now Than It Did Two Years Ago  

The stakes attached to that trade-off have shifted. SAPinsider’s 2026 Benchmark found that 43% of respondents now cite SAP’s AI roadmap — the Business AI Platform and Autonomous Suite announced at Sapphire 2026, including more than 200 specialized AI agents and 50 Joule Assistants — as the primary external factor shaping their ERP strategy. That’s ahead of the 2027 maintenance deadline itself, now cited by 39%.  

This isn’t a laggard problem, either. Even large, well-resourced programs are still mid-transition under this same pressure: Airbus’s digital leadership has publicly acknowledged that most of the company’s SAP migration work remains ahead of it, despite the 2027 timeline bearing down on a sprawling estate that still includes legacy SAP R/3 and ECC 6.0 systems.  

What changed is the cost of getting the data wrong. A fragmented Business Partner record used to mean finance and procurement disagreed on a report. Now it means every autonomous agent and AI forecast built on top of S/4HANA inherits that same fragmentation — and a technically successful interface exchange can still mask incorrect data underneath. Our post on true data integrity in SAP EDI processes walks through exactly how that plays out at the IDoc level.  

Discover, Govern, Validate, Operate: How QyrusAI Closes the Gap  

The pattern in both studies points to the same fix: treat the migration as a sequence of decisions to get right in order, not a single technical event. QyrusAI’s Modernize and Assure workspaces are built around exactly that sequence.  

Discover. Before you fix a single master record or commit to a migration path, you need an honest, evidence-based map of the SAP estate — not tribal knowledge or a stale architecture diagram. QyrusAI’s discovery capability inventories every integration (RFC, IDoc, REST/OData, SOAP, CPI iFlows) and scores each one for confidence and criticality, so scope gets locked before the project starts, not renegotiated mid-flight.  

Govern. The Business Partner model consolidates fragmented customer, vendor, and employee records into one master object per legal entity. Customer-Vendor Integration (CVI) is the bridge that keeps legacy and Business Partner records synchronized — and it needs to go in before conversion, not during it, with continuous deduplication and enrichment keeping records from fragmenting again after go-live.  

Validate. This is where QyrusAI’s Assure workspace does the heavy lifting. Qyrus Assure DataChain takes a single document or transaction number and maps every linked transaction across the flow — quotation, delivery, billing — cutting test data creation time by up to 92% and closing the “referential integrity nightmare” that makes manual test data setup for SAP such a bottleneck. Document Exchange (IDoc/EDI) Testing solves the specific problem covered above: it links every incoming IDoc to the business transaction it actually posted, catching the silent mapping flaws a “successful” technical status alone won’t reveal. This is the same approach that helped a $30B+ US automaker cut testing effort by 88% on its own complex SAP S/4HANA workflows. For more on closing the test data gap specifically, see the hidden tax on SAP projects and how DataChain eliminates it.  

Operate. Clean Core isn’t a milestone you hit once — it’s a discipline that erodes one “quick” core modification at a time. QyrusAI’s Autonomous Regression Suite keeps testing running after go-live, connecting to SAP’s standard APIs with no scripting required, so drift back into the core gets caught by a scheduled test run instead of discovered in production months later.  

Where to Start Your SAP S/4HANA Migration Governance  

The runway is shorter than the calendar suggests. For organizations planning to use extended maintenance as a bridge, SAP’s own guidance recommends completing that ordering process by Q3 2027 — which pulls the real decision point well ahead of the headline deadline.  

A few places to start regardless of where your program stands today:  

  • Map the estate first. Score every interface for confidence and criticality before you commit to a scope or a migration path.  
  • Stand up CVI early. Build the Business Partner bridge before conversion begins, not as a mid-project fire drill.  
  • Separate the obligatory cleanup from the discretionary work — and fund both. The fixes required for technical success (missing fields, postal formats) always get done because the system won’t go live without them. The fixes that create business value (deduplication, enrichment) are the first thing cut when the timeline tightens, and that’s exactly what erodes user trust in the new system on day one.  
  • Test the identity model, not just the interfaces. A clean Business Partner record only matters if it flows correctly through Lead-to-Cash and Source-to-Pay — prove that before go-live, not after.  

None of this changes the deadline. But it’s the difference between a migration your organization controls and one that controls you.  

Frequently Asked Questions  

What is the SAP S/4HANA 2027 deadline?  

December 31, 2027, is when SAP ends mainstream maintenance for SAP ERP 6.0 on Enhancement Packages 6 through 8. After that date, SAP no longer provides standard support, security patches, or legal updates for those releases unless an organization has purchased extended maintenance.  

What happens after SAP ECC mainstream maintenance ends?  

Organizations on Enhancement Packages 6–8 can purchase extended maintenance through December 31, 2030, at a 2 percentage-point surcharge on their maintenance base. After 2030, only reduced customer-specific maintenance is available, with no new fixes or legal updates.  

Why do most SAP S/4HANA migrations run over budget or behind schedule?  

Research from ISG and Horváth both point to governance failures rather than technology gaps: underestimated complexity, expanding scope, unclear decision rights across multiple vendors, and business-process change that gets underestimated going in.  

What is Customer-Vendor Integration (CVI) and why does it matter?  

CVI is the bridge that synchronizes legacy customer and vendor records into SAP’s unified Business Partner structure. It needs to be implemented before system conversion — not during or after — and it runs continuously to keep records in sync rather than functioning as a one-time migration step.  

What is SAP Clean Core?  

Clean Core is the practice of keeping custom logic out of the SAP core system and building it instead as side-by-side extensions on SAP Business Technology Platform (BTP). It has to be actively maintained after go-live, since even small core modifications accumulate and eventually degrade AI and automation capabilities built on top of the system.  

How long does an SAP S/4HANA migration typically take?  

Timelines vary by path: a brownfield conversion (keeping the existing system in place) typically runs 6 to 10 months, while a greenfield rebuild can take 12 to 36 months depending on customization volume and transformation ambition.  

How can QyrusAI help reduce SAP S/4HANA migration risk?  

QyrusAI combines estate discovery, Business Partner and CVI governance, AI-driven SAP test automation, and continuous post-go-live regression testing in one workspace — covering the full sequence from mapping the estate to keeping it clean after go-live.  

The Bottom Line  

The 2027 deadline is real, but it isn’t the thing most migrations actually fail against. The data is consistent across every study cited here: programs miss their targets because of how they’re governed, not because the underlying platform can’t get there. Mapping the estate honestly, governing to one clean identity, and testing before you trust the result is the sequence that keeps a deadline-driven program from becoming a multi-year rescue effort.  

Ready to see where your own SAP S/4HANA migration stands against this pattern? Request a QyrusAI demo to walk through your estate, your data governance gaps, and your testing coverage with the team.