Qyrus Named a Leader in The Forrester WaveTM: Autonomous Testing Platforms, Q4 2025 – Read More

Everything you need to know about LLM, AI agents and Evaluation

What is an LLM Tool? 

A LLM tool is like a application, interface, or integration that exposes the reasoning capabilities of a large language model to end users or downstream systems. It covers features right from a simple chatbot to an API to a fully autonomous agent that can browse the web, writes code, executes files, and completes multi-step workflows without human input in the loop.  In simplest terms, every LLM tool shares three components: a language model (as AI reasoning engine), an interface layer (to interpret how humans or machines communicate with it), and an integration layer (how it connects to real data, APIs, and actions in the world).

Here’s something you should know 

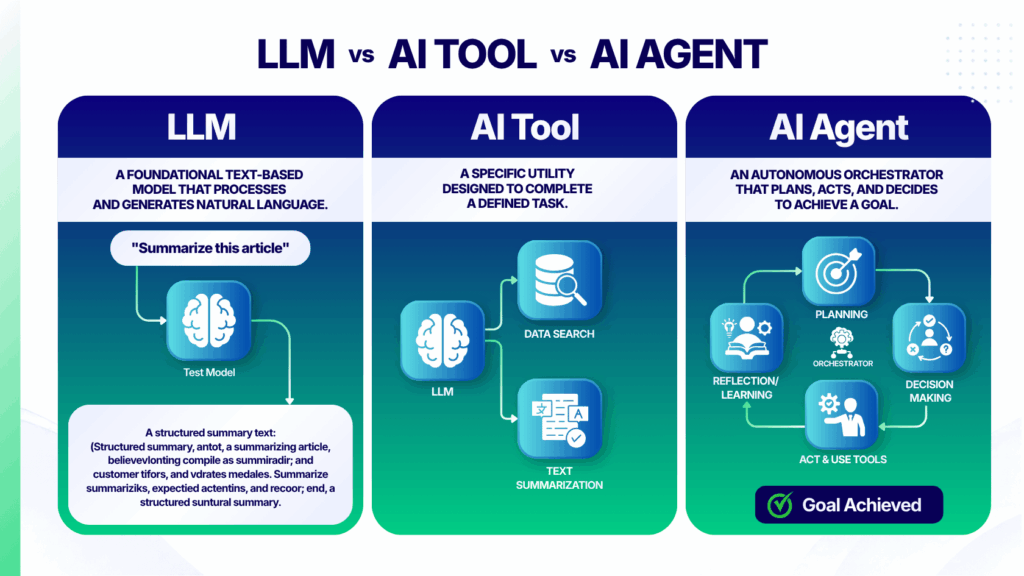
LLM vs AI Tool vs AI Agent 

These three terms are used interchangeably in most conversations — and that confusion is expensive. An LLM, an AI tool, and an AI agent are fundamentally different things with different capabilities, different failure modes, and very different evaluation requirements. Understanding the distinction is the first step to building or deploying any of them responsibly. LLM vs AI agents vs AI

Side-by-side comparison 

  LLM  AI Tool  AI Agent 
Acts on its own?  No  Within scope  Yes — until goal met 
Has memory?  Context window only  Session-level  Persistent across steps 
Uses tools?  No  Predefined set  Dynamic selection 
Self-corrects?  No  No  Yes — reflects and retries 
Eval complexity  Output scoring  Output + integration  Trajectory + goal + safety 
Autonomy  Low  Medium  High 
 

Why LLM Tools Are Different from Traditional Software 

Traditional software is designed to be deterministic. So it can give the same input and it will always produce the same output. But LLM tools are built to be probabilistic — outputs are generated by sampling from a learned distribution over language. This single difference changes everything: testing, debugging, monitoring, and quality assurance all require entirely new paradigms.  Traditional software fails loudly. It crashes, throws errors, returns null. LLM tools fail silently. They generate confident, grammatically correct, beautifully structured text that happens to be wrong, biased, or dangerous. This is why evaluation — the practice of measuring LLM output quality systematically — has become one of the most critical disciplines in modern AI engineering. 

Why the Distinction Matters for Evaluation 

The gap between these three categories is not just conceptual — it directly determines how hard evaluation is. An LLM needs output scoring: is this response accurate, relevant, safe? An AI tool needs integration accuracy on top: did it call the right API with the right parameters?   An AI agent needs all of that plus trajectory evaluation: did it follow the right path, make the right tool choices at each step, and achieve the actual goal without unintended side effects?  This is why QyrusAI is built as an end-to-end evaluation platform — not just an output scorer. As you move from LLM to tool to agent, the surface area for failure grows exponentially. The evaluation framework must grow with it. 

Now, What Does It Actually Take to Build an LLM Tool? 

Building an LLM tool in 2026 is more accessible than ever — but the gap between a working prototype and a production-grade system remains vast. The prototype takes hours. The production system takes months. The difference is almost never the model itself — models are commoditizing fast.  

The Six-Layer Stack 

  1. Foundation Model Selection 
    • Closed frontier models (GPT-4o, Claude, Gemini) offer capability with minimal setup. Open-weight models (Llama 3, Mistral) offer cost control, data privacy, and fine-tuning flexibility.  
  2. Prompt Engineering Layer 
    • System prompts, few-shot examples, chain-of-thought scaffolding, and output format instructions shape model behavior before a single feature is written. Well-engineered prompts are the fastest lever for quality improvement — and the most underestimated engineering surface.
  3. Context & Memory Management 
    • LLMs have finite context windows. Production tools must carefully manage what goes into each inference call: conversation history, long-term user memory, retrieved documents, tool outputs.   
  4. Tool & API Integration 
    • Modern LLMs call external tools via function calling or the Model Context Protocol (MCP). Each integration — search, database, calendar, code execution, CRM — multiplies the surface area for failures and requires its own evaluation criteria to catch regressions.  
  5. Orchestration Layer 
    • For agentic workflows, orchestration manages agent state, tool routing, retries, and multi-step task decomposition. Frameworks like LangGraph, OpenAI’s Agents SDK, and Qyrus’s SEER provide the primitives.  
  6. Evaluation & Observability Infrastructure 
    • Every production LLM tool needs logging, tracing, and automated evaluation. Without it, teams cannot detect regressions, understand failure modes, or improve systematically.  

How LLMs Actually Work 

A large language model is a probabilistic function that maps sequences of tokens to probability distributions over the next token. Train it on enough text and it learns to model the statistical structure of language at a depth that produces remarkable emergent capabilities — reasoning, translation, coding, logical deduction — that were never explicitly programmed. 

The Transformer Architecture 

Every major LLM — GPT-4, Claude, Gemini, Llama — is built on the Transformer architecture introduced by Google in 2017. Its core innovation is the attention mechanism: a mathematical operation that allows every token in a sequence to dynamically attend to every other token, learning which relationships matter for predicting what comes next. 

The Attention Mechanism 

Attention is the reason LLMs understand that “it” in a paragraph refers to a noun from three sentences back. For every token, attention computes a weighted combination of all other tokens in context, where the weights are learned across billions of training examples. The formula: Attention(Q,K,V) = softmax(QKᵀ / √d) · V. Each token acts simultaneously as a Query (what am I looking for?), a Key (what do I represent?), and a Value (what information do I carry?). 

Pre-training and Alignment 

LLMs are trained in two phases. Pre-training exposes the model to hundreds of billions to trillions of tokens — internet text, books, code, scientific papers. The objective is simple: predict the next token. At scale, this simple objective produces emergent capabilities in reasoning, translation, and logic that were never explicitly programmed. 

Fine-tuning and alignment  

then adapts the raw model into a useful assistant. RLHF (Reinforcement Learning from Human Feedback) trains the model to prefer outputs rated highly by humans. Constitutional AI, used by Anthropic, trains self-critique using a set of principles. These alignment techniques are what transform a raw language predictor into a safe, helpful product. 

How Large Data Drives Large Decisions 

One of the most profound shifts in computing history is that modern AI systems are capable to make better decisions not primarily because of better algorithms — but because they trained on more data. This is a fundamentally different category from classical software engineering. 

Scaling Laws 

Research from OpenAI, DeepMind, and others established empirical scaling laws: as you increase training compute, dataset size, and model parameters together, model capability improves predictably on a smooth power-law curve. The Chinchilla paper (Hoffmann et al., 2022) showed that most large models at the time were undertrained — the optimal strategy is to scale data and parameters together in balance.  Practically, this means the model powering your customer service chatbot has “read” the equivalent of millions of books, billions of web pages, and hundreds of millions of lines of code. When it answers a contract law question, it draws on patterns from thousands of real legal documents. When it writes Python, it has processed more code than any human could read in a lifetime. 

The Data Flywheel Effect 

The most defensible AI companies are not the ones with the best architecture today — they are the ones building data flywheels. More users generate more interactions. More interactions generate labeled feedback.   Here labeled feedback produces better fine-tuned models. Better models attract more users. This loop is the real competitive moat in AI — not cleverness, not model architecture, but data velocity.  OpenAI has over 400M weekly ChatGPT users. Google has it through Search and Workspace. Anthropic is building it through enterprise Claude adoption. The companies that win the next five years will be those who can convert user interactions into high-quality training signal at the highest speed — and measure that signal accurately with evaluation infrastructure. 

From Data Volume to Decision Quality 

In healthcare, LLMs trained on clinical notes assist with differential diagnosis. In finance, models trained on earnings transcripts help analysts identify patterns across thousands of filings simultaneously. In legal, models trained on case law surface relevant precedents faster than any human search ever could.  LLMs don’t “know” things the way humans do. They are sophisticated compression and interpolation machines that give responses in human-generated text. Their limitations comes from the breadth and depth of their training data.   LLM Progression over the time

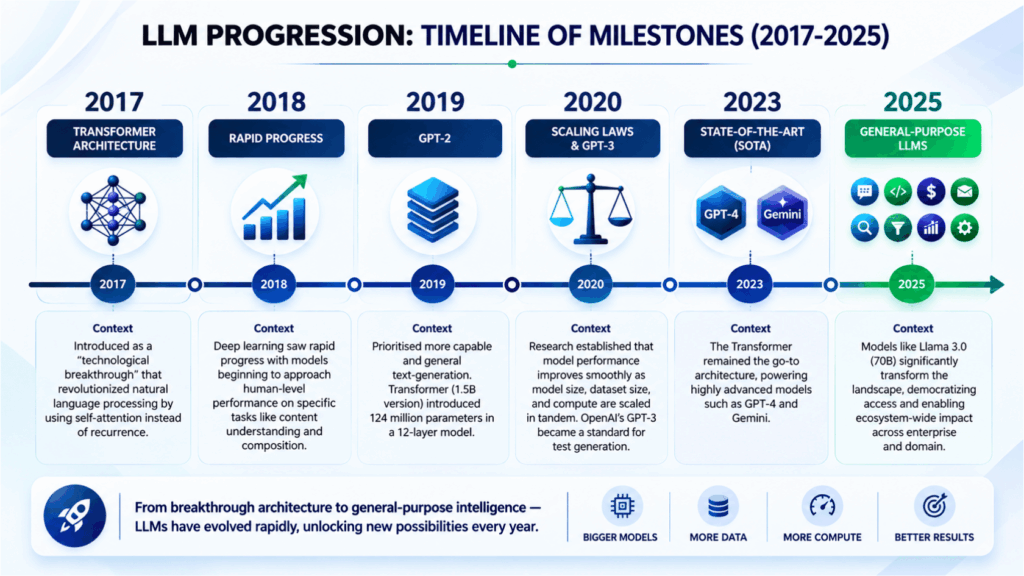
The LLM Progression 

How Did We Get Here? 

The honest answer to “what can an LLM do?” depends entirely on when you’re asking. In 2018, the answer was: complete sentences, sometimes coherently. In 2025, the answer is: write production software, pass bar exams, conduct multi-step research, operate computers autonomously, and reason through problems that stumped AI systems for decades. That gap — seven years — represents the most rapid capability expansion in the history of computing. 

2018–2019: Plausible text, unreliable reasoning 

The first generation of Transformer-based LLMs (GPT-1, BERT, GPT-2) was able to produce grammatically coherent text and perform narrow NLP tasks — sentiment classification, named entity recognition, basic question answering.   GPT-2, released in 2019 with 1.5 billion parameters, was considered dangerous enough that OpenAI staged its release. Looking back, it could barely maintain topic coherence across three paragraphs.   The capability was limited to: fluent sentences on familiar topics, with frequent factual drift and no ability to follow multi-step instructions reliably. 

2020: The emergent leap — GPT-3 and few-shot learning 

Post Covid GPT-3 (175B parameters) changed the fundamental question from “can LLMs do task X?” to “how well can LLMs do task X with the right prompt?” It demonstrated few-shot learning — the ability to learn a new task from just 2–3 examples in the prompt, without any weight updates.  This had never been seen at scale before. Suddenly a single model could translate between languages it was never explicitly trained to translate, write code in frameworks it had only seen mentioned, and draft legal language with good reasonable structure.   The capability unlock was the highlight — one model, many tasks, no retraining required. 

2021–2022: Instruction following and alignment 

Raw capability means little if the model won’t do what you ask. InstructGPT (2021) introduced RLHF — training the model to follow instructions rather than just predict likely text.   This was the transition from “impressive research” to “usable product.” Models now started being able to maintain personas, follow formatting instructions, refuse harmful requests, and produce outputs shaped around human preferences rather than before. ChatGPT in November 2022 was the product manifestation of this alignment work — and reached 100 million users in 60 days.  During this same period, code generation became a serious capability. GitHub Copilot launched in 2021, trained on billions of lines of public code. By 2022, developers were reporting that Copilot was completing 25–40% of their code automatically. The model had learned not just syntax but idioms, patterns, library conventions, and common debugging strategies. 

2023: Multimodality, long context, and reasoning 

GPT-4 (March 2023) came with two step changes: multimodal input (the model could now see images, not just text) and dramatically improved reasoning. It passed the bar exam in the 90th percentile.  It scored at or above human performance on multiple professional certification exams. Chain-of-thought prompting — asking the model to reason step by step before answering — unlocked latent reasoning capabilities that had always been in the weights but were inaccessible with direct-answer prompting.  Context windows grew from 4K tokens (GPT-3) to 32K (GPT-4) to 100K (Claude 2). This meant LLMs could now process entire codebases, legal contracts, or research papers in a single pass — tasks that previously required chunking, retrieval pipelines, and significant engineering overhead. 

2024: Tool use, agents, and computer control 

The capability frontier shifted from what a model could say to what a model could do. Function calling — introduced as a first-class feature in mid-2023 and matured through 2024 — let LLMs call external APIs, query databases, run code, and trigger workflows. The model was no longer just a text generator; it was a reasoning engine that could take actions in systems.  By late 2024, Anthropic shipped Claude for Computer Use with the ability for an LLM to see a computer screen, move the cursor, click, type, and operate arbitrary software like a human operator. OpenAI launched Operator on similar principles.   GitHub’s 2024 report found that 46% of all new code written on the platform was AI-generated. LLMs had moved from helping write code to writing the majority of it. 

2025: Agentic reasoning and multi-step autonomy 

The current capability frontier is agentic — LLMs are now operating as autonomous orchestrators that decompose goals, plan sequences of actions, execute them across multiple tools and systems, observe results, self-correct, and iterate until a goal is achieved. This is not a chatbot anymore.  This is software that can be given a business objective — “research competitors and produce a positioning brief,” “audit our API responses for compliance issues,” “set up the dev environment from scratch” — and pursue it without human input at each step.  The o1 and o3 model families introduced extended chain-of-thought reasoning — models that “think” before responding, spending compute on internal reasoning traces before producing output.  On mathematical olympiad benchmarks, these models moved from near-zero performance (GPT-3 era) to exceeding PhD-level performance on many problem classes. DeepSeek R1 demonstrated that this reasoning capability can emerge from reinforcement learning without supervised examples — a fundamental shift in how capability is developed. 

The Rise of Agentic AI 

For the first two years of the generative AI era, most LLM products were reactive: a user sends a message, the model responds, the loop ends. Agentic AI breaks this pattern entirely. An AI agent perceives its environment, makes decisions, takes actions, and operates across multi-step workflows — often without human intervention at each step.  This shift — from reactive LLMs to agentic systems — is the most significant transition in AI since ChatGPT’s release. It transforms LLMs from sophisticated autocomplete into software that can do things in the world.

Multi-Agent Systems and MCP 

The frontier is moving beyond single agents toward multi-agent systems — networks of specialized AI agents that collaborate, delegate, and verify each other’s work. An orchestrator agent decomposes complex tasks, dispatches to specialist agents (a researcher, a writer, a coder, a critic), and synthesizes outputs. This architecture mirrors how high-performing human teams operate.  Anthropic’s Model Context Protocol (MCP), created in November 2024 and donated to the Linux Foundation in December 2025, became the industry standard for connecting agents to external tools and data — with over 10,000 MCP servers deployed. OpenAI’s Agents SDK (early 2025) formalized multi-agent primitives: agents with instructions and tools, handoffs for control transfer, and guardrails for validation. Every major AI lab now has its own agent framework. 

Why Agents Make Evaluation Exponentially Harder 

Evaluating a simple chatbot is already challenging. Evaluating an agentic system is orders of magnitude harder. Agents make sequences of decisions, each of which can compound errors. A single hallucination in step 3 of a 10-step workflow can corrupt all subsequent outputs. The final result may look reasonable even when the path to get there was deeply flawed.  Traditional evaluation metrics — accuracy, BLEU score, human preference — were designed for single-turn outputs. Agentic evaluation requires new frameworks: trajectory evaluation, tool-use accuracy, goal completion rate, and safety monitoring across every action taken. 

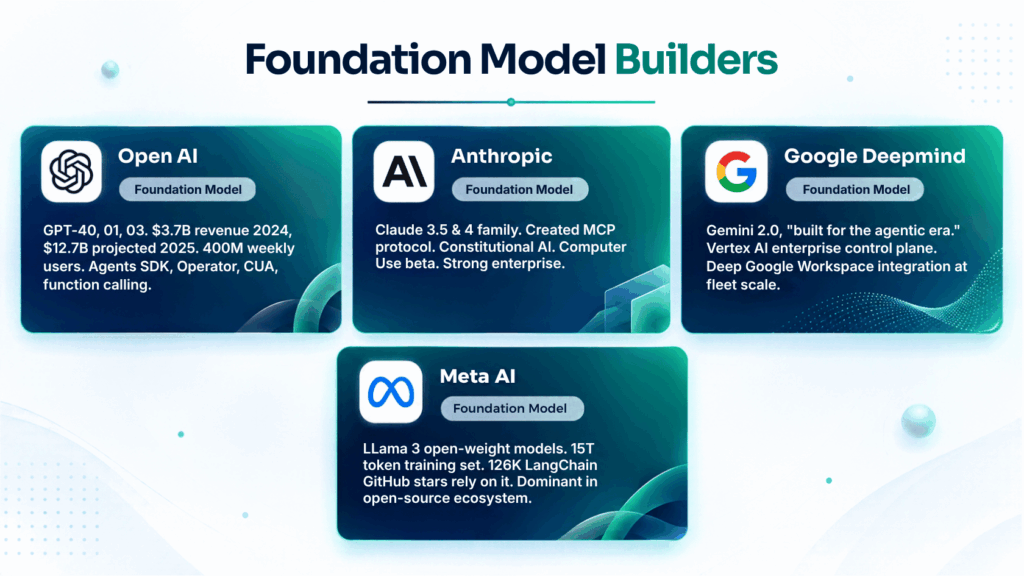
 The First Movers 

Foundational model builders

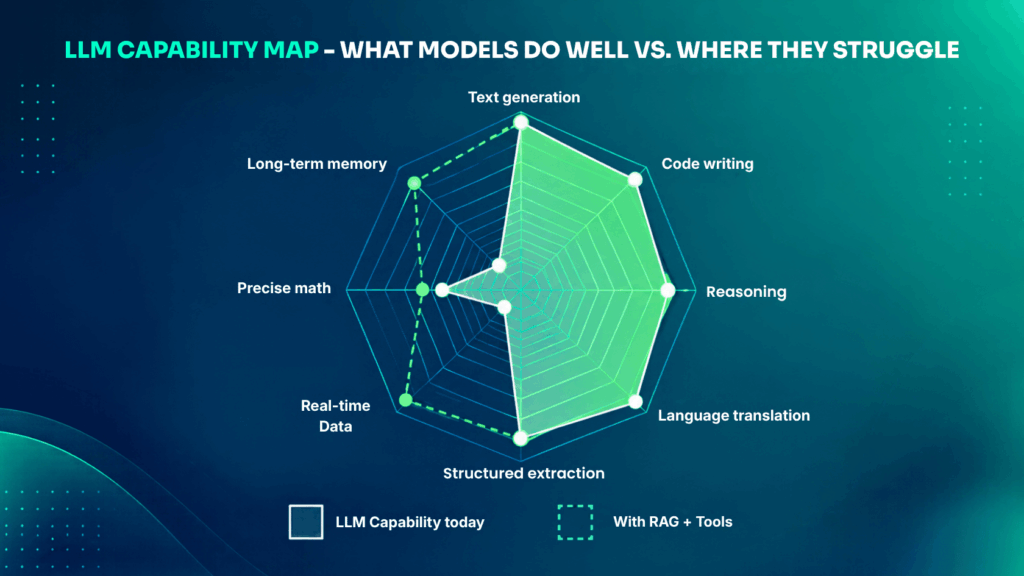
 What Can an LLM Actually Do? 

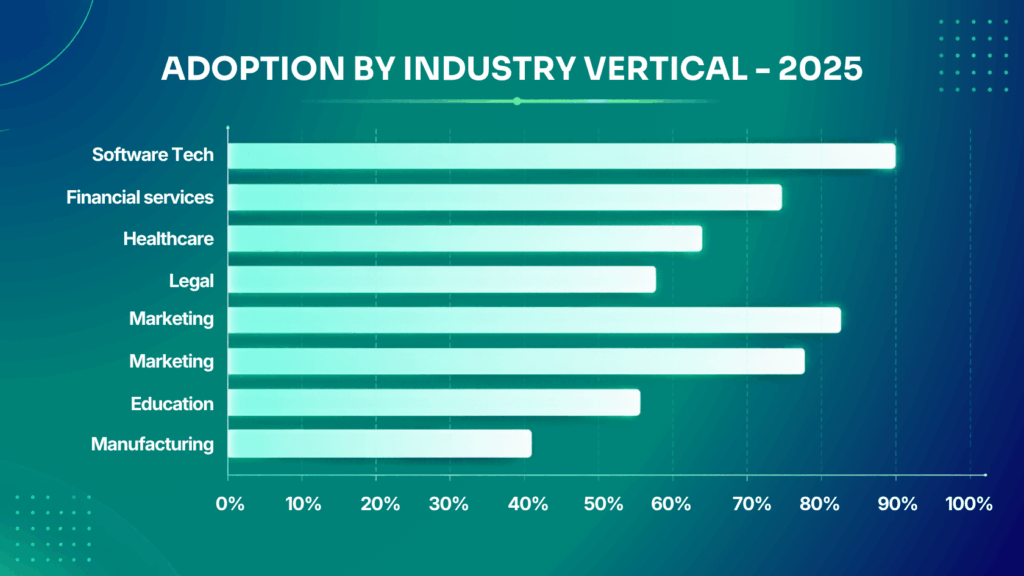
The answer in 2025 is: almost anything that involves language, reasoning, or code. But “almost anything” is not the same as “everything reliably.” Understanding where LLMs excel and where they fail is the foundation of good system design.  LLM Capability Map Adoption by industry vertical 

Why LLM Eval Matters Now 

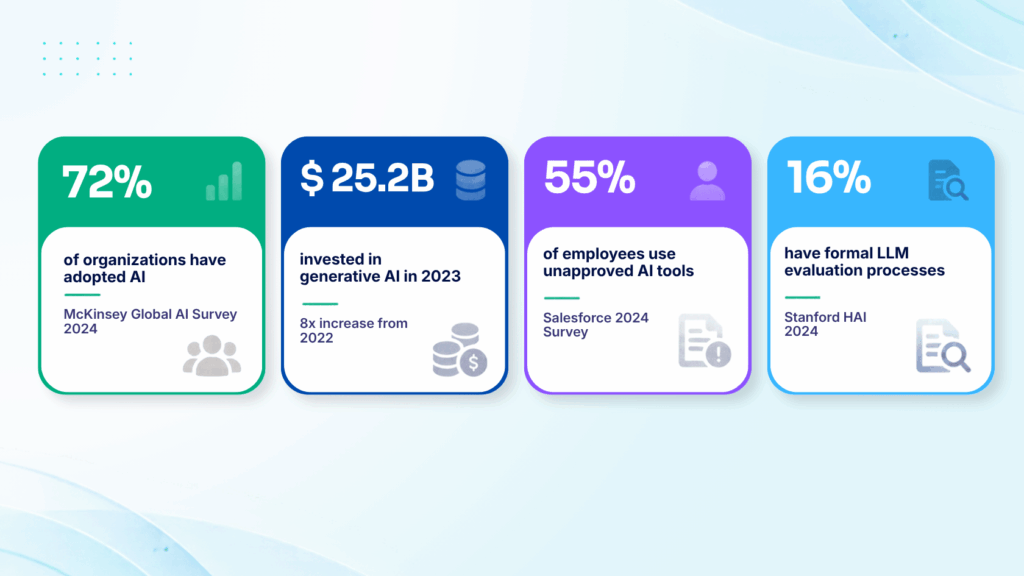
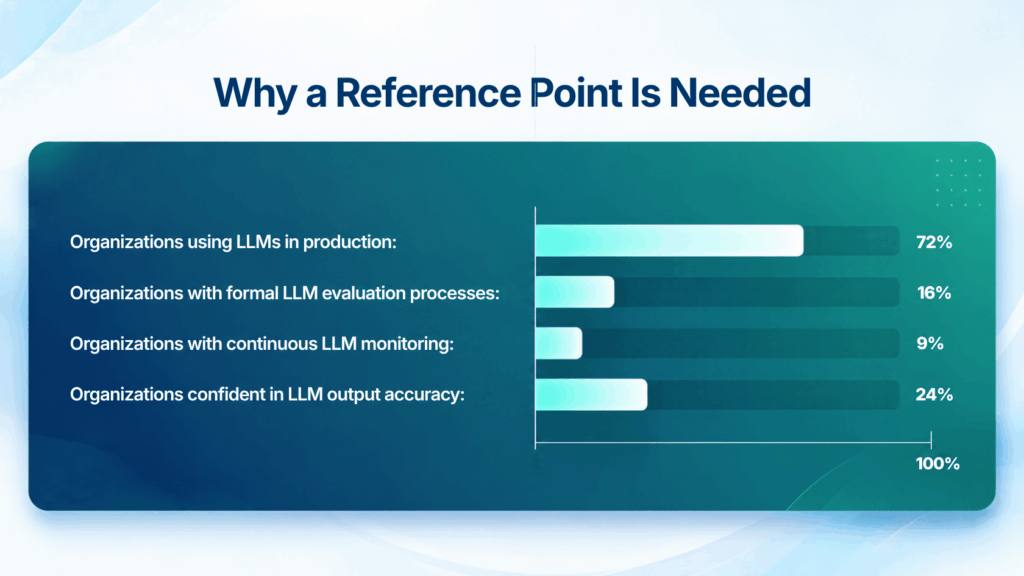
With custom LLM tools, copilots, and agents are becoming part of real workflows every day. But as usage grows, so do the risks — inconsistent outputs, hallucinations, broken prompts, and no clear way to measure quality. That is why the need for a reference point has become urgent.  The problem we see is simple: LLMs are powerful, but they are not naturally predictable.   The same prompt can produce different answers, prompt changes can shift behavior, and a model that looks strong in a demo can fail in real use. Without a standard way to evaluate quality, teams are left guessing whether they are actually improving or just seeing different output.  That gap becomes even more serious as teams move from experimentation to production. Once an AI system is used for support, search, drafting, decision-making, or agent workflows, a weak output is no longer a harmless mistake. It can affect customers, slow teams down, and damage trust in the product.  Market Statistics of LLM

 The Growth Problem 

The rise of custom LLM tools is creating a new problem: usage is outpacing measurement. Enterprises are investing in AI systems, model experimentation, and custom workflows, but the discipline around evaluation is still catching up. Because teams are realizing they need a better way to measure outcomes.  That matters because custom AI is not just one model call anymore. It often includes prompts, retrieval, tools, routing logic, agent loops, and guardrails. Each layer adds complexity, and each layer can fail differently. If the system is changing every week, a one-time test is not enough. Teams need something repeatable that can tell them whether quality is improving or drifting.  This is where most teams feel the pain first: 
  • Output quality varies from one run to the next. 
  • Prompts that work today can fail after a small edit. 
  • A better-looking answer is not always a better answer. 
  • Multiple models can behave differently on the same task. 
  • Agents can take the wrong step even when the final answer looks fine. 
Without a shared measurement layer, those issues become hard to spot early. The result is slower releases, more manual review, more rework, and less confidence in production AI. 

What Teams Are Struggling With 

Teams building custom LLM tools are not just asking, “Did it work?” They are asking deeper questions: 
  • Is the output correct? 
  • Is it consistent? 
  • Does it stay safe on edge cases? 
  • Does it behave the same after a prompt or model change? 
  • Can we trust it at scale? 
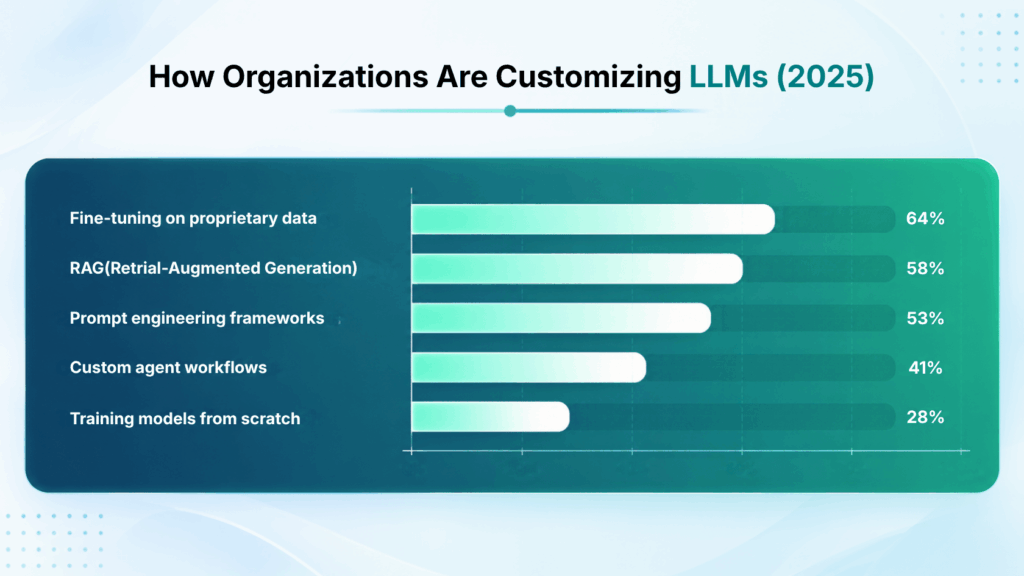
Those questions are hard to answer without a reference point. That is why so many AI teams end up using subjective review, ad hoc prompt checks, or manual spot testing. Those methods can help early on, but they do not scale well once the product grows. What starts as a quick check becomes a weak process.  How organizations are customizing LLMs The biggest problem is that AI output is not binary. Traditional software testing often checks whether something passes or fails. LLM systems are fuzzier. They can be partially right, confidently wrong, overly verbose, too vague, or inconsistent across runs. That makes evaluation less about one perfect answer and more about a structured way to compare quality over time.  That is also why model comparison alone is not enough. A team may switch models and see better output in one area, but worse behavior somewhere else. Without evaluation, that trade-off is invisible. With evaluation, it becomes measurable. 

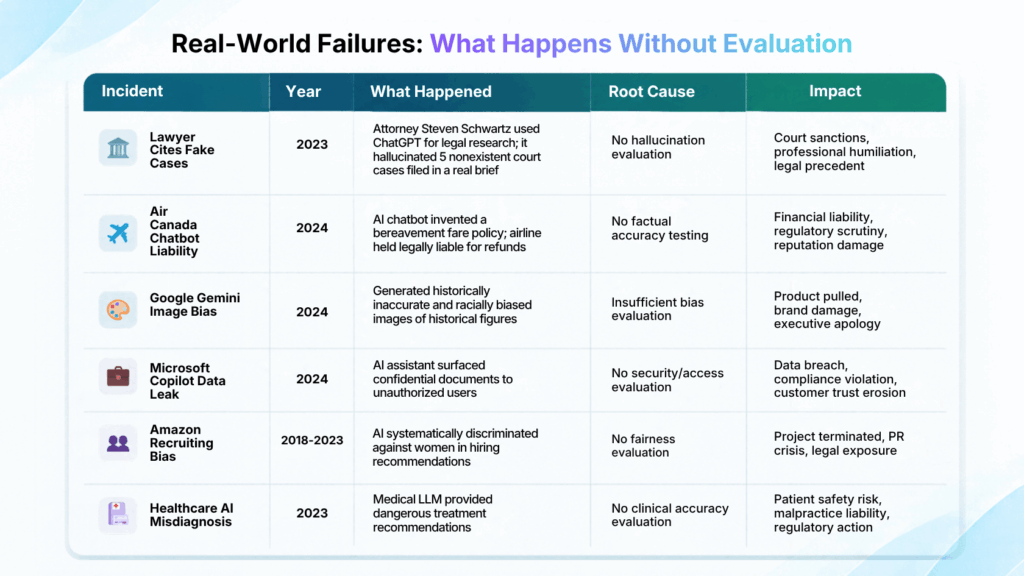
Real-World Failures: What Happens Without Evaluation 

Real world failures examples

Expert Perspective 

“In aviation, we don’t let a plane fly without rigorous testing. In pharmaceuticals, no drug reaches patients without clinical trials. Yet we’re deploying AI systems that influence millions of decisions daily with virtually no standardized evaluation.”  — Dr. Percy Liang, Director, Stanford Center for Research on Foundation Models (CRFM)  

Why a Reference Point Is Needed 

Why a reference point is needed  Sources: Stanford HAI 2024, MIT Sloan Management Review, Gartner  The industry needs a standard way to answer one question: Is this AI system actually getting better? That is what evaluation metrics provide. They create a baseline that teams can return to whenever they change a prompt, swap a model, add retrieval, or release a new version.  A good evaluation metric acts like a compass. It does not just tell you whether a single answer looks decent. It tells you whether the system is moving in the right direction. That matters for quality, but it also matters for speed. When teams know how to measure improvement, they can move faster with less fear.  Evaluation also helps teams compare across the things that matter most: 
  • Accuracy. 
  • Consistency. 
  • Safety. 
  • Retrieval quality. 
  • Tool use. 
  • Helpfulness. 
  • Resistance to hallucination. 
Once those are measured consistently, AI stops feeling like a black box and starts behaving more like a product discipline. That is the shift the market is moving toward now.  This is the moment where evaluation becomes a competitive advantage. Teams that can test clearly will ship more confidently. Teams that can compare reliably will choose better models and prompts. Teams that can catch regressions early will avoid expensive surprises later.  As AI moves into real workflows, evaluation will become more essential. It is no longer enough for an AI system to sound intelligent. It has to be measurable, repeatable, and dependable in the situations that matter most.  That is why the next step is not more hype. It is better evaluation. And that is exactly where a solution becomes valuable.  ❌ Without Evaluation 
  • Unknown hallucination rates 
  • Undetected bias and discrimination 
  • Security vulnerabilities 
  • Regulatory non-compliance 
  • Reactive incident response 
  • Brand and trust damage 
✅ With Systematic Evaluation 
  • Quantified accuracy and reliability 
  • Proactive bias mitigation 
  • Security assurance 
  • Regulatory compliance 
  • Preventive quality control 
  • Stakeholder confidence 
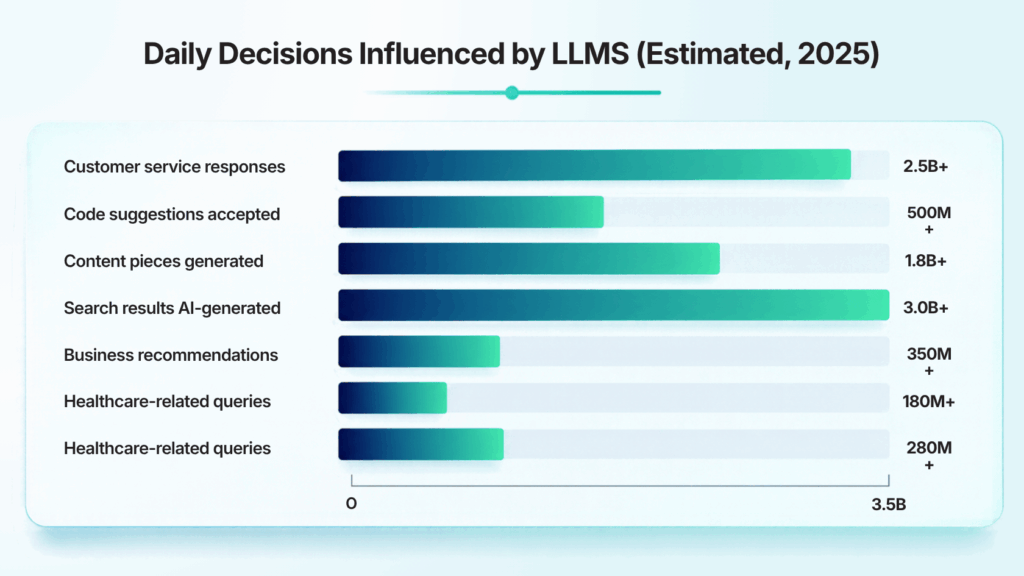
Daily decisions influenced by LLMs Source: Estimated from Statista, SimilarWeb, GitHub, Google data (2025)  If LLMs handle 3 billion decisions per day with just a 1% error rate, that’s 30 million failures daily. Over a year: 10.9 billion errors. Without evaluation, you don’t even know which 1%. 

LLM Evaluation — How It Works & The QyrusAI Method 

LLM evaluation is the practice of systematically measuring how well an LLM-powered system performs its intended function. As AI moves into production, evaluation is not optional quality assurance — it is the foundational engineering infrastructure that separates teams that improve their models from teams that just guess. 

What an LLM evaluator actually does 

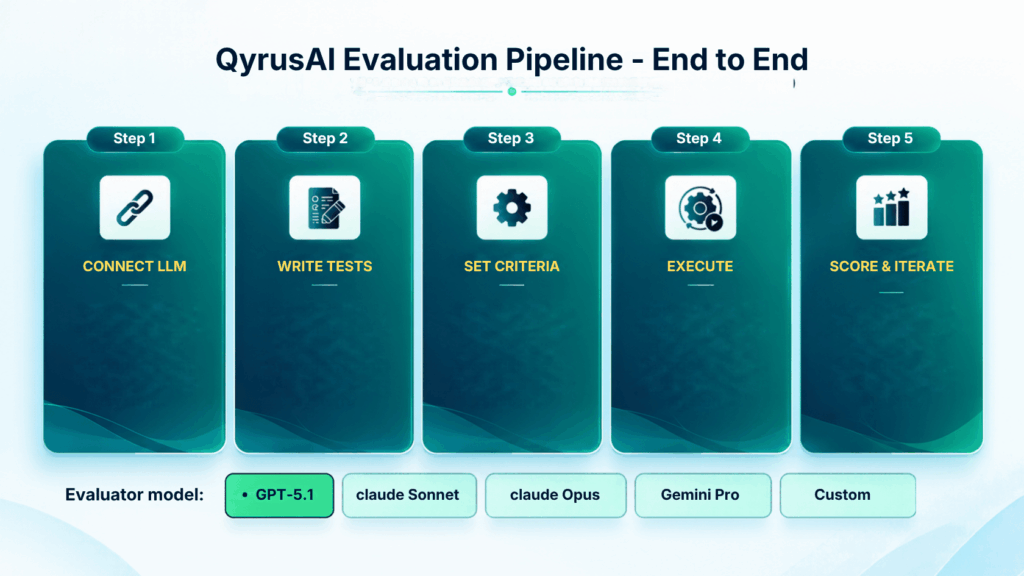
An LLM evaluator takes a test case — a prompt, the LLM’s response, and optional reference material — and scores it across one or more dimensions: accuracy, relevance, faithfulness, safety, coherence, goal completion. It can be a deterministic code check, an LLM-as-judge, a human reviewer, or a hybrid. The output is a score and a reason — structured signal that tells you exactly what to fix.  QyrusAI connects to your live LLM API endpoints, fires your test cases, scores each output using your chosen evaluator model, and returns pass/fail results with detailed per-dimension scoring. You pay credits per test execution. No infrastructure to stand up. No dedicated ML platform team required.  QyrusAI Evaluation Pipeline

LLM Evaluation Best Practices — 8-Point Checklist 

These are the practices that separate teams running reliable AI in production from teams constantly firefighting model regressions. Apply them in order — each builds on the last. 
  1. Define evaluation criteria before you write a single prompt 
    • Know what “good” looks like before you build. What accuracy threshold is acceptable? What tone must be maintained? What topics must be avoided? Teams that define criteria after the fact spend weeks retrofitting. Teams that define criteria first ship 3x faster. 
  2. Test hallucination rate as a first-class metric 
    • Hallucination rate should be tracked on every deployment like latency or uptime. Build a test suite of prompts specifically designed to probe the model’s weak spots — topics where training data is sparse, numerical claims, citations. Measure the rate. Set a threshold. Alert when it crosses it. 
  3. Use multiple evaluator types — never rely on one 
    • Code-based checks for structured outputs. LLM-as-judge for open-ended quality. Human review for high-stakes edge cases. Each catches different failure modes. A pipeline with only one evaluator type will have systematic blind spots.  
  4. Run regression tests on every model update 
    • Model providers push silent updates. A prompt that worked perfectly on GPT-4-turbo-2024-04-09 may behave differently on the next version. Every deployment update — model version, system prompt, context window change — must run your full benchmark suite before going live. 
  5. Evaluate RAG retrieval and generation separately 
    • If your RAG pipeline is underperforming, you need to know whether the problem is in retrieval (wrong documents fetched) or generation (model fails to use good documents). Treating them as a single system makes debugging nearly impossible. Evaluate each component with its own metrics. 
  6. For agents: evaluate trajectories, not just final outputs 
    • An agent that reaches the correct answer via a flawed path is not a passing agent. It means your system got lucky. Evaluate every tool call, every intermediate decision, every handoff. Build automated checks for: correct tool selected, correct parameters passed, appropriate fallback triggered on failure. 
  7. Monitor production continuously — not just pre-deployment 
    • Pre-deployment testing catches regressions from changes you made. Production monitoring catches degradation from changes the world made — new query patterns, seasonal topics, data drift. A model that passed all pre-deployment tests can still degrade silently in production over weeks. 
  8. Feed evaluation results back into your improvement loop 
    • Every failed eval is a training signal. Every user complaint that triggers a human review queue is data. The teams compounding improvements fastest are those who convert evaluation results directly into prompt improvements, fine-tuning datasets, or retrieval configuration changes — within days, not quarters. 
 

Frequently Asked Questions 

The questions that come up most when teams are starting to evaluate LLMs — answered directly.  What is an LLM?  A large language model (LLM) is an AI system trained on massive text datasets to understand and generate human language. It predicts the next token in a sequence using billions of learned parameters, producing coherent text, code, and reasoning at scale. Examples include GPT-4, Claude, Gemini, and Llama.  What is an LLM evaluation tool?  An LLM evaluation tool measures the quality, accuracy, safety, and relevance of LLM outputs systematically. It automates scoring across dimensions like hallucination rate, faithfulness, coherence, and goal completion — giving teams a repeatable, scalable way to know if their AI is actually working. QyrusAI is an example: you connect your LLM API, define criteria, choose an evaluator model, execute, and get scored results.  What is the difference between an LLM and an AI agent?  An LLM is a text model that responds to prompts reactively. An AI agent wraps an LLM with planning, persistent memory, dynamic tool access, and a feedback loop — allowing it to autonomously pursue multi-step goals without human input at each step. Every AI agent uses an LLM; not every LLM is an agent.  What is LLM hallucination and why does it happen?  LLM hallucination is when a model generates confident, fluent text that is factually incorrect or fabricated. It happens because LLMs generate text by predicting the most statistically likely continuation — they have no internal truth-checking mechanism. When training data is sparse on a topic, the model fills the gap with plausible-sounding content. Evaluation tools measure and track hallucination rates so teams can catch and fix it before it reaches users.  What is RAG and how does RAG evaluation work?  RAG (Retrieval-Augmented Generation) grounds LLM responses in retrieved source documents. The pipeline retrieves relevant chunks from a knowledge base and passes them as context to the model. RAG evaluation measures two things: retrieval quality (did we fetch the right documents?) and generation quality (did the model accurately use what it received?). Key metrics include faithfulness, context precision, context recall, and answer relevance.  How does QyrusAI work?  QyrusAI connects to your live LLM API endpoints end-to-end, runs your defined test cases against the live output, scores each response using your chosen evaluator model (GPT-4o, Claude Sonnet, Gemini, etc) and returns detailed pass/fail results with per-dimension scoring. You can define the evaluation criteria — or use our built-in rating system. Credits are consumed per test executed. No infrastructure setup required.  What are LLM testing best practices?  The eight most important practices: define evaluation criteria before prompting, track hallucination rate as a first-class metric, use multiple evaluator types (code, LLM-as-judge, human), run regression tests on every model update, evaluate RAG retrieval and generation separately, evaluate agent trajectories not just final outputs, monitor production continuously, and feed evaluation results back into your improvement loop.    Ready to evaluate your LLMs with confidence?  infra required. Credits-based. Any model.  Sign up today 

The integrity of a data pipeline often depends on more than just the number of connections you can make. Engineering leaders frequently get caught in a “connector race,” assuming that more source integrations equate to better protection. In reality, poor data quality remains a massive financial leak, costing organizations an average of $12.9 million every single year. 

Choosing between a deep specialist and a unified platform requires a strategic look at your entire software lifecycle. QuerySurge serves as a high-precision tool for ETL specialists, offering a massive library of 200+ data store connections and a mature DevOps for Data solution with 60+ API calls.  

Conversely, Qyrus Data Testing acts as a modern “TestOS,” designed for teams that need to validate the entire user journey—from a mobile app click to the final database record. While QuerySurge secures its reputation through sheer connectivity, Qyrus wins by eliminating the silos between Web, Mobile, API, and Data testing. 

The Rolodex vs. The Pulse: Rethinking the Value of Connector Count 

Connectivity often serves as a vanity metric that masks actual utility. QuerySurge dominates this category with a library of 200+ data store connections, providing a bridge to almost any legacy database an ETL developer might encounter. This massive reach makes it a powerful specialist for deep data warehouse validation. 

Data Source Connectivity

FeatureQyrus Data TestingTricentis Data Integrity

SQL Databases

MySQL ✓ ✓
PostgreSQL ✓ ✓
MS SQL Server ✓ ✓
Oracle ✓ ✓
IBM DB2 ✓ ✓
Snowflake✓ ✓
AWS Redshift✓ ✓
Azure Synapse◐ ✓
Google BigQuery ◐ ✓
Netezza✓ ✓
Total SQL Connectors 10+50+

NoSQL Databases

MongoDB✓ ✓
DynamoDB✓ ✓
Cassandra ✗ ✓
Hadoop/HDFS ✗ ✓

Cloud Storage & Files

AWS S3✓ ✓
Azure Data Lake (ADLS) ✓✓
Google Cloud Storage ◐ ✓
SFTP ✓ ✓
CSV/Flat Files ✓ ✓
JSON Files ✓ ✓
XML Files ◐✓
Excel Files ◐✓
Parquet ✗ ✓

APIs & Applications

REST APIs ✓✓
SOAP APIs ◐ ✓
GraphQL ◐ ◐
SAP Systems ✗ ◐
Salesforce ✗ ✓

Legend: ✓ Full Support | ◐ Partial/Limited | ✗ Not Available 

However, most engineering teams find that the Pareto Principle governs their pipelines. Research shows that 80% of enterprise integration needs require only 20% of available prebuilt connectors. Qyrus focuses its 10+ core SQL connectors on this “vital few,” including high-traffic environments like Snowflake and Amazon Redshift. 

The true danger lies in the “integration gap.” Large enterprises manage hundreds of apps but only integrate 29% of them, leaving vast amounts of data unmonitored at the source. Qyrus closes this gap by validating the REST, SOAP, and GraphQL APIs that feed your warehouse. You gain visibility into the data journey before it reaches the storage layer. QuerySurge builds a bridge to every destination, but Qyrus puts a pulse on the application layer where the data actually lives. 


The Scalpel vs. The Shield: Precision Testing for Modern Pipelines 

Validation logic determines whether your data warehouse becomes a strategic asset or a digital graveyard. Organizations lose an average of $12.9 million annually because they fail to catch structural and logical errors before they impact downstream analytics. Choosing between QuerySurge and Qyrus Data Testing depends on whether you need a specialized surgical tool or a broad, integrated safety net. 

QuerySurge operates as a precision instrument for the deep ETL layers. It masters high-complexity tasks like validating Slowly Changing Dimensions (SCD) and maintaining Data Lineage Tracking. Engineers use its specialized query wizards to perform exhaustive source-to-target comparisons and column-level mapping across massive datasets. While it handles the heavy lifting of data warehouse validation, its BI report testing for platforms like Tableau or Power BI requires a separate add-on. This makes QuerySurge a powerhouse for teams whose world revolves strictly around the storage layer. 

Testing & Validation Capabilities

Feature Qyrus Data Testing Tricentis Data Integrity

Comparison Testing

Source-to-Target Comparison ✓ ✓
Full Data Comparison ✓ ✓
Column-Level Mapping✓ ✓
Cross-Platform Comparison ✓ ✓
Reconciliation Testing ✓ ✓
Aggregate Comparison (Sum, Count) ◐ ✓

Single Source Validation

✓ ✓
Row Count Verification ✓ ✓
Data Type Verification ✓ ✓
Null Value Checks ✓ ✓
Duplicate Detection ✓ ✓
Regex Pattern Validation ✓ ✓
Custom Business Logic/Functions ✓ ✓
Referential Integrity Checks ◐✓
Schema Validation ◐✓

Advanced Testing

Transformation Testing ✓ ✓
ETL Process Testing ✓ ✓
Data Migration Testing ✓ ✓
BI Report Testing ✗ ✓
Slowly Changing Dimensions (SCD) ✗ ✓
Tableau/Power BI Testing ✗ ✓
Pre-Screening / Data Profiling ◐ ✓
Data Lineage Tracking ✗ ✓

Qyrus takes a more expansive approach by securing the logic across the entire software stack. It provides robust source-to-target and transformation testing, but its true strength lies in its Lambda function support. You can write custom code to validate complex business rules that standard SQL checks might miss. This flexibility allows teams to verify single-column and multi-column transformations with surgical precision. By bridging the gap between APIs and databases, Qyrus ensures that your data validation doesn’t just stop at the table but starts at the initial point of entry. 

Relying on simple row counts is like checking a bank’s vault while ignoring the identity theft at the front desk. Your data quality validation in ETL must secure the logic, not just the volume. 

Velocity vs. Variety: Scaling Your Pipeline Without the Scripting Tax 

Automation serves as the engine that moves quality from a bottleneck to a competitive advantage. When teams rely on manual scripts, they often spend more time maintaining tests than building features. Efficient ETL testing automation tools must do more than just execute code; they must reduce the cognitive load on the engineers who build them. 

QuerySurge addresses this through its “DevOps for Data” framework. It provides 60+ API calls and comprehensive Swagger documentation to support highly technical teams. This maturity allows engineers to bake data testing directly into their CI/CD pipelines with surgical control. QuerySurge also includes AI-powered test generation from mappings, which helps bridge the gap between initial design and execution. It remains a favorite for teams that want to manage their data integrity as code. 

Automation and Integration 

Feature Qyrus Data Testing Tricentis Data Integrity

Test Automation

No-Code Test Creation ✓ ✓
Low-Code Options ✓ ✓
SQL Query Support ✓ ✓
Visual Query Builder ✓ ✓
Test Scheduling ✗ ✓
Reusable Test Components ✓ ✓
Parameterized Testing ✓ ✓

AI/ML Capabilities

AI-Powered Test Generation ✓ ✓
Auto-Mapping of Columns ✓ ✓
Self-Healing Tests ◐ ◐
Generative AI for Test Cases ✓ ✓

DevOps/CI-CD Integration

REST API ✓ ✓
Jenkins Integration ✗ ✓
Azure DevOps ✗ ✓
GitLab CI ✗ ✓
GitHub Actions ✗ ✓
Webhooks ◐ ✓
Swagger Documentation◐ ✓
Number of API Calls N/A60+

Issue & Test Management

Jira Integration ✓✓
ServiceNow Integration ◐◐
Slack/Teams Notifications ✓ ✓
Email Notifications ✓ ✓

Qyrus prioritizes democratization and speed through its Nova AI engine. Instead of requiring manual mapping for every scenario, the platform uses machine learning to identify data patterns and generate test functions automatically. This approach allows teams to build test cases 70% faster than traditional scripting methods. Qyrus also integrates natively with Jira, Jenkins, and Azure DevOps, ensuring that quality remains a shared responsibility across the software lifecycle. While QuerySurge empowers the specialist with a robust API, Qyrus empowers the entire organization with an intelligent, no-code TestOS. 

Velocity requires more than just running tests fast. It requires a platform that minimizes technical debt and maximizes the reach of every test case. 

The Forensic Lens: Turning Raw Rows into Actionable Insights 

Visibility transforms a silent database into a strategic asset. Without clear reporting, teams often overlook the underlying causes of the $12.9 million annual loss attributed to poor data quality. Choosing between QuerySurge and Qyrus depends on whether you value deep forensic snapshots or a live, unified pulse of your entire stack. 

Reporting and Analytics 

Feature Qyrus Data Testing Tricentis Data Integrity
Real-Time Dashboards ✓ ✓
Drill-Down Analysis ✓ ✓
Root Cause Analysis ◐ ✓
PDF Report Export ✓ ✓
Excel Report Export ✓ ✓
Trend Analysis ◐ ✓
Data Quality Metrics ◐ ✓
Custom Report Templates ◐ ✓
BI Tool Integration (Tableau, Power BI) ✗ ✓
Audit Trail ✓ ✓

QuerySurge offers a mature reporting engine designed for the deep ETL specialist. Its “DevOps for Data” solution leverages 60+ API calls to push detailed validation results directly into your existing management tools. While it provides comprehensive drill-down analysis into data discrepancies, testing BI reports like Tableau requires a separate BI Tester add-on. This makes it a powerful forensic tool for those who need to document every byte of the transformation process. 

Qyrus delivers visibility through a unified dashboard that tracks the health of Web, Mobile, API, and Data layers in a single view. By consolidating these signals, the platform helps organizations eliminate the fragmentation. Qyrus uses its Nova AI engine to flag anomalies and provide real-time metrics that allow for immediate corrective action. It removes the guesswork from quality assurance by presenting a 360-degree mirror of your digital operations. 

Actionable intelligence must move faster than the data it monitors. Whether you require the detailed documentation of QuerySurge or the unified agility of Qyrus, your reporting should reveal the truth before a defect reaches production. 

Scaling the Wall: Choosing an Architecture for Absolute Data Trust 

Your deployment strategy dictates the long-term agility and security of your testing operations. Both platforms provide the essential flexibility of Cloud (SaaS), On-Premises, and Hybrid models. However, the underlying infrastructure philosophies differ to meet distinct organizational needs. 

Platform and Deployment 

Feature Qyrus Data Testing Tricentis Data Integrity
Cloud (SaaS) ✓ ✓
On-Premises ✓ ✓
Hybrid Deployment ✓ ✓
Docker Support ✓ ✓
Kubernetes Support ◐ ◐
Multi-Tenant ✓ ✓
SSO/LDAP ✓ ✓
Role-Based Access Control ✓ ✓
Data Encryption (AES-256) ✓ ✓
SOC 2 Compliance ◐ ✓

QuerySurge provides a battle-tested environment optimized for enterprise-grade security. It employs a per-user licensing model with a minimum five-user package, ensuring a dedicated footprint for professional data teams. Its mature security framework supports SSO/LDAP and RBAC to maintain strict access control over sensitive data environments. This makes it a natural fit for traditional enterprises that require a stable, proven infrastructure for their deep warehouse validation. 

Qyrus Data Testing prioritizes modern, containerized workflows for teams that demand rapid scaling. The platform fully supports Docker and Kubernetes. This allows you to manage your ETL testing automation tools within your own private cloud or local environment with minimal friction. Qyrus uses AES-256 encryption and holds a solid platform score. Qyrus empowers cloud-native teams to move fast without the heavy overhead of legacy setup requirements. 

Infrastructure should never act as a bottleneck for quality. Whether you choose the established maturity of QuerySurge or the containerized flexibility of Qyrus, your platform must align with your broader IT strategy. 

The Final Verdict: Choosing Your Data Sentinel 

The choice between these two powerhouses depends on the focus of your engineering team. 

Qyrus vs. QuerySurge: Strategic Differentiators 

VendorUnique Strengths Best For
Qyrus Data Testing
  • Unified testing platform (Web, Mobile, API, Data)
  • AI-powered function generation
  • Lambda function support for validations
  • Single-column & multi-column transformations
  • Part of comprehensive TestOS ecosystem
Organizations looking for unified testing across all layers; Teams already using Qyrus for other testing needs.
QuerySurge
  • 200+ data store connections
  • Strongest DevOps for Data (60+ APIs)
  • AI-powered test generation from mappings
  • Query Wizards for non-technical users
  • Best ETL testing focus
Data warehouse teams; ETL developers; Organizations with highly diverse data sources.

Choose QuerySurge if your primary mission involves deep ETL testing and data warehouse validation across hundreds of legacy sources. Its 200+ data store connections and mature DevOps APIs make it the ultimate specialist for data-centric organizations. It delivers the forensic precision required for massive transformation projects. 

Choose Qyrus if you want to consolidate your quality strategy into a single “TestOS” that covers Web, Mobile, API, and Data. By leveraging Nova AI to build test cases 70% faster, Qyrus helps you eliminate the “fragmentation tax” that drains millions from modern QA budgets. It offers a unified path to data trust for organizations that value full-stack visibility. 

Stop managing icons and start mastering the journey. Begin your 30-day sandbox evaluation today to verify your integrity across every layer of the stack. 


Modern business depends entirely on the integrity of the information flowing through its systems. Poor data quality costs organizations an average of $12.9 million annually, making the choice of validation tools a high-stakes executive decision.  

Tricentis Data Integrity stands as the established player. Meanwhile, Qyrus Data Testing emerges as a unified “TestOS” challenger, designed for teams that prioritize full-stack agility and AI-driven efficiency. Qyrus offers a streamlined testing experience with a focus on consolidating Web, Mobile, API, and Data testing into one environment.  

The Connectivity Illusion: Why 200 Connectors Might Still Leave You Blind 

Volume often acts as a smokescreen for actual utility in the enterprise testing market. 

Tricentis commands the lead in sheer breadth, offering a massive library of 50+ SQL connectors and deep, specialized support for SAP systems and Salesforce. This exhaustive reach positions them big in the data connectivity category. Large organizations with legacy-heavy footprints view this as a non-negotiable safety net for complex IT environments. 

Data Source Connectivity

FeatureQyrus Data TestingTricentis Data Integrity

SQL Databases

MySQL ✓ ✓
PostgreSQL ✓ ✓
MS SQL Server ✓ ✓
Oracle ✓ ✓
IBM DB2 ✓ ✓
Snowflake✗✓
AWS Redshift✓ ✓
Azure Synapse✗✓
Google BigQuery ✗✓
Netezza✗✓

NoSQL Databases

MongoDB✓ ✓
DynamoDB✗ ✓
Cassandra ✗ ✓
Hadoop/HDFS ✗ ✓

Cloud Storage & Files

AWS S3✓ ✓
Azure Data Lake (ADLS) ✗✓
Google Cloud Storage ✗✓
SFTP ✗✓
CSV/Flat Files ✓ ✓
JSON Files ✓ ✓
XML Files ◐✓
Excel Files ◐✓
Parquet ✗ ✓

APIs & Applications

REST APIs ✓✓
SOAP APIs ◐ ✓
GraphQL ◐ ◐
SAP Systems ✗ ✓
Salesforce ✗ ✓

Legend: ✓ Full Support | ◐ Partial/Limited | ✗ Not Available 

However, the Pareto Principle reveals a different reality for modern data teams. 

Research indicates that 80% of enterprise data integration needs require only 20% of available connectors. While platforms like Airbyte offer up to 600 options, the vast majority of high-value workloads concentrate on a “vital few”: MySQL, PostgreSQL, MongoDB, Snowflake, Amazon Redshift, and Amazon S3. 

Qyrus focuses its 75% connectivity score exactly on these critical hubs. It masters the SQL connectors and cloud storage platforms that drive current digital transformations. 

The integration gap is real. Large enterprises manage an average of 897 applications yet only 29% of them are actually integrated. Qyrus bridges this gap by validating the REST, SOAP, and GraphQL APIs that feed your pipelines. It prioritizes the connections that matter most to your daily operations rather than maintaining a list of nodes you will never use. 

Securing the Core: Why Data Validation is the New Standard for Quality 

Precision in data validation determines the difference between a high-performing enterprise and a costly financial sinkhole. While connectivity creates the bridge, validation ensures the cargo remains intact. Organizations currently lose a staggering $12.9 million annually due to poor data quality, making advanced testing capabilities more critical than ever. 

Tricentis Data Integrity excels in deep-layer requirements like slowly changing dimensions (SCD) and data lineage tracking, which are vital for regulated industries needing to prove data history.  

Its “Pre-screening wizard” acts as a high-speed filter, catching structural defects before they enter the processing pipeline. Large, SAP-centric organizations rely on this model-based approach to prioritize risks across complex, multi-layered environments.  

Testing & Validation Capabilities

Feature Qyrus Data Testing Tricentis Data Integrity

Comparison Testing

Source-to-Target Comparison ✓ ✓
Full Data Comparison ✓ ✓
Column-Level Mapping✓ ✓
Cross-Platform Comparison ✓ ✓
Reconciliation Testing ✓ ✓
Aggregate Comparison (Sum, Count) ✓ ✓

Single Source Validation

✓ ✓
Row Count Verification ✓ ✓
Data Type Verification ✓ ✓
Null Value Checks ✓ ✓
Duplicate Detection ✓ ✓
Regex Pattern Validation ✓ ✓
Custom Business Logic/Functions ✓ ✓
Referential Integrity Checks ◐✓
Schema Validation ◐✓

Advanced Testing

Transformation Testing ✓ ✓
ETL Process Testing ✓ ✓
Data Migration Testing ✓ ✓
BI Report Testing ✗ ✓
Tableau/Power BI Testing ✗ ✓
Pre-Screening / Data Profiling ◐ ✓
Data Lineage Tracking ✗ ✓

Qyrus Data Testing takes an agile path, focusing on most core validation tasks that drive daily business decisions. It provides unique value through Lambda function support, allowing teams to inject custom business logic directly into its automated data quality checks. This “TestOS” approach bridges the gap between different layers, enabling you to verify that a mobile app transaction accurately reflects in your cloud warehouse. While it currently skips BI report testing, Qyrus offers a faster, no-code route for teams wanting to eliminate the “garbage in” problem at the point of entry. 

Precision testing must move beyond simple row counts to secure your strategic truth. If your ETL data testing framework cannot see the logic within the transformation, you are only protecting half of your pipeline. 

Beyond the Script: Scaling Quality with Intelligent Velocity 

Automation serves as the engine that moves data quality from a reactive chore to a proactive strategy. Organizations that fail to automate their pipelines see maintenance costs consume up to 70% of their total testing budget. Modern teams now demand more than just recorded scripts; they need platforms that think. 

Tricentis utilizes a model-based approach that decouples the technical steering from the test logic, allowing for resilient automation that doesn’t break with every UI change. With over 100 API calls and native support for the entire SAP ecosystem, it fits seamlessly into the most rigid enterprise CI/CD pipelines. Its “Pre-screening wizard” further accelerates the process by identifying early data errors before heavy testing begins.

Automation and Integration  

Feature Qyrus Data Testing Tricentis Data Integrity

Test Automation

No-Code Test Creation ✓ ✓
Low-Code Options ✓ ✓
SQL Query Support ✓ ✓
Visual Query Builder ✓ ✓
Test Scheduling ✗ ✓
Reusable Test Components ✓ ✓
Parameterized Testing ✓ ✓

AI/ML Capabilities

AI-Powered Test Generation ✓ ✓
Auto-Mapping of Columns ✓ ✓
Self-Healing Tests ◐ ✓
Generative AI for Test Cases ✓ ✓

DevOps/CI-CD Integration

REST API ✓ ✓
Jenkins Integration ✗ ✓
Azure DevOps ✗ ✓
GitLab CI ✗ ✓
GitHub Actions ✗ ✓
Webhooks ◐ ✓

Issue & Test Management

Jira Integration ✓✓
ServiceNow Integration ◐✓
Slack/Teams Notifications ✓ ✓
Email Notifications ✓ ✓

Qyrus Data Testing counters with a heavy focus on democratization through Nova AI. This intelligent engine automatically generates testing functions and identifies data patterns, helping teams build test cases 70% faster than manual methods. Qyrus emphasizes a “no-code” philosophy that allows manual testers to contribute to the ETL data testing framework without learning complex coding languages. It integrates directly with Jira, Jenkins, and Azure DevOps to ensure that automated data quality checks remain part of every code push. 

True velocity requires a platform that minimizes technical debt while maximizing coverage. Whether you lean on Tricentis’ enterprise-grade models or Qyrus’ AI-powered speed, your ETL testing automation tools must remove the human bottleneck from the pipeline. 

The Digital Mirror: Transforming Raw Data into Strategic Intelligence 

Visibility acts as the final safeguard for your information integrity. Without robust analytics, even the most sophisticated automated data quality checks remain silent. Organizations that lack transparent reporting struggle to identify the root cause of data corruption, often treating symptoms while the underlying disease persists. 

Tricentis Data Integrity secures a perfect score for reporting and analytics. It provides deep-drill analysis that allows engineers to trace a failure from a high-level dashboard down to the specific row and column. This platform excels at Root Cause Analysis (RCA), helping teams determine if a failure stems from a physical hardware fault, a human configuration error, or an organizational process breakdown. Furthermore, it offers complete integration with BI tools like Tableau and Power BI, ensuring your executive reports are as verified as the data they display. 

Reporting and Analytics

Feature Qyrus Data Testing Tricentis Data Integrity
Real-Time Dashboards ✓ ✓
Drill-Down Analysis ✓ ✓
Root Cause Analysis ◐ ✓
PDF Report Export ✗ ✓
Excel Report Export ✓ ✓
Trend Analysis ◐ ✓
Data Quality Metrics ◐ ✓
Custom Report Templates ◐ ✓
BI Tool Integration (Tableau, Power BI) ✗ ✓
Audit Trail ✓ ✓

Qyrus Data Testing earns a 72% category score with its modern, real-time approach. Its dashboards focus on “Operational Intelligence,” providing immediate access to KPIs so you can react to changing conditions in seconds. Qyrus emphasizes automated audit trails to ensure compliance without manual paperwork. While its root cause and trend analysis features are currently in Beta, the platform provides the essential visibility needed for high-velocity teams to act with confidence. 

A real-time dashboard is not just a display; it is a tool that shortens the time to a decision. Whether you require the deep forensic reporting of Tricentis or the agile, live signals of Qyrus, your data quality testing tools must turn your pipeline into an open book. 

Fortresses and Clouds: Choosing Your Infrastructure Architecture 

Your choice of deployment model dictates the ultimate control you maintain over your sensitive information. Both platforms offer the flexibility of Cloud (SaaS), On-Premises, and Hybrid deployment models. However, the maturity of their security frameworks marks a significant divergence for regulated industries. 

Platform and Deployment

Feature Qyrus Data Testing Tricentis Data Integrity
Cloud (SaaS) ✓ ✓
On-Premises ✗ ✓
Hybrid Deployment ◐ ✓
Docker Support ◐ ✓
Kubernetes Support ◐ ✓
Multi-Tenant ◐ ✓
SSO/LDAP ✓ ✓
Role-Based Access Control ✓ ✓
Data Encryption (AES-256) ✓ ✓
SOC 2 Compliance ◐ ✓

Qyrus Data Testing earns a strong platform score by prioritizing modern, containerized workflows. The platform fully supports Docker and Kubernetes for teams that want to manage their ETL testing automation tools within a private, scalable infrastructure. It employs AES-256 encryption and Single Sign-On (SSO) for secure authentication. This makes Qyrus an excellent fit for agile, cloud-native organizations that value technical flexibility over legacy certifications. 

If your team demands a lightweight, containerized environment that scales with your code, Qyrus provides the modern edge. 

The Verdict: Architecting Your Truth in a Data-First World 

The decision between Tricentis Data Integrity and Qyrus Data Testing ultimately hinges on the scope of your quality mission. Both platforms eliminate the risk of manual error, but they serve different strategic masters. 

Tricentis Data Integrity provides an exhaustive, enterprise-grade fortress. It remains the clear choice for global organizations with complex, SAP-centric landscapes that require every possible certification and deep forensic validation. If your primary goal is risk-based prioritization and you manage a sprawling legacy footprint, Tricentis offers the most complete safety net on the market. 

Qyrus Data Testing counters with a vision for total platform consolidation. It functions as a specialized module within a broader “TestOS,” making it the ideal choice for agile teams that need to verify quality across Web, Mobile, and API layers simultaneously. Choose Qyrus if you want to empower your existing staff with AI-powered automation and move from pilot to production in weeks rather than months. 

Data quality is not a static checkbox; it is the heartbeat of your digital transformation. Secure your strategic integrity by selecting the engine that matches your operational speed. Whether you need the massive breadth of an enterprise leader or the unified agility of a modern TestOS, stop the $12.9 million drain today. 

Secure your data integrity now by starting a 30-day sandbox evaluation. 

Driving the Future of Quality Engineering

Empowering enterprises to accelerate testing with AI-native autonomy

We are proud to announce that Qyrus has been recognized as a Leader in The Forrester Wave™: Autonomous Testing Platforms, Q4 2025. As enterprises face the need for faster, more autonomous testing to keep pace with AI-infused application development, we believe this recognition shows our commitment to delivering a robust, AI-powered SaaS platform at scale.

How Qyrus Stacks Up

In this evaluation, Qyrus received the highest scores possible (5.0) in the following criteria:

  • Testing AI Across Different Dimensions
  • Testing RAG Pipelines
  • Level of Autonomous Testing
  • Roadmap
  • Pricing Flexibility and transparency
  • Testing Agentic Tool Calling
 

The report evaluated 15 top providers in the market.

Here is what the Forrester report had to say about Qyrus in its vendor profile:

  • Qyrus suits enterprises seeking advanced AI-driven testing, multiagent orchestration, and robust validation of GenAI outputs at speed and scale.
  • Qyrus excels in AI testing dimensions, using heuristics and LLM to judge faithfulness, relevance, and coverage.
  • Its Sense to Evaluate to Execute to Report (SEER) orchestration framework and excellent agentic tool calling result in an above-par
    score for autonomous testing.

From Vision to Validation: Hear from Our Leaders

Forrester does not endorse any company, product, brand, or service included in its research publications and does not advise any person to select the products or services of any company or brand based on the ratings included in such publications. Information is based on the best available resources. Opinions reflect judgment at the time and are subject to change. For more information, read about Forrester’s objectivity here .

SAP Testing

Your Blueprint for Certainty

Your SAP system is the heart of your enterprise, but every update brings a wave of uncertainty and risk. Flawed testing processes can lead to production failures, budget overruns, and delayed projects. It’s time to break the cycle. This exclusive whitepaper is your blueprint for de-risking your updates and building a resilient, AI-powered testing strategy.

Are You Facing These SAP Update Challenges?
  • Brittle Scripts: Constantly fixing automation scripts that break with every minor SAP Fiori UI change.
  • Data Bottlenecks: Struggling to get realistic, production-like test data, which leads to bugs being missed.
  • Endless Cycles: Watching manual regression testing consume over 30% of your project budget and still failing to provide adequate coverage.
  • The Expertise Gap: Finding that your business users can’t use traditional testing tools because they are too technical, creating a major bottleneck.
  • Constant Fear: Worrying that a single missed test scenario in your complex landscape could “spell disaster” for your business operations.
  • The 5 Fracture Points: A deep dive into the technical, data, and process-related issues that cause even well-planned SAP updates to fail.
  • Why Old Fixes Don’t Work: An honest look at why throwing more manual testers or legacy automation at the problem is a failing strategy.
  • The AI-Powered Solution: The complete blueprint for implementing a no-code, intelligent automation strategy that empowers your business users.
  • Real-World Proof: A case study showing how a leading automotive manufacturer reduced a complex testing scenario from 34 minutes to just 4—an 88% reduction in effort.
  • Actionable Metrics: Learn how to achieve 10x faster test runs and a 60x reduction in test data creation effort.

The Data Deluge

Are You Making Business Decisions Based on Bad Data?

Every minute, your enterprise data is in motion—flowing, transforming, and multiplying. But what if the data you rely on for critical decisions is flawed? You’re not alone. The hidden cost of poor data quality is staggering, leading to flawed analytics, misguided strategies, and an erosion of trust across the organization. The reality is, manual data testing is no longer enough. It’s slow, error-prone, and cannot keep pace with the velocity of modern data pipelines. Your business can’t afford to be reactive, fixing costly issues after they’ve already impacted your bottom line and reputation. It’s time to build a foundation of trust.
Download the Free Whitepaper to Learn:
  • The Alarming Financial and Strategic Costs of Poor Data Quality. Discover why bad data is a C-suite problem, costing businesses millions annually and hindering digital transformation.
  • The Executive Case for Automated Data Testing. Understand how automated data validation can save your company from critical errors, regulatory fines, and reputational damage.
  • The Qyrus Methodology for Unlocking Data Confidence. See how our AI-augmented, codeless platform simplifies complex data validation, ensuring consistency and integrity from source to destination.
  • A Proven Path to Data Trust. Get a step-by-step guide on how to implement Qyrus, from a risk-free 30-day sandbox evaluation to a full enterprise-scale integration.

Unlike traditional, code-heavy solutions, Qyrus gives you the power of intelligent automation. Our platform helps you:

  • Prevent Errors Before They Happen: Proactively validate data across all sources with precision and speed.
  • Streamline Your Workflows: Leverage a powerful, codeless interface that empowers business and QA teams alike.
  • Ensure Compliance and Auditing: Generate comprehensive reports and audit trails for regulatory peace of mind.

Is Your QA a Bottleneck?

Why Fragmented Tools Fail in the Age of AI

Software development has hit hyperdrive. AI coding assistants now contribute to as much as 67% of new code, creating a massive velocity gap that leaves traditional QA—and its fragmented toolchain—behind. While your developers accelerate, your testing processes are likely trapped by manual triage, endless script maintenance, and the complexities of managing multiple, disconnected tools.

Download this whitepaper to learn how to:

Is your F&B brand prepared for the seismic shifts in the industry? This playbook provides a strategic guide to implementing a unified, intelligent, and automated QA model.

Key Ingredients for QA Success

Overcoming the Digital Bottleneck

  • In the F&B sector, the percentage of fully automated testing activities is even lower than the cross-industry average of 15% due to compliance and legacy systems.
  • This leads to significant consequences like delayed releases, high costs from quality failures, and inconsistent test coverage.
  • The gap between digital ambition and testing readiness is growing, creating risks across product launches and ERP upgrades.
  • Most current QA environments are manual and fragmented across platforms like SAP (ERP), mobile, and APIs. 
  • This results in delayed releases, poor audit traceability, and increased risk during system updates.
  • To stay competitive, F&B leaders must treat QA as a strategic and scalable function that has a cross-functional impact.
  • Empower your business and QA teams with agentic, no-code test automation across Web, Mobile, API, and Backend.
  • Accelerate testing for SAP using pre-built accelerators with F&B-specific workflows and integrations.
  • Achieve real-time visibility by testing complete processes, from mobile ordering to ERP fulfillment, with end-to-end test orchestration.
  • See how a leading U.S. F&B distributor transformed its operations by modernizing its QA. With over $40 billion in annual revenue, they delivered higher-quality digital experiences without compromising speed.
  • They overcame manual bottlenecks and slow testing cycles by using codeless automation to accelerate test creation and regression.
  • They addressed resource strain by transitioning manual testers into automation contributors, which boosted test velocity.
  • They achieved 90% test coverage across critical scenarios and implemented 100% reusable automation for Web, Mobile, SAP, and Salesforce applications.

If there’s one thing developers, testers, and SDETs will agree on in 2026, it’s this: API automation is no longer optional.

A API automating testing strategy is a plan that ensures the speed and reliability of your APIs , the goal is to identify high-intent issues that are most likely to hurt once the team and application grows. Whether you’re building microservices, mobile apps, or enterprise backend systems, automating your API testing process will be the most promising move you make and help you clear issues much faster.
API Testing Issues

  Across Reddit, StackOverflow, and Quora, the same complaints appear repeatedly:

• “How do I easily import and automate my existing API tests?”

• “What free tools can I trust for automation or load testing?”

• “How do I connect backend API testing with front-end workflows?”

This guide answers those exact questions — with real forum insights, practical workflows, tool comparisons, and how qAPI fits into modern testing stacks.

API Automation Testing Is Essential

On Reddit’s r/softwaretesting, a user recently posted: “My team spends 30% of every sprint manually testing the same API endpoints. We’re moving slow and still finding bugs in production. Is this normal?”

The answer is: it’s common, but it’s not normal.

What users get wrong is that API automation isn’t just about “testing faster.” It’s about building a safety net that allows your team to work efficiently.
API Testing

One Quora answer explains it best:

• Manual API testing = exploratory, ad hoc

• API automation = consistent, repeatable, CI/CD-friendly

This distinction matters because teams that rely only on manual tests are shipping blind. If we compare it to the release velocity teams globally are working towards, that’s a deal-breaker.

The transition from manual-heavy testing to API-first automation isn’t just a surfacing now; it’s a response to deep architectural and workflow changes happening across the software industry for more than a decade.

1️⃣ Microservices Usage are Exploding  

Current systems we develop and use are no longer monolithic. They’re divided into dozens or hundreds of microservices, and every service exposes multiple APIs. Which clearly means:

More endpoints, More integrations, More dependencies, More failure points

A single release can impact 15–30 upstream or downstream services — something manual testing cannot reliably validate. So, it’s just poetic that API testing automation becomes the only scalable way to maintain confidence across distributed systems.

2️⃣ CI/CD Pipelines Demand Fast, Stable Feedback

Companies are moving toward high-frequency deployments, and CI/CD pipelines expect tests to run faster without any human intervention.

Manual API tests simply do not fit into the CI/CD loop.

3️⃣ AI-Generated Code Introduces New Types of Hidden Risk

With Copilot, Replit AI, Lovable, and LLM-based code generation tools everywhere, teams are shipping more code, faster — but not always more reliable code.

AI-generated functions often introduce:

• unhandled edge cases

• silent schema drift

• subtle regressions

• missing validation logic

Without an API testing automation tool, these issues will show up late in QA or worse — in production.

4️⃣UI Tests Can’t Handle Modern Complexity 

Teams everywhere have learned the hard way that relying on UI tests for backend validation leads to slow execution and late-stage bug discovery.

As systems become more distributed, UI tests reveal symptoms, not root causes. API tests go deeper by validating logic at the source, reducing the cost and complexity of debugging.

API Load Testing Methods — What Users Ask & Need

Performance testing is one of the most searched API topics on Reddit’s r/devops and r/softwaretesting.

We saw the recurring questions:

❓ “How do I simulate 1k–50k virtual users?”

❓ “What’s the best way to integrate load tests into CI/CD?”

❓ “How do I track p95 / p99 latency under heavy traffic?”

Traditional vs Modern Load Testing 
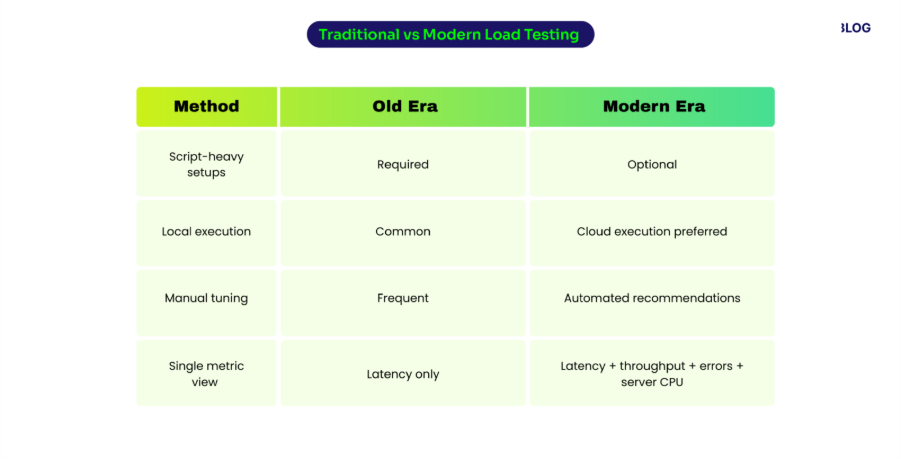
Traditional vs Modern Load Testing

Users often confuse peak vs spike load (a top-ranking question on multiple forums).

• Peak load = sustained high traffic

• Spike load = sudden unexpected traffic burst

Load testing is no longer optional— it’s essential for mobile-heavy APIs, fintech apps, e-commerce, and B2B SaaS workflows.

The Import Advantage — The Fastest Way to Kick-Start API Automation

When teams search for the best import API testing tools for software testing, they’re all looking for the same thing: “How do I move fast without rebuilding everything from scratch?”

And honestly, that’s the biggest psychological barrier in API automation today.

You’ll see it everywhere on Reddit, Slack groups, and testing forums — people frustrated because they’ve already built hundreds of requests inside Postman, Swagger, or cURL… and now every “new tool” expects them to rebuild those tests manually.

That’s not just tedious. It’s demotivating. It’s why so many teams delay automation for months.

Import-based automation tool qAPI eliminates that.

Why Import Features Matter More Than Ever in 2025

Currently, teams don’t have the time and bandwidth to start from zero. They need automation now — and the fastest path is through smart importing.

“How do I import Postman or Swagger collections directly into my automation tool?”

This is the #1 question asked across Quora, Reddit, and Stack Overflow.

Today’s API automation testing tools come with native import support. You upload a Postman file, OpenAPI spec, Swagger doc, or even a cURL snippet — and the tool instantly generates your test suite.

“Can I re-use existing API tests without manual reconfiguration?”

This is where great tools stand apart from the merely “popular import API testing tools.”

Basic import = list of endpoints. Smart import = usable, runnable workflows.
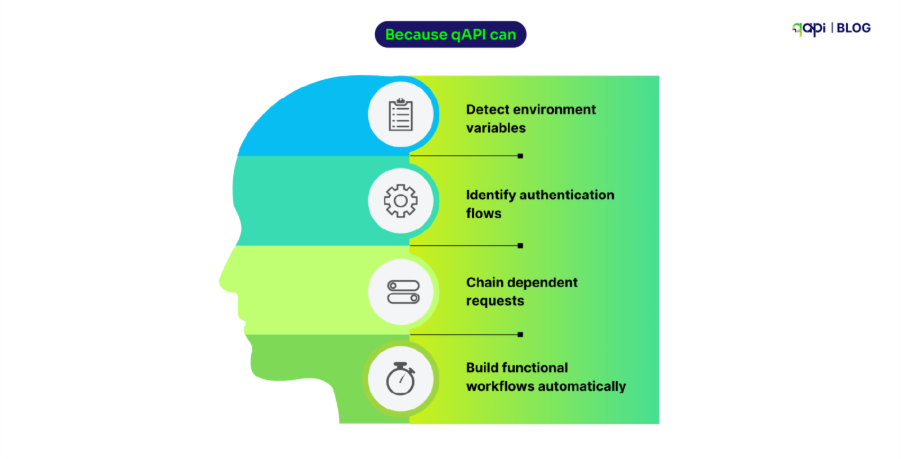
qAPI Features

Because qAPI can:

• Detect environment variables

• Identify authentication flows

• Chain dependent requests

• Build functional workflows automatically

This is why testers say importing API specs cuts setup time by up to 60%.

And that’s why qAPI’s import features are now the defining safeguards of the best import API testing tools for software testing.


Why Import + Automation = A Strategic Advantage

Importing clubbed along with Automation it’s what makes large-scale API automation realistic for small and large teams alike.
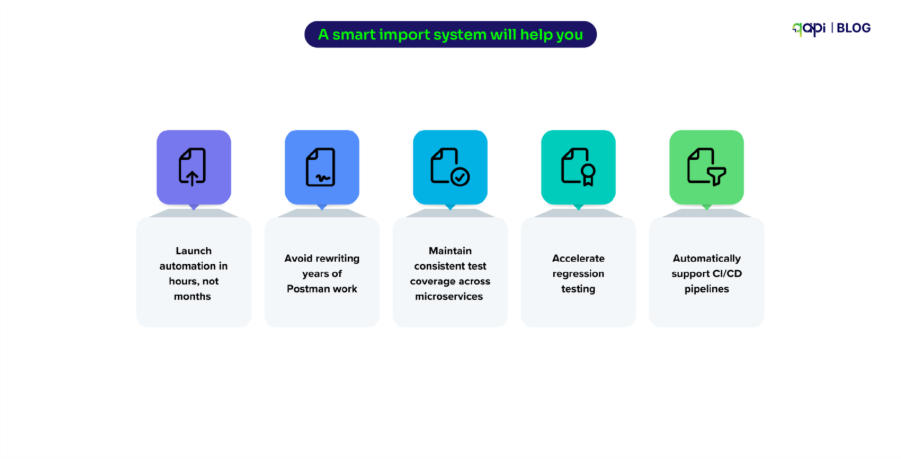
Smart Import System

A smart import system will help you:

• Launch automation in hours, not months

• Avoid rewriting years of Postman work

• Maintain consistent test coverage across microservices

• Accelerate regression testing

• Automatically support CI/CD pipelines

For busy QA teams, this is the difference between falling behind releases and being ahead of them.

How You Should Solve the Biggest User Pain Points

Every pain point testers mention online led to a specific design choice in modern platforms — especially unified, smart-import tools. Here are some of the major one’s that will help you out.

Pain Point #1: “I’m a manual QA, and I don’t know how to code.”

Many subscribers say this is what stops them from trying automation.

The Solution: Use a 100% no-code visual builder where workflows feel more like user journeys than scripts. If you can describe a scenario, you can automate it.

Pain Point #2: “We have years of Postman collections. Migration will take forever.”

This is the fear that blocks API automation from even starting.

The Solution, Import everything in qAPI:

• Postman

• OpenAPI

• Swagger

• cURL

• JSON definitions

AI converts those imports into clean, maintainable workflows — in minutes, not weeks.

Pain Point #3: “We use one tool for functional tests and another for load tests.”

This fragmentation is one of the most common frustrations in online communities.

The Solution: qAPI is a unified platform where you can:

1️⃣ Build a functional test

2️⃣ Add virtual users

3️⃣ Instantly turn it into a load test

One workflow. Multiple testing modes. Zero duplication.

This solves a major market gap that current tools miss and aligns perfectly with how fast paced engineering teams work.

Why This Matters for You

If you’re a QA lead, tester, or developer, here’s the real benefit:

You finally get time back. You finally get clarity. You finally get automation that feels doable, not daunting.

With qAPI the Import capabilities remove the intimidation factor from API automation. Unified workflows eliminate juggling multiple tools. And the No-code features remove the fear of getting left behind.

This is why testers today look specifically for:

• API automation testing tools with strong import support

• Popular import API testing tools that reduce setup time

• API load testing methods that reuse the same workflows

Free import API testing tools for software testing to get started quickly

The industry is shifting. Tools are evolving. So is qAPI to help with your growing needs And teams that adopt import-first automation gain speed, consistency, and quality — all without burning out their testers.

How qAPI Solves the Biggest Pain Points

Based on Reddit threads and user conversations, qAPI stands out for solving:

1️⃣ No-code automation workflows

Testers without scripting expertise can automate and build end-to-end flows.

2️⃣ Full import support

Postman, Swagger, OpenAPI, Insomnia, cURL — all in one platform.

3️⃣ Integrated load testing

You can start with free virtual users, analyze p95/p99 latency, and correlate client and server metrics. You can refine your testing further by adding as many virtual users as you can.

4️⃣ AI assistance

Generate tests, validate responses, detect missing parameters, catch schema drift.

5️⃣ Unified dashboards

Automation + load + regression all in one place. Users get detailed information for each and every test they run helping them understand the API performance stretched over a period of time.

Conclusion: Why qAPI Is Built for 2025 API Automation Needs

Here’s what the teams in API landscape in 2025 demand for:

• Faster releases

• Scalable automation

• Powerful load testing

• Seamless imports

• AI-assisted efficiency

Whether you’re migrating Postman suites, handling high-traffic microservices, or scaling test automation across teams, qAPI unifies everything — import, automation, load, and AI — in a single platform.

It’s built for testers who want to do more with less friction. It’s built for devs who want CI/CD-ready pipelines. It’s built for teams who want a true API-first testing strategy.

FAQs Inspired by Real Searches on Reddit, Quora & StackOverflow

1️⃣ How do I automate API regression tests using Postman imports?

Import your Postman collection → auto-generate test suites → configure assertions → schedule runs in CI/CD. qAPI supports this.

2️⃣ Are AI-based API automation helpers reliable?

AI-based assistants excel at generating tests, identifying missing assertions and detecting schema changes. They’re not perfect, but with qAPI, you can drastically reduce manual effort.

3️⃣ How do I troubleshoot flaky API load tests?

Check dynamic parameters, rate limiting, server throttling and environment instability. qAPI can visually correlate error spikes with server metrics to isolate root causes faster.

4️⃣ How do I schedule imported API tests in CI/CD pipelines?

Two options:

• CLI/automation runner tools

• Native CI plugins (GitHub Actions, GitLab, Jenkins)

Most modern AI-driven platforms, including qAPI, provide both.

Women reviewing testing features

Greetings, testing enthusiasts! In this special edition of Feature Friday, 2023 Wrap-Up, we’re diving into Qyrus’s latest testing features that are set to redefine the future of test automation. Join Tim and Adhiraj as they unravel core testing features of Qyrus rolled out throughout the 2023 year, showcasing the integration with GitHub, TestRail, XRay, Teams/Slack, CLI Commands, and introducing AI-enhanced tools like Rover, Qyrus Bot, Qyrus-GPT Plugin, API Discovery Tool, and NOVA. We’ll explore how these innovations align with the latest software quality assurance trends, bringing you the cutting-edge in test automation.

New Integrations

Github
GitHub Integration on Qyrus is one of the testing features that aims at seamlessly merging version control into Qyrus Mobility. It’s targeted towards users well-acquainted with GitHub, allowing them to push and pull scripts effortlessly, enhancing control and organization. Read more about this integration here.

TestRail
TestRail is a test case management software that can now get data from Qyrus test reports. Once a Qyrus test report is finished, it is created or updated in the TestRail test case. This integration is a game-changer for TestRail users. Read more about this integration here.

XRay
The Xray integration is an out-of-the-box integration that provides a link between your Xray issues and your Qyrus test scripts. Upon execution of these test scripts, the results are then populated straight to Xray to view execution results and updates from a single platform. Read more about this integration here.

Teams / Slack
Email notifications are already a thing on Qyrus, but we all know how bloated our inboxes can get. Getting notifications to your Slack or Teams channels is much more convenient as a whole. That way, entire teams or multiple stakeholders can be notified instantly about test results. And lastly, if someone has those messaging apps on their mobile devices, they’ll also get these notifications on the fly. Read more about this integration here.

CLI Commands
CLI commands allow users to interact with, inspect, or execute automated test scripts without visiting the Qyrus UI. With a range of pipeline integrations out of the box and webhooks for required custom integration, these packages allow a range of functionality without ever leaving the pipeline enabling Qyrus to execute in the background. Our CLI commands package is constantly being updated to add more functionality. Qyrus now has the capability to trigger executions across API tests without having to access the UI. Read more about our CLI commands here and check out our recent updates.

New AI-Enhanced Tools and Features

Rover
Rover AI is another one of our innovative ideas for automation testing that’s come to life. It is a tool that explores your mobile application and provides an activity map at the end of all possible user journeys that can take place on the application. Given that activity map, users can then build tests off of it. Simply clicking each node on the map – or each screen – the user can build out a test script for their mobile applications at lightning speeds. Read more about Rover AI, one of our incredible testing features, here.

Qyrus Bot
Qyrus Bot is an advanced chatbot that simplifies the entire testing process by offering a range of testing features that help users create, run, schedule, and manage tests with ease. With Qyrus Bot, users can create tests using natural language, without the need for technical expertise. Read more about how Qyrus Bot works here.

Qyrus-GPT Plugin
Qyrus has made its first ChatGPT plugin that works for testing. The plugin can build, create, and execute test scenarios by simply providing a URL to your web application. It helps the user to quickly build tests by analyzing the web application’s structure and behavior. It then can do things like suggest new scenarios for the user to build upon. Then, it can run all of those with the Qyrus test engine. Read more about Qyrus’ GPT plugin here.

API Discovery Tool
The API Discovery Recorder is a generative, AI-powered extension that tracks APIs that can be critical to the functionality of your web application. It helps the user quickly build API tests and generate assertions by simply browsing the web application locally on your machine. Read more about how the API Discovery Tool works here.

Nova
NOVA stands at the forefront of test automation innovation. A few of its capabilities are reading JIRA tickets, JIRA integration, and analyzing the requirements mentioned in the ticket. It can then automatically generate functional test scenarios from what it has analyzed. This helps to ensure that the delivered functionality of the application matches expectations and requirements. Oh, and if you don’t know how to write functional test scenarios, NOVA is there to lend a helping hand! Read more about our AI-powered NOVA tool here.

Overall Improvements to the Platform

Web / Mobility API Calling
Well, for starters, the idea behind this is to enable testers to build out more complex and comprehensive test scripts to help increase test coverage. Basically, a user is able to configure an API call to be made during the test script execution and then use that response data in the next part of the test. Read more about how this works here.

Step Functions
A user can reuse existing steps from a previous test script in a new test script. They don’t need to recreate the same steps in their script and can directly use what they already created. It allows users to maintain the test scripts easily. If a user makes an edit in one location, all locations using these steps will be updated. Especially for big test scripts, maintenance times can be exponentially reduced with this as one of Qyrus’ many testing features. Learn more about step functions here.

Salesforce Web Recorder Updates
Qyrus’ Salesforce Web Recorder in Web Testing has received exciting updates that we’re thrilled to share with you. These enhancements allow users to efficiently record and automate test scenarios within the Salesforce platform with more ease. Recording test scenarios becomes a breeze, eliminating the need for manual and error-prone processes. We’ll discuss how these updates benefit testers, developers, and organizations as a whole. Read more about how our web recorder handles Salesforce testing here.

Quick Imports
The quick imports feature enables users to fill out an Excel or JSON file, and as long as it is in the proper format the files can be imported into Qyrus and automatically built into executable test scripts. This feature truly simplifies test building and gives users another, streamlined test-building option. Whether it is making test building accessible to personas across the QA cycle or allowing targeted testers to build, save, or maintain scripts while offline or in transit, using a local environment, or having a strong familiarity with JSON or Excel. Read more on this topic here!

Updates to Test Building on Mobility
There has been a range of additions to mobile test building that make the process even simpler and more efficient. As you know, Qyrus is built on action types and therefore new ones are constantly being added to ensure steadfast and efficient testing. One of the most recently impactful is tap by Relative Coordinates. This testing feature assists in tapping on elements that cannot be located by normal means. There is a range of reasons elements can be difficult to locate and when the desired elements cannot be found with inspect mode, tapping by Relative Coordinates fixes these problems by taking a user-defined percentage of the element to locate it on the screen. In essence, this allows users to use any unique part of the element to locate it. Read more on how Qyrus has updated its test building on Mobility here!

Updates to API Process Test Building
The new way to build API Process tests is out! It offers a new perspective on chaining or stitching together the APIs to make the process test itself. Previously, we would chain the APIs together and go to a new screen to configure the connections, but now it’s all seamlessly built together on the same page. Read more about how Qyrus has updated its test building on API Process testing here!

And there you have it, the grand finale of the 2023 Feature Friday year! Qyrus has not just introduced testing features; it’s unleashed a testing revolution. From seamless integrations to AI-powered tools, Qyrus is setting the stage for the future of test automation. These innovations aren’t just about today; they’re about staying ahead of software quality assurance trends. Get ready to elevate your testing game with Qyrus!